On this page
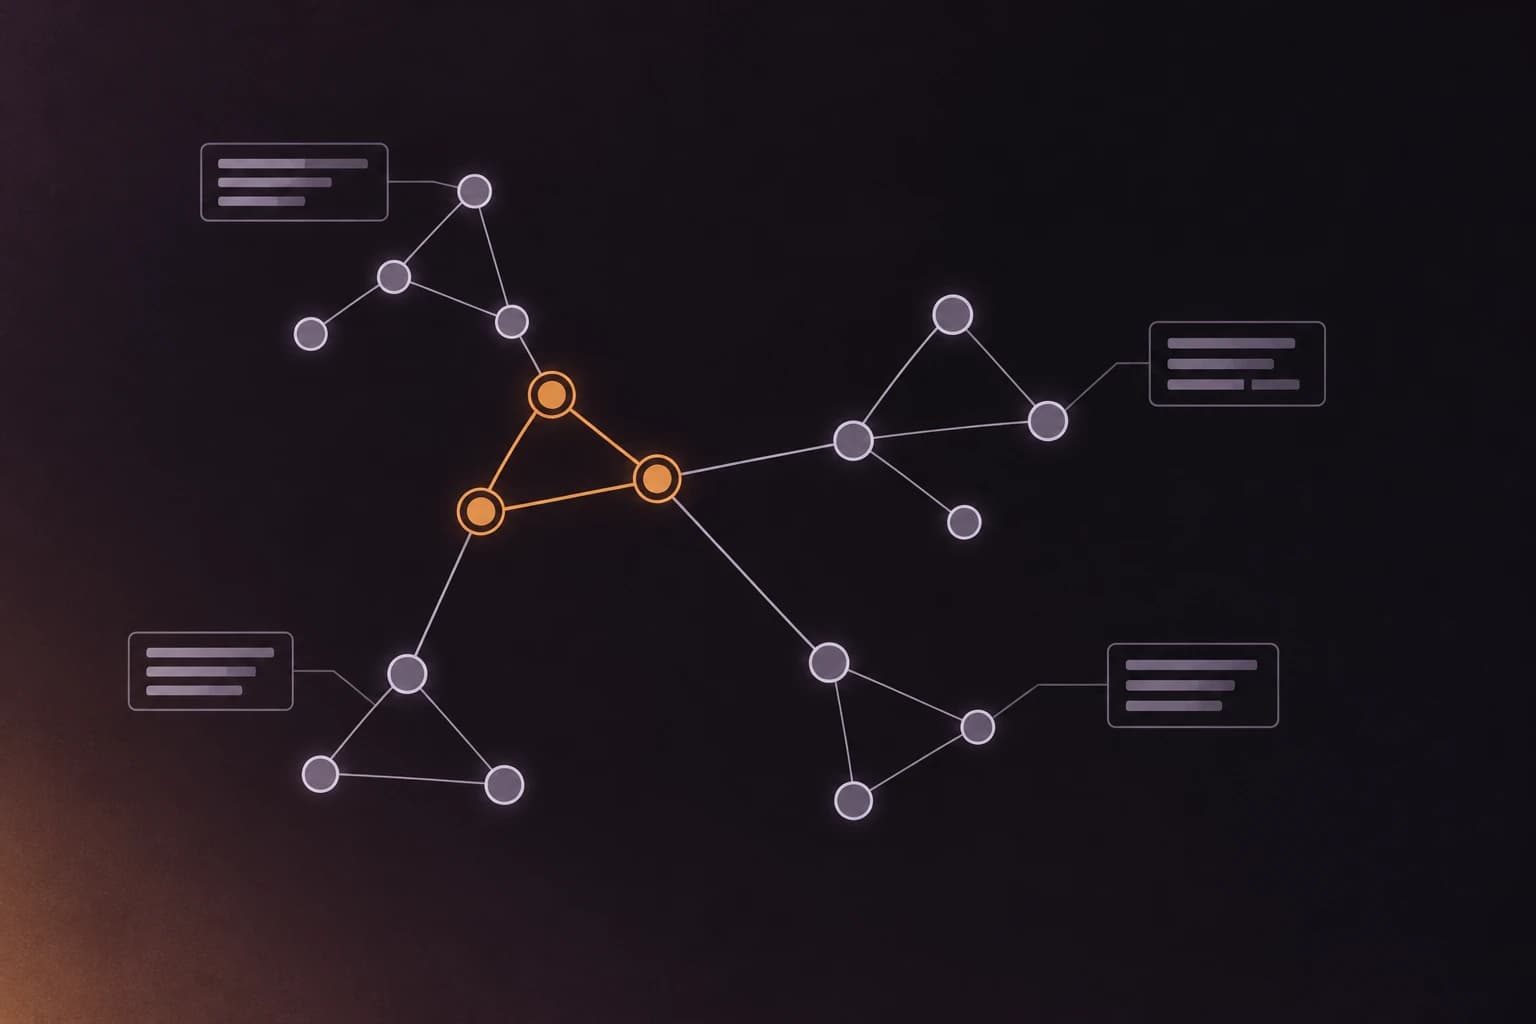
Hidden coupling is a pair of files that keep changing in the same commits although neither imports the other. Find it by running git log --name-only, counting file pairs per commit, and keeping only pairs that clear a minimum count and a minimum share of each file's commits. Imports describe what the code declares. Co-change describes what the team actually has to touch, and the gap between the two is where missed edits and stale contracts come from.
Part of the git intelligence guide.
What is hidden coupling?
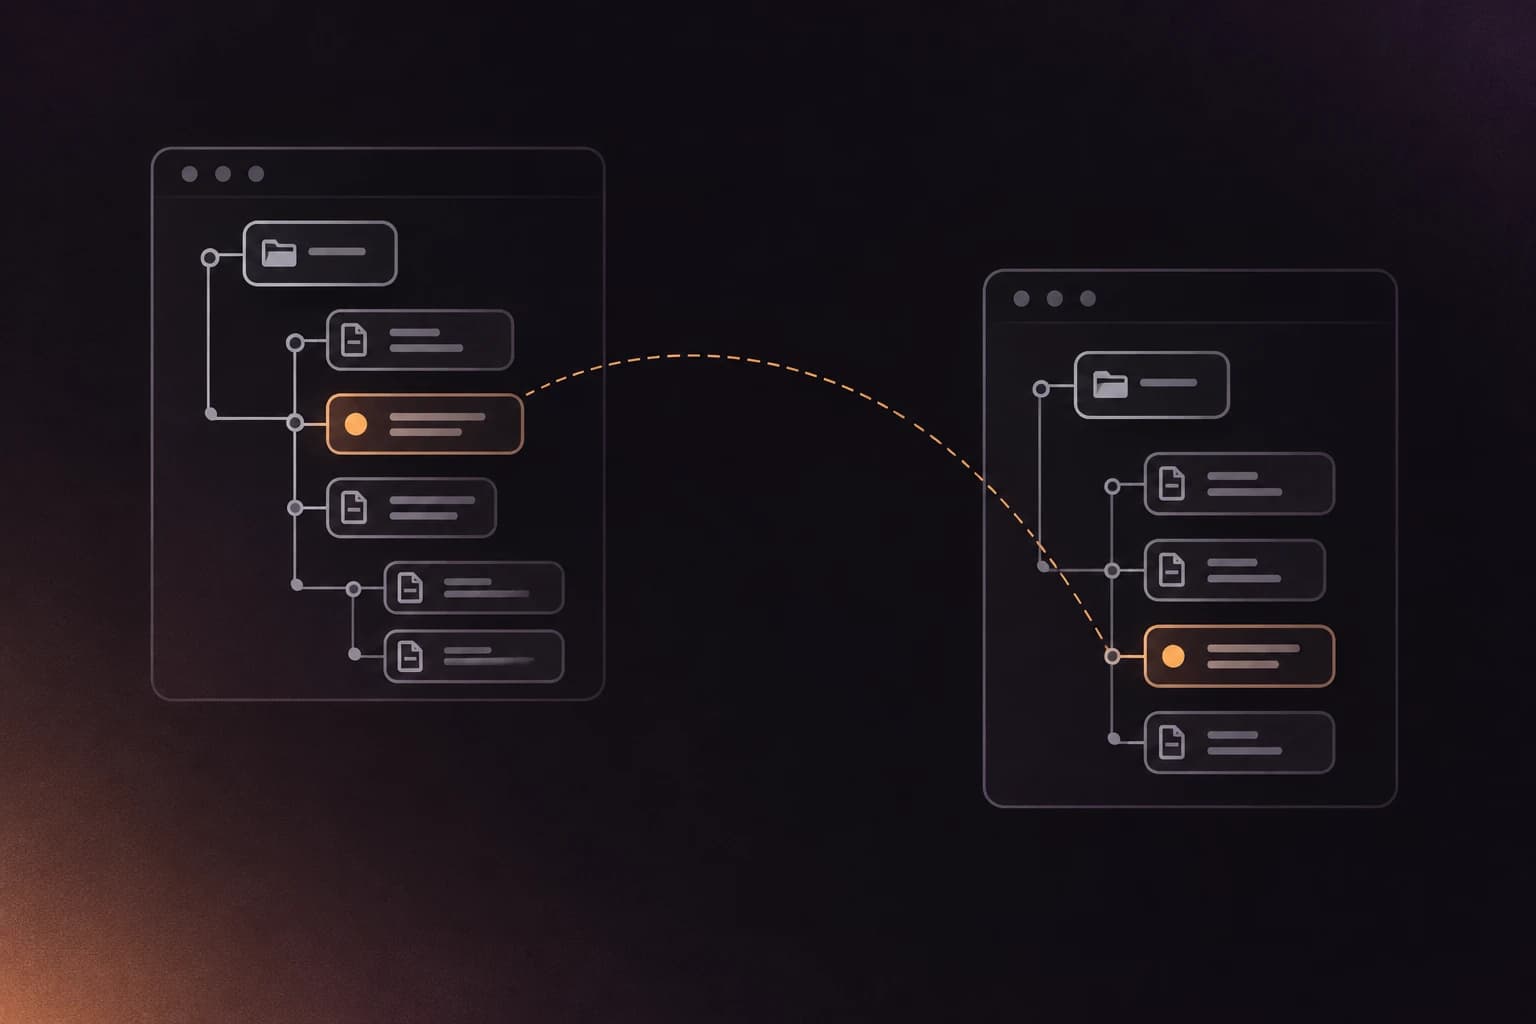
Hidden coupling, also called logical coupling or temporal coupling, is a relationship that exists in version history but not in the code's structure. A route handler and a schema file that always ship together, a config parser and the file that documents its keys, a client and the server DTO it mirrors: each pair encodes one rule in two places.
The idea has an academic lineage. Zimmermann and colleagues showed in Mining Version Histories to Guide Software Changes that association rules over commits expose couplings that program analysis cannot see. Adam Tornhill's temporal coupling analysis in CodeScene popularised the same measure for practitioners. The method is old and well tested. What changes between tools is how they filter noise.
How do you find files that change together?
Group files by commit, count every unordered pair, and rank by how often the pair appears relative to each file's own history. The script below does that with the standard library only.
import subprocess
from collections import Counter
from itertools import combinations

MAX_FILES = 50      # skip sweeping commits (renames, formatting, vendor syncs)
MIN_SHARED = 5      # absolute floor: small samples mislead

log = subprocess.check_output(
    ["git", "log", "--no-merges", "-n", "2000", "--name-only", "--format=@@commit"],
    text=True,
)

pairs, commits = Counter(), Counter()

def flush(files):
    files = sorted(set(files))
    if 1 < len(files) <= MAX_FILES:
        for f in files:
            commits[f] += 1
        for a, b in combinations(files, 2):
            pairs[(a, b)] += 1

files = []
for line in log.splitlines():
    if line == "@@commit":
        flush(files)
        files = []
    elif line.strip() and not line.endswith((".lock", ".md")):
        files.append(line.strip())
flush(files)

for (a, b), n in pairs.most_common():
    share = n / min(commits[a], commits[b])
    if n >= MIN_SHARED and share >= 0.5:
        print(f"{n:3d} shared  {share:.0%}  {a}  <->  {b}")
Run it from the repository root. Each line reads "this pair appeared in N commits, and that is X% of the less-active file's commits".
Which thresholds keep it honest?
Three filters decide whether the output is useful: commit size, an absolute count, and a share of each file's own history.
| Filter | Why it matters | Starting value |
|---|---|---|
| Skip merges and commits touching many files | A rename, formatter run or vendor sync pairs every file with every other | Drop commits over 50 files |
| Minimum shared commits | A pair that appears twice is a coincidence | 5 |
| Share of the less-active file's commits | Frequency alone ranks busy files first; the share ranks coupled files first | 50% or more |
| Window | Too short reacts to one sprint, too long keeps retired architecture | The last 1,000 to 2,000 commits |
Scroll the table sideways to see every column.
Frequency alone produces false positives, which is why the share matters. A file that changes in 40 commits will pair with many partners by chance. A pair that accounts for 80% of the smaller file's commits is not chance.
How do you tell hidden coupling from ordinary coupling?
Compare each pair with the import graph. A pair with an import edge is normal dependency flow: when the callee's signature changes, the caller changes. A pair with no edge is the finding. Also set aside pairs that are expected to move together, such as handler.py and test_handler.py.
What the surviving pairs usually turn out to be:
| Pattern | Likely cause | Next move |
|---|---|---|
| Client file and server DTO | Contract mirrored by hand | Generate one from the other, or share a schema |
| Parser and the file listing its options | Two sources of truth | Derive one from the other |
| Two modules in different directories | Boundary drawn by folder, not responsibility | Merge, or move the shared rule into a library |
| Source file and a distant fixture | Fixture encodes behaviour | Pin the contract with a test |
Scroll the table sideways to see every column.
How does repowise detect hidden coupling?
repowise walks git history once at index time, records co-change pairs for every tracked file, and labels each pair by whether the dependency graph explains it. Pairs are weighted by recency, so a coupling that stopped long ago fades instead of lingering. Commits that touch hundreds of files are skipped as noise, and each file keeps its strongest partners. The walk depth and minimum count are configurable under git.co_change_commit_limit and git.co_change_min_count, and no model key is needed.
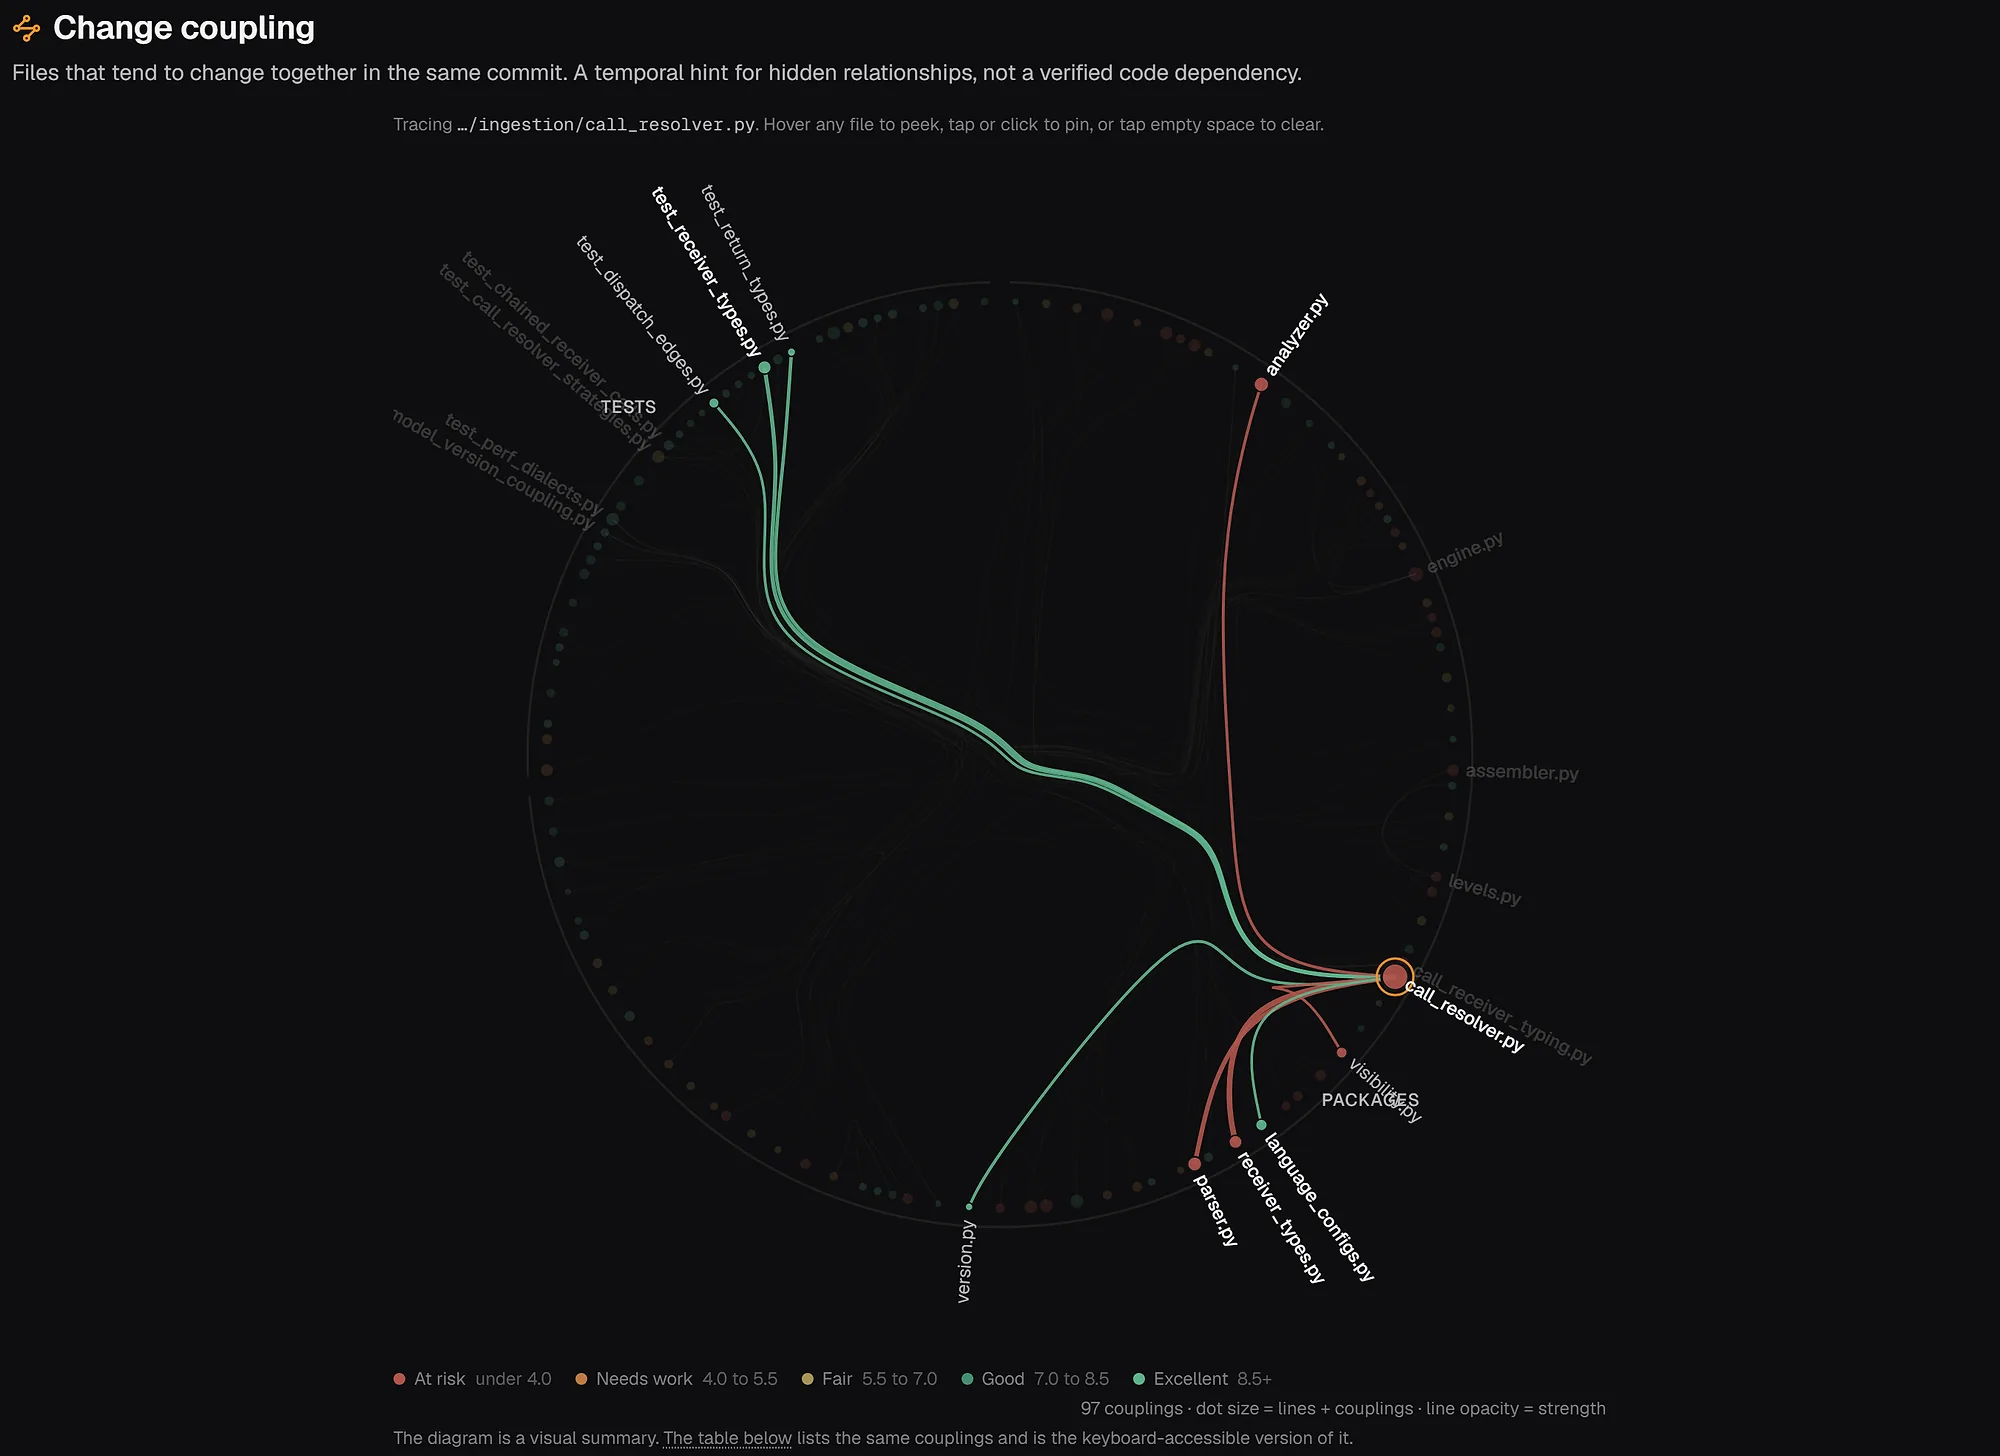
The Coupling view on the repowise repository: call_resolver.py traced to the test files and source modules that move with it. Line opacity is strength.
The same data is read in four places:
get_contextandget_riskreturn each file'sco_change_partners, withsupport(shared commits),conf_ab(the share of the file's commits that also touched the partner) andhas_import_link, so the hidden ones are one filter away. See the MCP tools reference.- The code-health layer includes a hidden-coupling check. It fires when two files clear a commit floor, share at least half of the smaller file's commits, the graph does not explain the pair, and the pair is not a test and its source. Severity stays at medium until a pair has eight or more shared commits, because small samples oversell confidence. See code health.
repowise riskandget_riskwithchanged_fileslead with adirectivewhosemissing_cochangesfield names the files that historically change with your diff and are not in it. See change risk.repowise overlaplists other open branches editing the same files, and the co-change partners of your files that they edit.
repowise init
repowise risk main..HEAD     # includes missing co-changes for the range
repowise overlap             # other branches touching the same files or their partners
How do you use it in review?
Treat a strong co-change partner missing from the diff as a question, not a verdict. If the change touches the shared contract, the partner needs an edit or a line in the PR description explaining why not. If the change is local, the note is enough. The repowise PR bot puts this in the review comment, so the author sees the missing partner before a reviewer has to remember it.
For agents the same information arrives before the edit: the partner list comes back with get_context, so an agent changing auth.ts is told that middleware/session.ts has historically moved with it. In a workspace of several repositories, cross-repo co-change flags the backend and frontend files that drift together.
What should you do with the findings?
Work the list top-down, and treat each pair as a design question.
- Make the shared rule explicit. If two files mirror a contract, generate one from the other or move the rule to one module.
- Pin it with a test. A contract test turns silent drift into a failing build.
- Redraw the boundary. If a pair appears in every refactor, the module split follows folders, not responsibilities.
- Add both owners to review. A pair that crosses team lines is usually a knowledge silo; see code ownership and bus factor.
- Watch the trend. One pair is harmless. A file that keeps gaining partners is a hotspot in the making; see git hotspot analysis.
Pitfalls
Most false positives come from five sources.
- Mechanical commits. Renames, formatter runs, lockfile bumps and vendor syncs. Filter by commit size and file type.
- Small samples. Two shared commits is not a pattern. Require a floor before trusting a ratio.
- Squash merges. A squashed PR records one commit for many logical changes and inflates pairs. Compare against a window of unsquashed history if you can.
- Test and source pairs. Expected, not hidden. Exclude them.
- Files with no import edge by nature. Changelogs, manifests and docs carry no edge in either direction, so their absence from the graph proves nothing.
Co-change is evidence of a relationship, not proof of a dependency. repowise keeps it out of its dependency-importance ranking for exactly that reason and shows it as its own layer.
FAQ
- What is hidden coupling in code?
- Hidden coupling is a relationship between files that repeatedly change in the same commits even though neither imports the other. It shows up in git history rather than in the dependency graph, and it usually means a contract, data shape or rule is duplicated across the two files.
- How do I find files that change together in git?
- Run
git log --no-merges --name-only, group file names by commit, and count every pair. Drop sweeping commits, require a minimum shared count, and rank by the share of each file's commits the pair accounts for. The script above does this in about twenty lines. - What is the difference between logical coupling and static coupling?
- Static coupling comes from the code: imports, calls and inheritance. Logical coupling, also called temporal or evolutionary coupling, comes from history: files edited together. Logical coupling finds links that static analysis cannot, such as duplicated constants, mirrored schemas and shared conventions.
- How accurate is co-change detection?
- It is a strong hint and not a proof. Thresholds on commit size, shared count and share of history remove most noise, and comparing with the import graph removes the expected pairs. A human still decides whether a surviving pair is a design problem.
- Should a missing co-change partner block a pull request?
- No, not by default. A missing partner is a prompt to check that the other file does not need the same edit. When the change really touches the shared contract, the PR should include the partner or explain why it does not.
- Can hidden coupling span repositories?
- Yes. Backend and frontend repositories often drift together through shared APIs. In workspace mode, repowise combines the graph with co-change across repositories and reports missing cross-repo co-changes in the PR directive.