On this page
- Quick answer: the five questions
- Why refactoring plans go stale
- How do you score impact per effort?
- Impact: how much future pain goes away
- Effort: how long and how risky
- Compute the priority
- What does a good first-quarter target look like?
- Refactor or rewrite?
- How does repowise rank refactoring targets automatically?
- Using it from an agent
- Pitfalls
- Keep the backlog useful
- FAQ
To decide what to refactor first, score each candidate on impact (how much future pain it removes) and effort (how long and how risky the change is), then start with the highest impact per effort. The winners are usually not the ugliest files. They are active code on a path many changes touch, with a clear seam to cut along. repowise health --refactoring-targets produces that ranking from your dependency graph and git history, and this guide shows how to do the same by hand.
Part of the code health guide.
Quick answer: the five questions
A refactor belongs near the top of the list when four of these five answers are yes. Ask them of every candidate before you estimate anything.
| Question | Why it matters | What to look for |
|---|---|---|
| Will this code change again soon? | Refactoring pays back on future edits | Active feature area, recent bug fixes |
| Does it cause repeated pain? | Pain is evidence, not a feeling | Slow reviews, regressions, fragile tests |
| What is the blast radius? | High fan-out means high leverage | Many importers, shared utilities |
| Can I make it safe first? | Safety lowers effort | Tests, a seam to extract along |
| Can I finish in a short, reviewable slice? | A small slice gets merged | Clear boundary, one owner |
Scroll the table sideways to see every column.
If the answer to the first question is no, stop. Martin Fowler's guidance is to refactor as part of real work, so stable code nobody edits is the wrong place to spend a week.
Why refactoring plans go stale
Plans go stale when they are written as a wish list instead of a ranking. "Simplify auth" and "remove duplication" do not say what to touch this week or what to ignore.
Two habits cause it. Teams optimize for how code looks, so a tidy-looking file nobody edits gets the same attention as a messy one on a hot path. And teams treat refactoring as a separate project, which loses to feature work every sprint. Fowler's answer is opportunistic and preparatory refactoring: small improvements attached to the bug fix, feature or upgrade already in flight.
CodeScene describes the same targeting logic: focus on modules where low code health overlaps with high change frequency, because that combination correlates with defects (as of October 2026). Change frequency decides whether a smell is worth fixing.
How do you score impact per effort?
Score impact and effort from 1 to 5 on five signals each, then divide. A whiteboard and a spreadsheet are enough for the first twenty candidates.
Impact: how much future pain goes away
| Signal | 1 | 3 | 5 |
|---|---|---|---|
| Change frequency | Rare | Monthly | Weekly or more |
| Blast radius | Few importers | Some | Many importers, shared hub |
| Bug history | None | Occasional | Repeated fixes in the same place |
| Incident involvement | None | Mentioned once | In postmortems or on-call notes |
| Knowledge concentration | Broad | Partial | One person understands it |
Scroll the table sideways to see every column.
Git history answers three of these rows without opinion: how often a file changes, how many fix commits touched it, and who owns it. Dependency fan-out comes from the import graph.
Effort: how long and how risky
| Signal | 1 | 3 | 5 |
|---|---|---|---|
| Files touched | One module | A few | Many, across packages |
| Test coverage around it | Strong | Partial | None |
| Public API change | None | Internal only | External callers |
| Caller migration | None | Some call sites | Cross-team |
| Coordination | Solo | Review from one owner | Several teams |
Scroll the table sideways to see every column.
Effort is not lines of code. A small change in a brittle, untested area costs more than a larger change in a well-covered one. Fowler's small-steps rule also lowers the score: the more you can split a change into behavior-preserving increments, the cheaper it is.
Compute the priority
priority = impact / effort
Both sums run from 5 to 25. For a faster version in a planning meeting, use (impact x 2) - effort. Then filter out candidates that score well but should wait:
- Code scheduled for deletion. Delete it instead; see how to find dead code.
- Code with no planned changes.
- Work blocked by a wider architecture decision.
- Cleanup that only improves style.
Finally, pick a slice, not "the refactor": "extract payments validation from checkout" or "split the 1,500-line module into three files". A slice that fits in one pull request gets finished.
What does a good first-quarter target look like?
The best targets are boring: active, bounded and in the way. They are not rewrites.
| Strong target | Why it ranks high |
|---|---|
| A shared utility file that became a junk drawer | High fan-out, changes weekly, unrelated helpers |
| A package that parses, validates and persists in one place | Hard to test in isolation, every feature lands there |
| A critical path with repeated regressions (checkout, auth, billing, sync) | Expensive to touch even when small |
| A module only one engineer understands | Low bus factor, every change needs tribal knowledge |
| The same validation copied across callers | Easy to extract, easy to test, easy to review |
Scroll the table sideways to see every column.
Weak targets share one trait: nobody would feel their absence. A static admin script, dead code awaiting deletion, a pretty file with no future work, or a rewrite requested because the code "feels old". The filter is simple: if the code disappeared tomorrow, would anyone feel pain in the next 30 days?
Refactor or rewrite?
Refactor when the system mostly works and the pain is local; rewrite only when the architecture cannot meet basic requirements and you can run both systems during migration. Refactoring improves design through small, behavior-preserving steps. A rewrite is a different bet: it replaces the system and risks losing behavior you did not know existed.
| Condition | Refactor | Rewrite |
|---|---|---|
| Existing behavior mostly correct | Yes | Maybe |
| Need gradual delivery | Yes | No |
| Tests available | Yes | Helpful, not required |
| Architecture fundamentally wrong | Sometimes | Often |
| Team can run both systems | Sometimes | Usually required |
Scroll the table sideways to see every column.
When unsure, run a spike: one small extraction or boundary cleanup tells you whether the system can be reshaped in place.
How does repowise rank refactoring targets automatically?
repowise health --refactoring-targets prints a ranked queue of concrete plans, scored from the same graph, class model and git history that drive the health score. Manual scoring works for a few dozen candidates. Past that, ownership is unclear and the list moves faster than a spreadsheet.
pip install repowise
repowise init
repowise health --refactoring-targets            # the stored queue, in serving order
repowise health --refactoring-targets --format json
repowise health --plan refac...                  # one plan as the prompt an agent applies
Plans are built during repowise init and repowise update, with no LLM key and no network. Each plan is one of seven types: Extract Class, Extract Method, Extract Helper, Move Method, Break Cycle, Split File and Performance Fix. Each carries fields that map onto the scoring above:
| Plan field | Maps to | What it tells you |
|---|---|---|
effort_bucket | Effort | S, M, L or XL, from the size of the target |
blast_radius | Impact | Callers, importing files and co-change partners that must change too |
impact_delta | Impact | Health the plan would recover |
confidence | Effort | A high Extract Method is mechanical enough to hand to an agent |
evidence | Impact | The measurements behind the plan: LCOM4, clone size, co-change count |
Scroll the table sideways to see every column.
By default the queue ranks what Fix first would take: opportunities in shipped code that recover real health and name a concrete edit. Test files, generated code, vendored code and dead code are left out and counted with a reason. The order is diversified, so the first rows cover distinct problems instead of five copies of the same one.
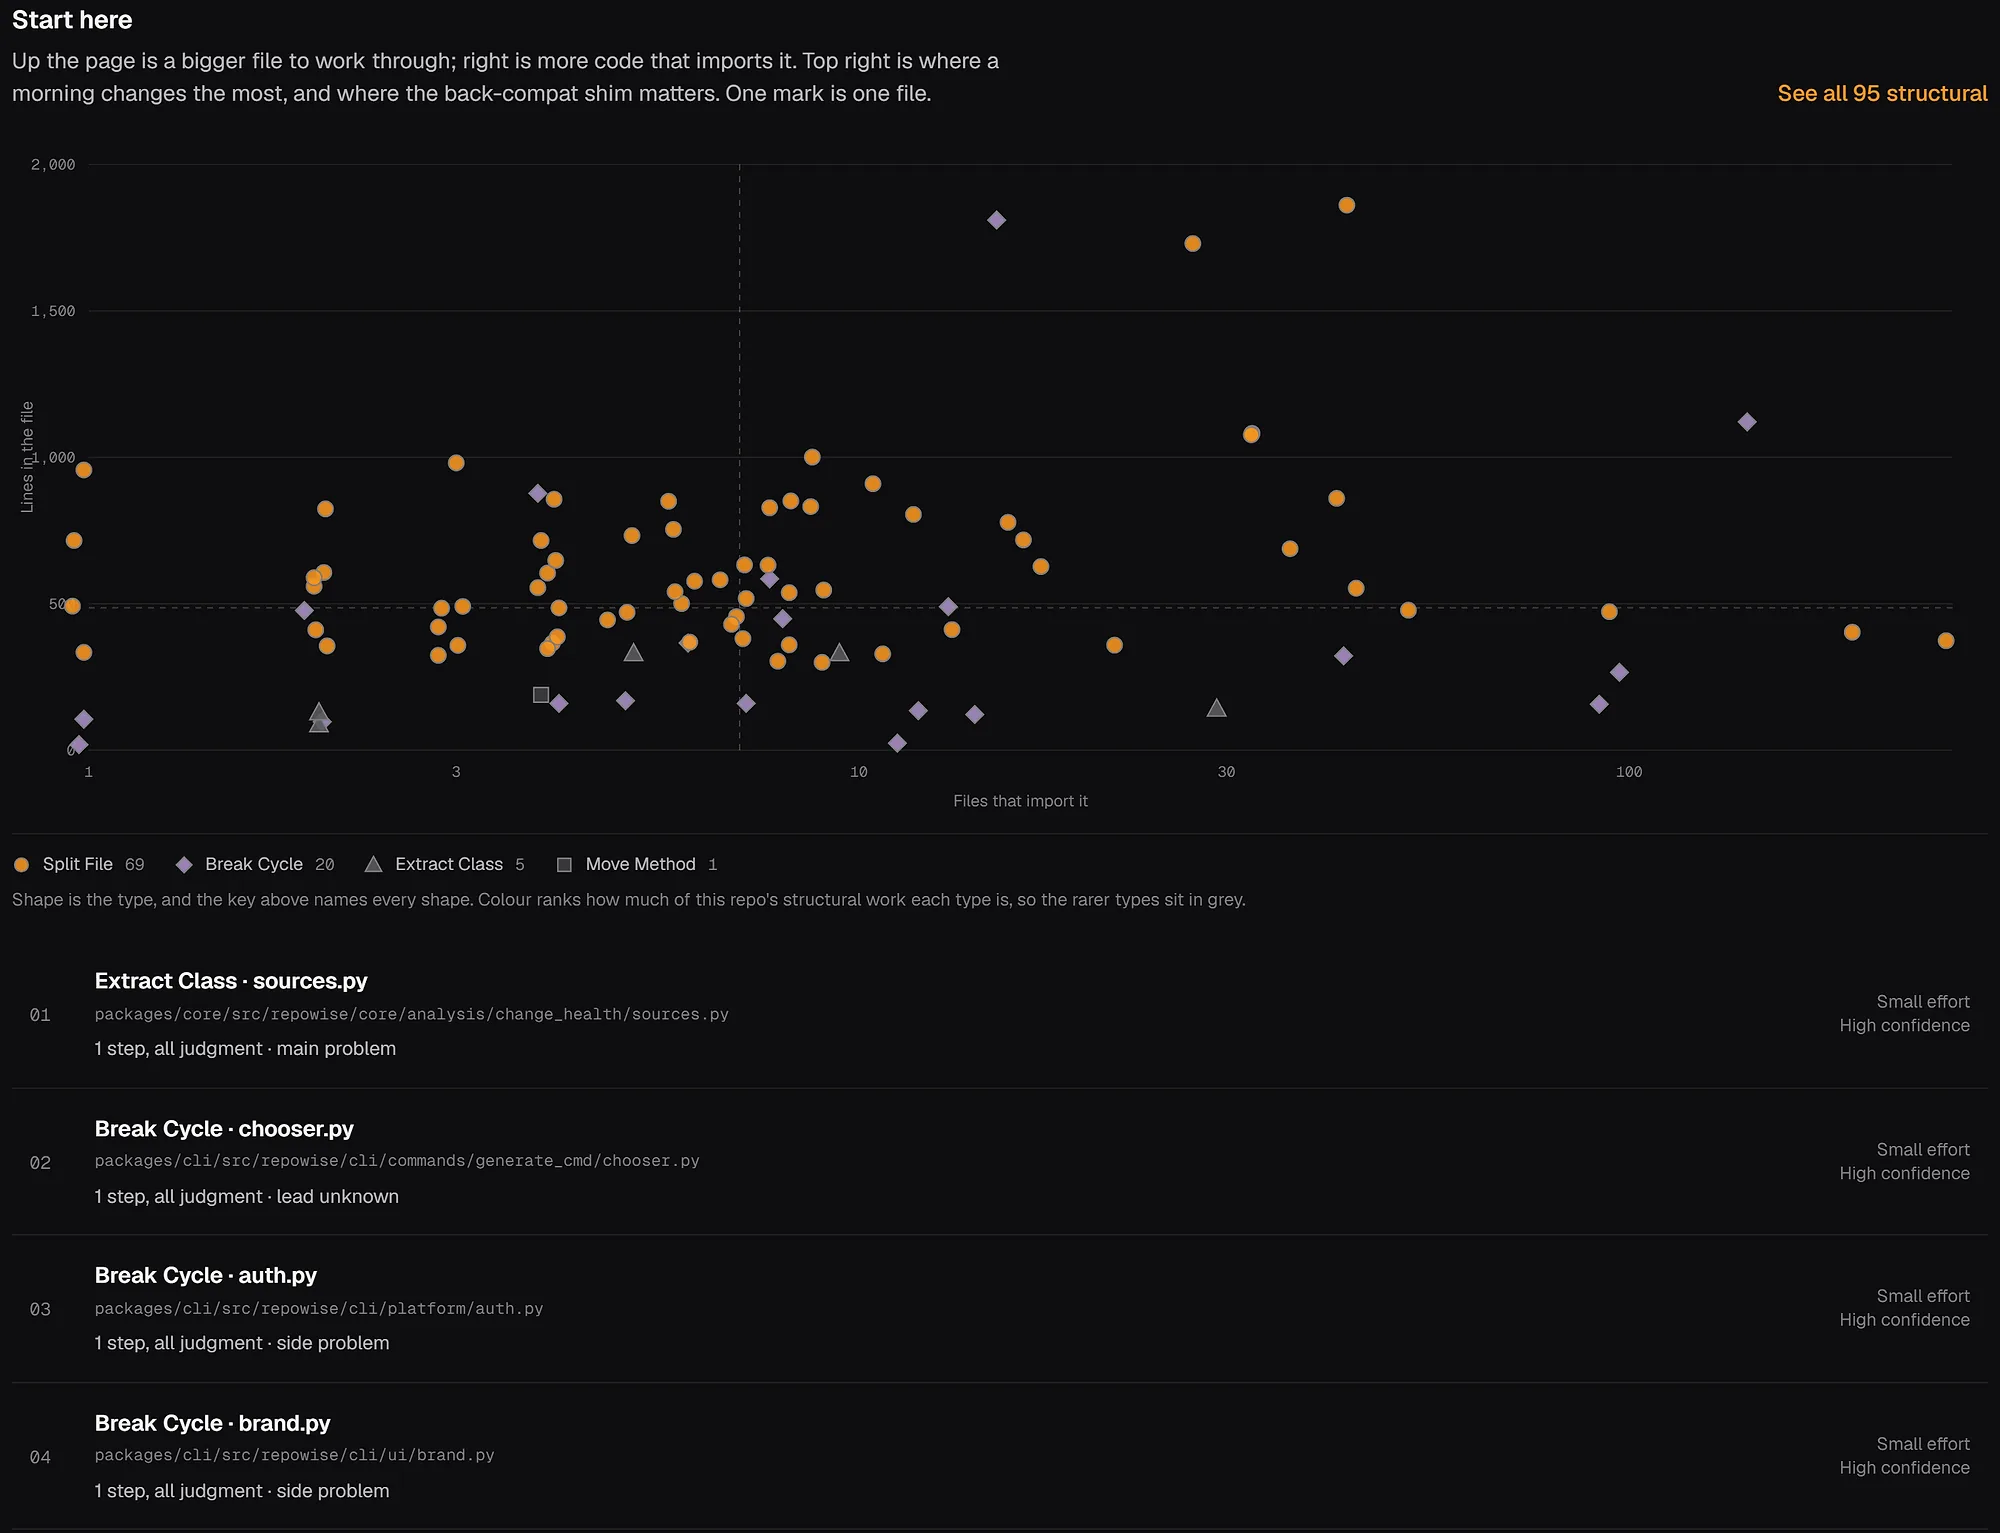
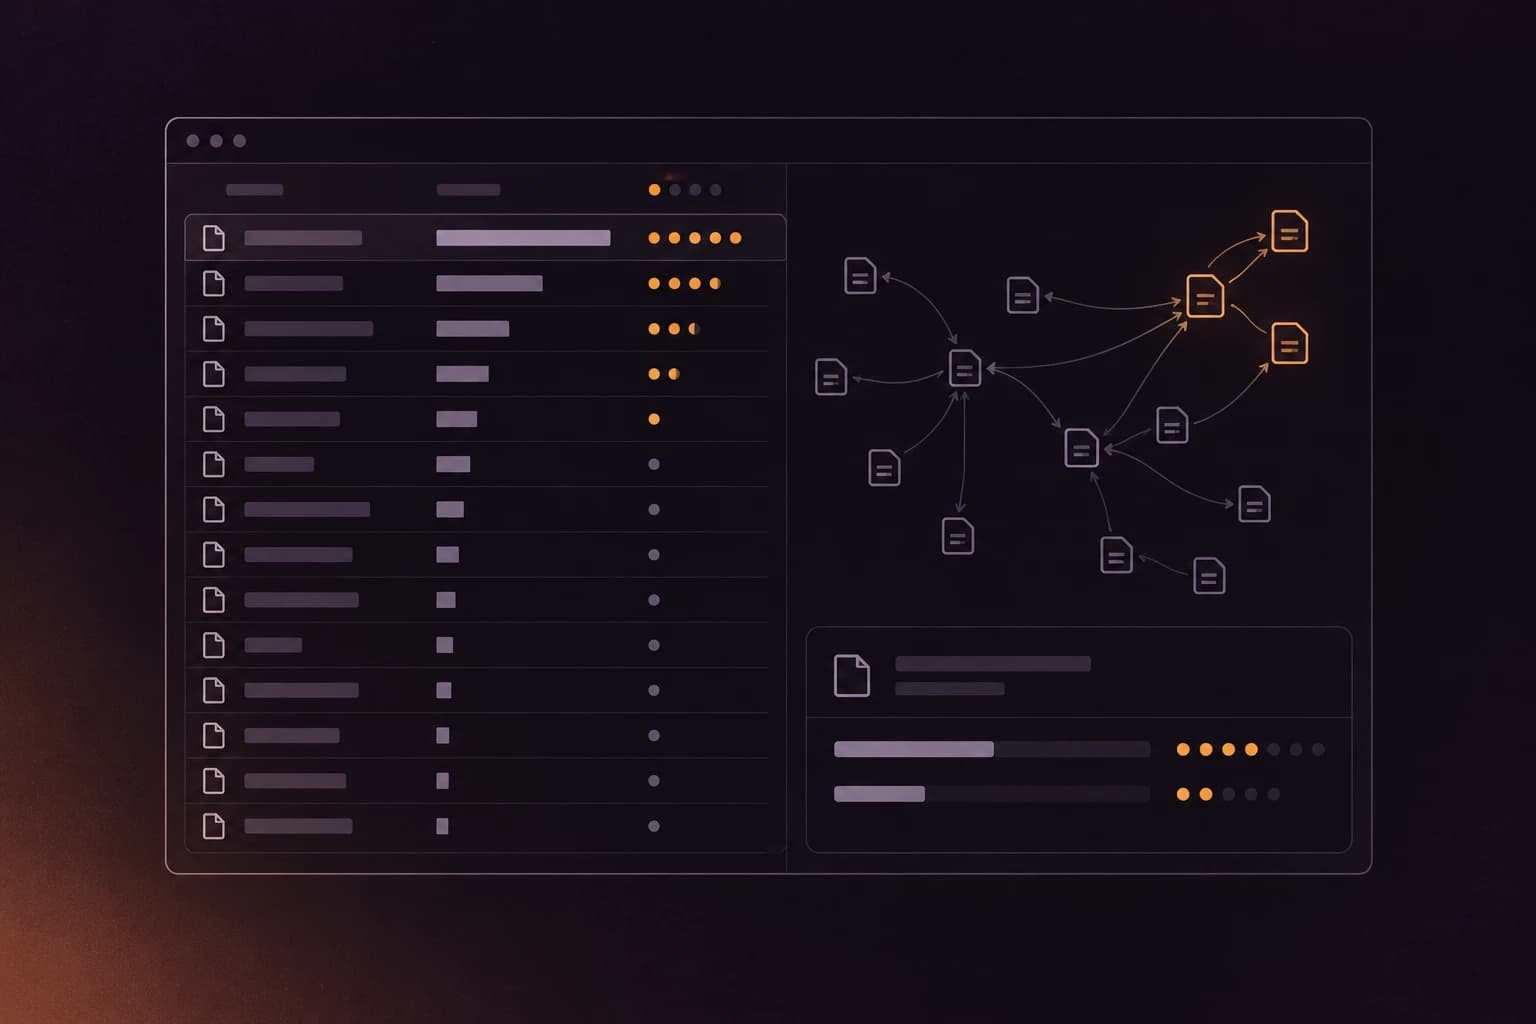
The scatter plots lines in the file against the number of files that import it, so the top right is large, widely imported code. Each row below shows the plan type, effort and confidence. A plan's drawer lists the tests closest to the change and the command to run them. When no test reaches the change, the plan has no command and asks for a characterization test first, which answers the "make it safe" question inside the queue itself.
Using it from an agent
The same data is available over MCP through get_health, one of ten tools:
get_health(only=["fix_first"])                                       # refactorings ranked beside other fixes
get_health(include=["refactoring"], only=["refactoring_opportunities"], limit=6)
get_health(targets=["src/api/server.py"], include=["refactoring"])   # one file
get_health(plan_id="refac...", include=["recipe"])                   # the plan as ordered steps
A recipe lists what must hold before the edit, the edits in order, the checks afterwards and what the edit must not do. repowise never applies edits itself; the agent or the engineer does. For the history behind a file, git intelligence gives churn, ownership and co-change, and the FastAPI code health demo shows these views on a public repository.
Pitfalls
Most failed refactors fail on scope, not on the score.
- Refactoring code that is about to change shape. Check the roadmap before you start.
- Scoring once. Change frequency and ownership move; re-score monthly and delete items whose code went quiet.
- Skipping tests. Add a characterization test first when none reaches the code.
- Splitting a plan across teams. If the blast radius spans owners, agree the interface change before the extraction.
- Counting cosmetic wins. "Done" means the next edit is cheaper. If the code only looks cleaner but still hurts to touch, the refactor was cosmetic.
Keep the backlog useful
Add candidates during bugs, incidents and feature work, attach each to an owner, and track one outcome per refactor: fewer fix commits, faster review or shorter lead time. The most valuable item is often the one that keeps showing up in unrelated work. That repetition is the signal.
FAQ
- What is refactoring prioritization?
- It is choosing which code to clean up first. Good prioritization ranks candidates by impact per effort, using change frequency, blast radius and bug history, instead of how untidy the code looks.
- What should I refactor first?
- Start with active code that changes often, causes repeated pain and has many dependents, and that you can fix in a small, safe slice. Ignore stable code nobody edits.
- How do I measure impact per effort?
- Score impact from 1 to 5 on change frequency, blast radius, bug history, incident involvement and knowledge concentration. Score effort on files touched, test coverage, API change, caller migration and coordination. Divide impact by effort.
- Is technical debt prioritization the same as refactoring priorities?
- Not quite. Technical debt also covers missing tests, weak architecture and operational risk. Refactoring priorities is the code-shape part, and the same impact-per-effort method applies to both. See how to prioritize technical debt.
- When should I use a tool instead of scoring by hand?
- Use a tool when the repository is large, ownership is unclear, or you need evidence from history and the dependency graph. By hand is fine for a short list.
- Does repowise change my code?
- No. repowise returns plans, recipes and the tests to run. Code generation for a plan is opt-in, calls your configured LLM provider, and returns a diff that you review. Nothing is applied to your files.
- How does repowise compare with CodeScene for refactoring targets?
- Both combine code health with change frequency to find hotspots. repowise also returns a concrete plan per target (Extract Method, Split File, Break Cycle and more) with blast radius, effort and the tests to run, and serves it to agents over MCP. --- For the full picture, see the cluster hub: How to prioritize technical debt (impact-per-effort).