On this page
To generate a CLAUDE.md, run /init inside Claude Code for a first draft from what Claude finds in your repository, or run repowise generate-claude-md to render one from a real dependency graph, git history and recorded decisions. The repowise file needs no LLM call and no API key, and repowise update keeps it current as the code changes.
Part of the Auto Wiki guide. New to these files? Read the CLAUDE.md and AGENTS.md complete guide first.
The quick answer
Both routes produce a file Claude Code reads at the start of every session. They differ in where the content comes from and whether it stays current.
Claude Code /init | repowise generate-claude-md | |
|---|---|---|
| Source | Claude explores the repo during the session | Dependency graph, git history, decisions and manifests, already indexed |
| LLM call | Yes, uses your session | None |
| Contents | Build and test commands, conventions it discovers | Architecture summary, key modules, entry points, tech stack, hotspots, decisions, commands, MCP workflow guide |
| Re-run behavior | Suggests improvements to an existing file | Replaces only its own marked section, keeps your text |
| Stays current | When you edit it | On every repowise update |
| Cost | Session tokens | Free |
Scroll the table sideways to see every column.
Use /init for a quick start on a small repository. Use repowise when the repository is large enough that a model's one-time exploration misses things, or when the file must follow the code. The two combine: write your team's rules by hand, and let repowise own the structural half.
What a CLAUDE.md should contain
A CLAUDE.md is persistent context that loads into every session, so it should hold only what the agent cannot cheaply discover and would otherwise get wrong. Anthropic's memory documentation lists project-level standards: build and test commands, coding standards, architectural decisions and naming conventions. It also advises a target of under 200 lines per file, because longer files consume more context and reduce adherence, and it treats the file as context rather than enforced configuration (as of October 2026).
That makes selection the hard part. A useful file answers five questions:
- What is this system and how is it shaped?
- Which files matter most, and where does execution start?
- Which files are fragile?
- How do I build, test and lint?
- Which decisions were made on purpose and should not be undone?
A hand-written file answers them on the day it is written. By the next refactor it points at directories that moved. Generating the structural answers from the code removes that drift.
Step 1: Generate it with repowise
Install repowise, index the repository, and the CLAUDE.md is written as part of the run.
pip install repowise
cd your-repo
repowise init --no-prose -y
--no-prose builds the index and a structural wiki with no LLM calls and no key. Drop it to add model-written wiki pages on top. Either way init registers the repowise MCP server with Claude Code and writes the managed CLAUDE.md after indexing finishes.
To regenerate the file on its own, or to preview it:
repowise generate-claude-md              # write .claude/CLAUDE.md
repowise generate-claude-md --stdout     # print it, write nothing
repowise generate-claude-md -o docs/CLAUDE.md
Pass --no-claude-md to init to skip the file; the preference is saved to .repowise/config.yaml as editor_files.claude_md: false. All flags are in the CLI reference.
Step 2: Read what it wrote
The generated section has three parts, targeted at 150 to 250 lines in total. It sits between two markers; everything above them is yours.
# CLAUDE.md

<!-- Add your custom instructions below. repowise will never modify anything outside the REPOWISE markers. -->

[your own rules: style, test commands, workflow]

<!-- REPOWISE:START - Do not edit below this line. -->
## Codebase Intelligence
...
<!-- REPOWISE:END -->
| Part | What it holds | Where it comes from |
|---|---|---|
| Codebase intelligence | Architecture summary, the top 10 key modules with owners, the top 10 entry points, tech stack, the top 5 hotspots | Wiki, PageRank over the dependency graph, git history, manifests such as package.json, pyproject.toml, go.mod, Cargo.toml |
| MCP workflow guide | When to call each repowise tool, in plain workflow language | A fixed template |
| Conventions | The eight most current architectural decisions, plus build, test, lint and format commands | Decision records and the scripts in your manifests and Makefile |
Scroll the table sideways to see every column.
Two details matter for quality. Entry points are ranked on execution-start evidence, not on how many files import them, because centrality rewards a widely imported barrel file over the real front door. And every list has a stable sort order with the path as the final tie-break, so regenerating on an unchanged index produces an identical file and clean diffs.
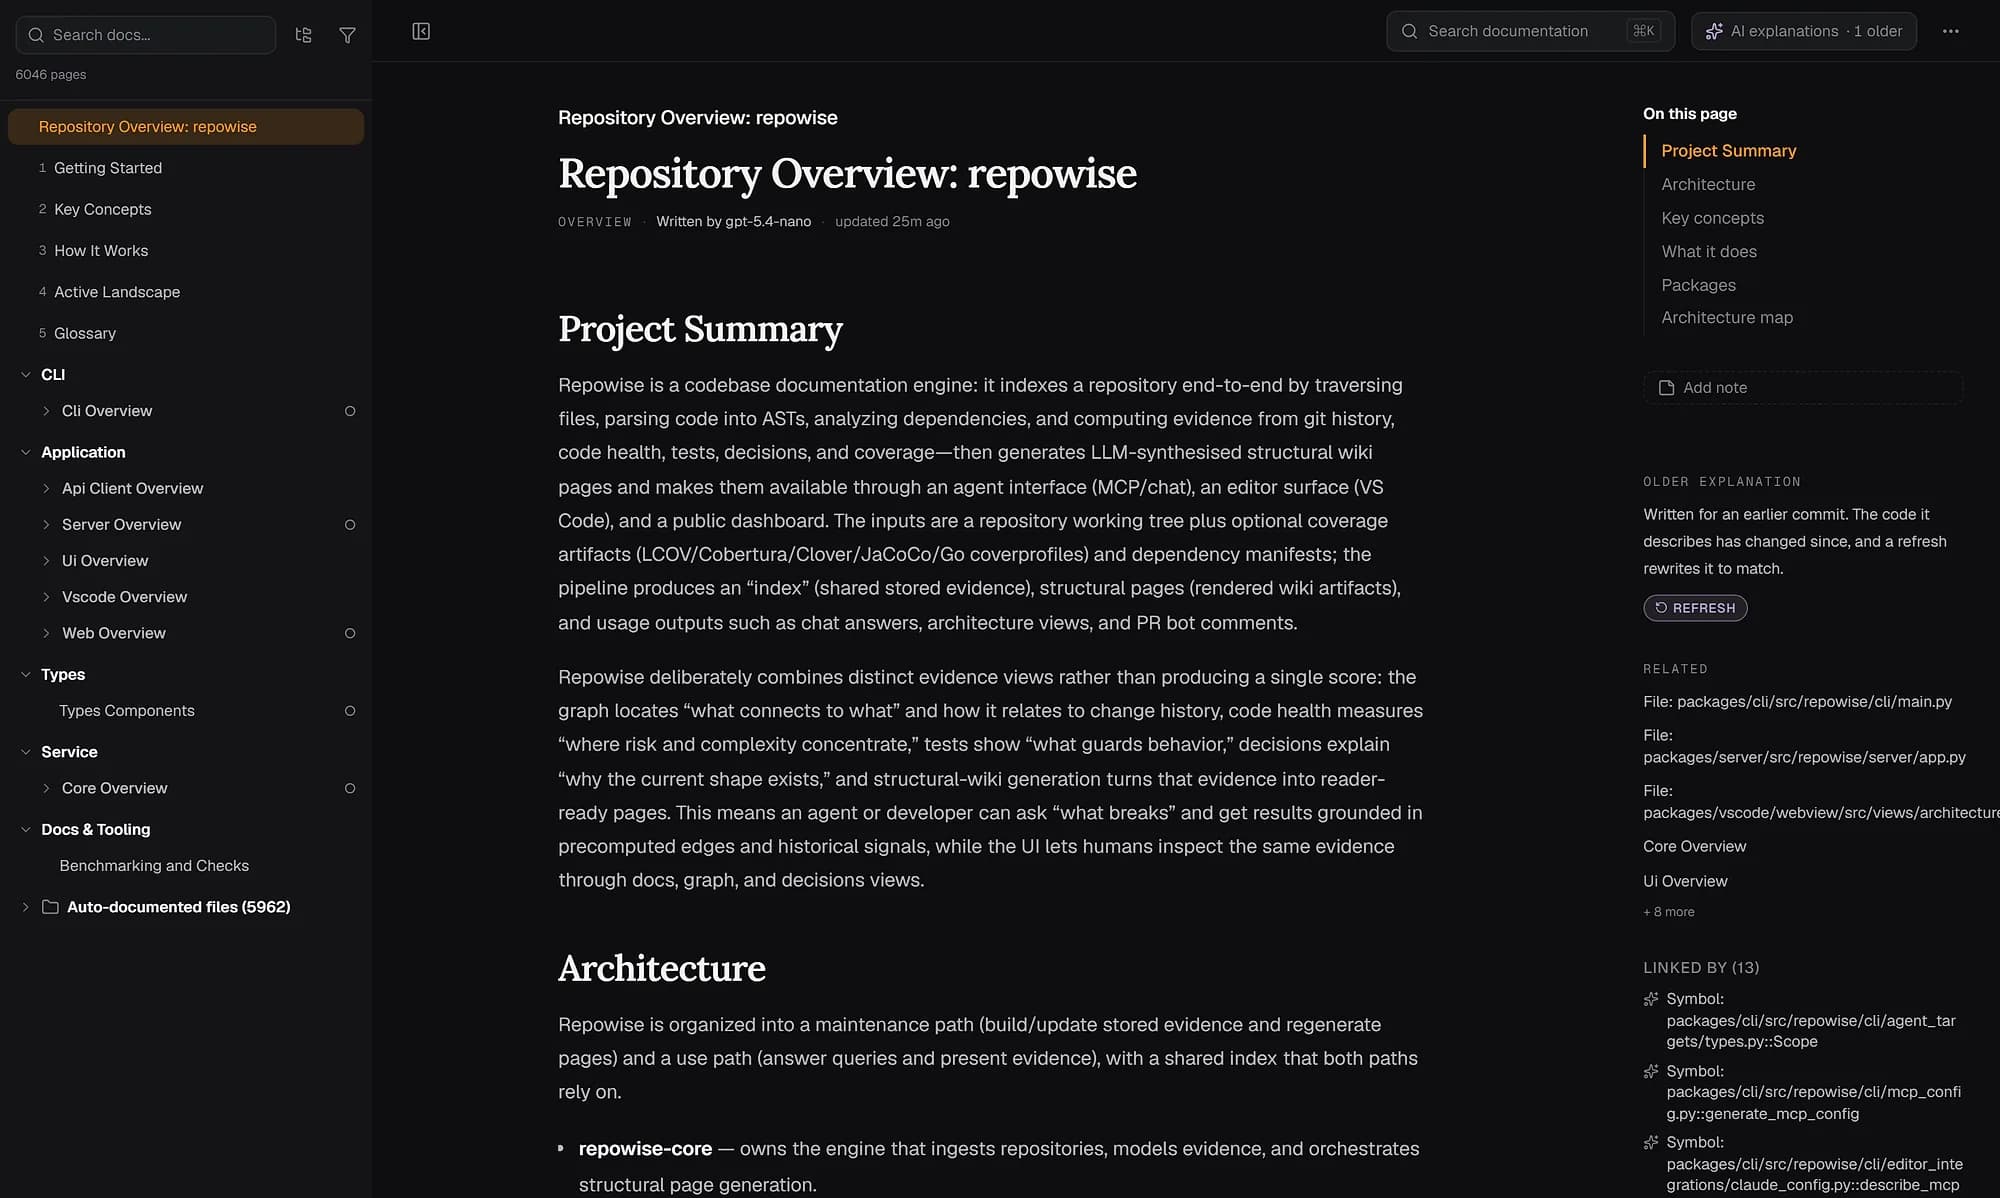
The overview page above is where the architecture summary comes from. The generator takes its first sentences, so the file and the wiki never disagree.
Step 3: Add your own rules
Put team conventions above the REPOWISE:START marker, where repowise never touches them. Good candidates are rules the code cannot reveal: a naming convention, a "never edit generated files" instruction, the PR checklist, which test command to run before pushing. Keep each rule specific enough to check. "Run npm run test before committing" beats "write good tests".
If a file already exists without markers, repowise appends its section at the bottom and leaves your content as it was. Anything you type inside the markers is overwritten on the next run.
Step 4: Keep it current
repowise update re-analyzes only what changed and regenerates the managed section afterwards. It is incremental, so it fits a post-merge hook or a CI job.
repowise update
Because the content is derived from the index, there is nothing to remember to edit. Move a service from /lib to /core and the next update changes the key modules list to match.
Step 5: Connect the MCP server
CLAUDE.md orients the agent; the MCP server answers specific questions. The file covers what fits in 200 lines. For everything else, Claude Code calls the ten repowise MCP tools on demand, and the generated workflow guide tells it when:
| Question | Tool |
|---|---|
| How does X work, and where is it? | get_answer |
| What is in this file, module or symbol? | get_context |
| Which files are risky to touch? | get_risk |
| What is the risk of this diff? | get_change_risk |
| Why is the code shaped this way? | get_why |
| What is dead? | get_dead_code |
Scroll the table sideways to see every column.
The rest are get_overview, get_health, get_symbol and search_codebase. See the AI context feature page and the MCP tool reference.
Large repositories and monorepos
Keep one root file small and split by scope. Claude Code loads a subdirectory's CLAUDE.md only when it works on files there, and supports path-scoped rules in .claude/rules/ for guidance that applies to part of the tree (Anthropic docs). Put architecture and commands at the root, and package-specific rules next to the package.
For several repositories, repowise generate-claude-md --workspace writes a workspace-level file at the workspace root with cross-repo contracts, co-changes and per-repo summaries.
Using AGENTS.md or another agent
Claude Code can read a repository's AGENTS.md in place of a CLAUDE.md. repowise writes a managed AGENTS.md for Codex with repowise init --codex, using the same marker scheme, so one index can feed both. Other hosts are wired with repowise agents add. The CLAUDE.md and AGENTS.md guide covers choosing between them.
Pitfalls
- The file is too long. Past about 200 lines, adherence drops. Trim your own section first; the generated one is already capped.
- Rules go inside the markers. They are overwritten on the next run. Write above
REPOWISE:START. - Treating it as enforcement. Anthropic describes CLAUDE.md as context, not configuration. To block an action outright, use a hook.
- Claude is not loading it. Run
/contextin a session and check the Memory files list. Project files live at./CLAUDE.mdor./.claude/CLAUDE.md. - A stale index. The file reflects the last
initorupdate. Runrepowise updateafter a large change.
FAQ
- How do I create a CLAUDE.md file?
- Run
/initin Claude Code to have Claude draft one from your repository, or runrepowise generate-claude-mdto render one from an index of the dependency graph, git history and decisions. Either file can be edited by hand afterwards, and repowise keeps your edits when it refreshes its own section. - Does repowise send my code to an LLM to write CLAUDE.md?
- No. The file is rendered from the local index with no model call, so it works without an API key. Model-written wiki pages are optional and run only if you choose a provider during
init. - Where does CLAUDE.md go?
- In the repository root as
CLAUDE.md, or in.claude/CLAUDE.md. Personal instructions for all projects go in~/.claude/CLAUDE.md. repowise writes.claude/CLAUDE.mdby default and accepts--outputfor another path. - How long should a CLAUDE.md be?
- Anthropic recommends under 200 lines per file. The repowise managed section targets 150 to 250 lines in total with every list capped, and you can move package-specific guidance into subdirectory files or path-scoped rules.
- What is the difference between CLAUDE.md and a README?
- A README onboards people: what the project is and how to run it. A CLAUDE.md gives an agent the structure, fragile files, commands and decisions it needs before editing. The two overlap on commands and little else.
- Which languages does it support?
- repowise parses 28 languages to a full AST, with 15 at the Full tier. Tech stack and command detection reads manifests for Node.js, Python, Rust, Go, Java, Kotlin, Ruby, PHP and Docker. See what repowise generates on real repositories in the live examples.