On this page
An architectural decision record (ADR) is a short file in your repository that states one decision, the context that forced it, and what it costs. Teams that keep them can answer "why is the code like this?" in seconds. Teams that do not end up reading git blame for a message that says "refactor". This post covers the template, a rule for when to write one, how to recover decisions you never recorded, and how to put them in front of AI agents.
Part of the Decision Records guide.
Why do you need architectural decision records?
Code records what the system does and tests record whether it works. Only a decision record explains why it has this shape. A line like retry_strategy = ExponentialBackoff(max_attempts=5) shows the mechanism. It does not say that five attempts match the 60 second rate-limit window of a legacy downstream API.
That reasoning usually lives in a design doc that went stale, a call nobody minuted, or a Slack thread. When it is gone, the structure becomes a Chesterton's fence: nobody dares remove it because nobody knows what it holds back. New engineers ask the same questions, and the people who know the answers become the search engine.
Michael Nygard popularized the fix in 2011 with Documenting Architecture Decisions: keep a small record of each significant decision, in version control, next to the code. The ADR community site now maintains templates and tooling around the practice.
What goes in an ADR?
Nygard's format has a title, context, decision and consequences, plus a status. Keep it to one or two pages and write it for the engineer who joins in two years. MADR adds an explicit list of considered options, which is worth having.
| Section | What it answers |
|---|---|
| Title | A short noun phrase: "Use Vite for frontend tooling" |
| Status | Proposed, accepted, deprecated or superseded |
| Context | The forces at play: constraints, deadlines, what else was considered |
| Decision | What we will do, in active voice |
| Consequences | What we gain and what it costs, good and bad |
Scroll the table sideways to see every column.
# ADR 005: Use Vite for frontend tooling

## Status
Accepted

## Context
Our Webpack build takes 45 seconds to reflect a change in development,
which slows every frontend task.

## Decision
We will migrate to Vite for native ESM hot module replacement.

## Consequences
- Dev server starts in seconds.
- Some legacy CommonJS dependencies need updating.
- Production builds now run through Rollup.
Store them in docs/adr/ (Nygard suggests doc/arch/). repowise reads adr/, adrs/, docs/adr/, docs/adrs/, docs/decisions/, decisions/, architecture/ and doc/adr/, in Nygard and MADR headings.
When should you write an ADR?
Write one for decisions that are hard or expensive to reverse. Skip the ones a pull request description already explains.
- Choosing a primary database, queue or broker.
- Picking a communication style between services (REST, gRPC, events).
- Adopting a core framework or a deployment model.
- Choosing a monorepo or several repositories.
Be honest in the consequences section. A decision with no downside is a best practice, not a trade-off, and the downsides are what a future maintainer needs most.
How do you recover decisions nobody wrote down?
The reasoning is usually already in the repository, in places that are not called ADRs. repowise reads those places during repowise init and repowise update:
| Source | What it reads | Needs an LLM key |
|---|---|---|
| ADR files | The folders above, Nygard and MADR headings | No |
| Inline markers | WHY:, DECISION:, TRADEOFF:, ADR:, RATIONALE:, REJECTED: in any comment syntax | No |
| Commits | Messages with a decision verb (migrate, switch to, replace, adopt, drop) | Yes |
| Pull request bodies | Squash-merge and PR commit bodies | Yes |
| Code comments | Rationale prose in the most central files | Yes |
| Manual entry | repowise decision add and the dashboard form | No |
Scroll the table sideways to see every column.
You can also opt in to mining your local coding-agent sessions. Every stored field is checked against a verbatim quote from the source, and a field it cannot ground is cleared. The same decision found in two places becomes one record with two pieces of evidence.
A lightweight habit makes this richer: write # WHY: five attempts, the legacy API resets its limit every 60 seconds next to the code. It costs one line and repowise picks it up with no model call.
Candidates, decisions and who decides
repowise separates what a machine finds from what a person accepts. A mined record is a candidate and governs nothing. Only an accepted decision reaches your agent as a rule.
repowise decision candidates         # what awaits review
repowise decision confirm a1b2c3d4   # accept one; this is what makes it govern
repowise decision list               # decisions and candidates
repowise decision health             # stale, unscoped, ungoverned hotspots
repowise decision export             # write accepted ones to .repowise/decisions.yaml
Acceptance is recorded with a reason, a scope (the files or modules it governs), an evidence reference and who signed it. repowise refuses to store one that lacks any of these. An ADR that is committed, marked accepted and names what it governs accepts itself, with the file as the signer. decision export writes accepted decisions to .repowise/decisions.yaml, which you commit so the record travels with the repository.
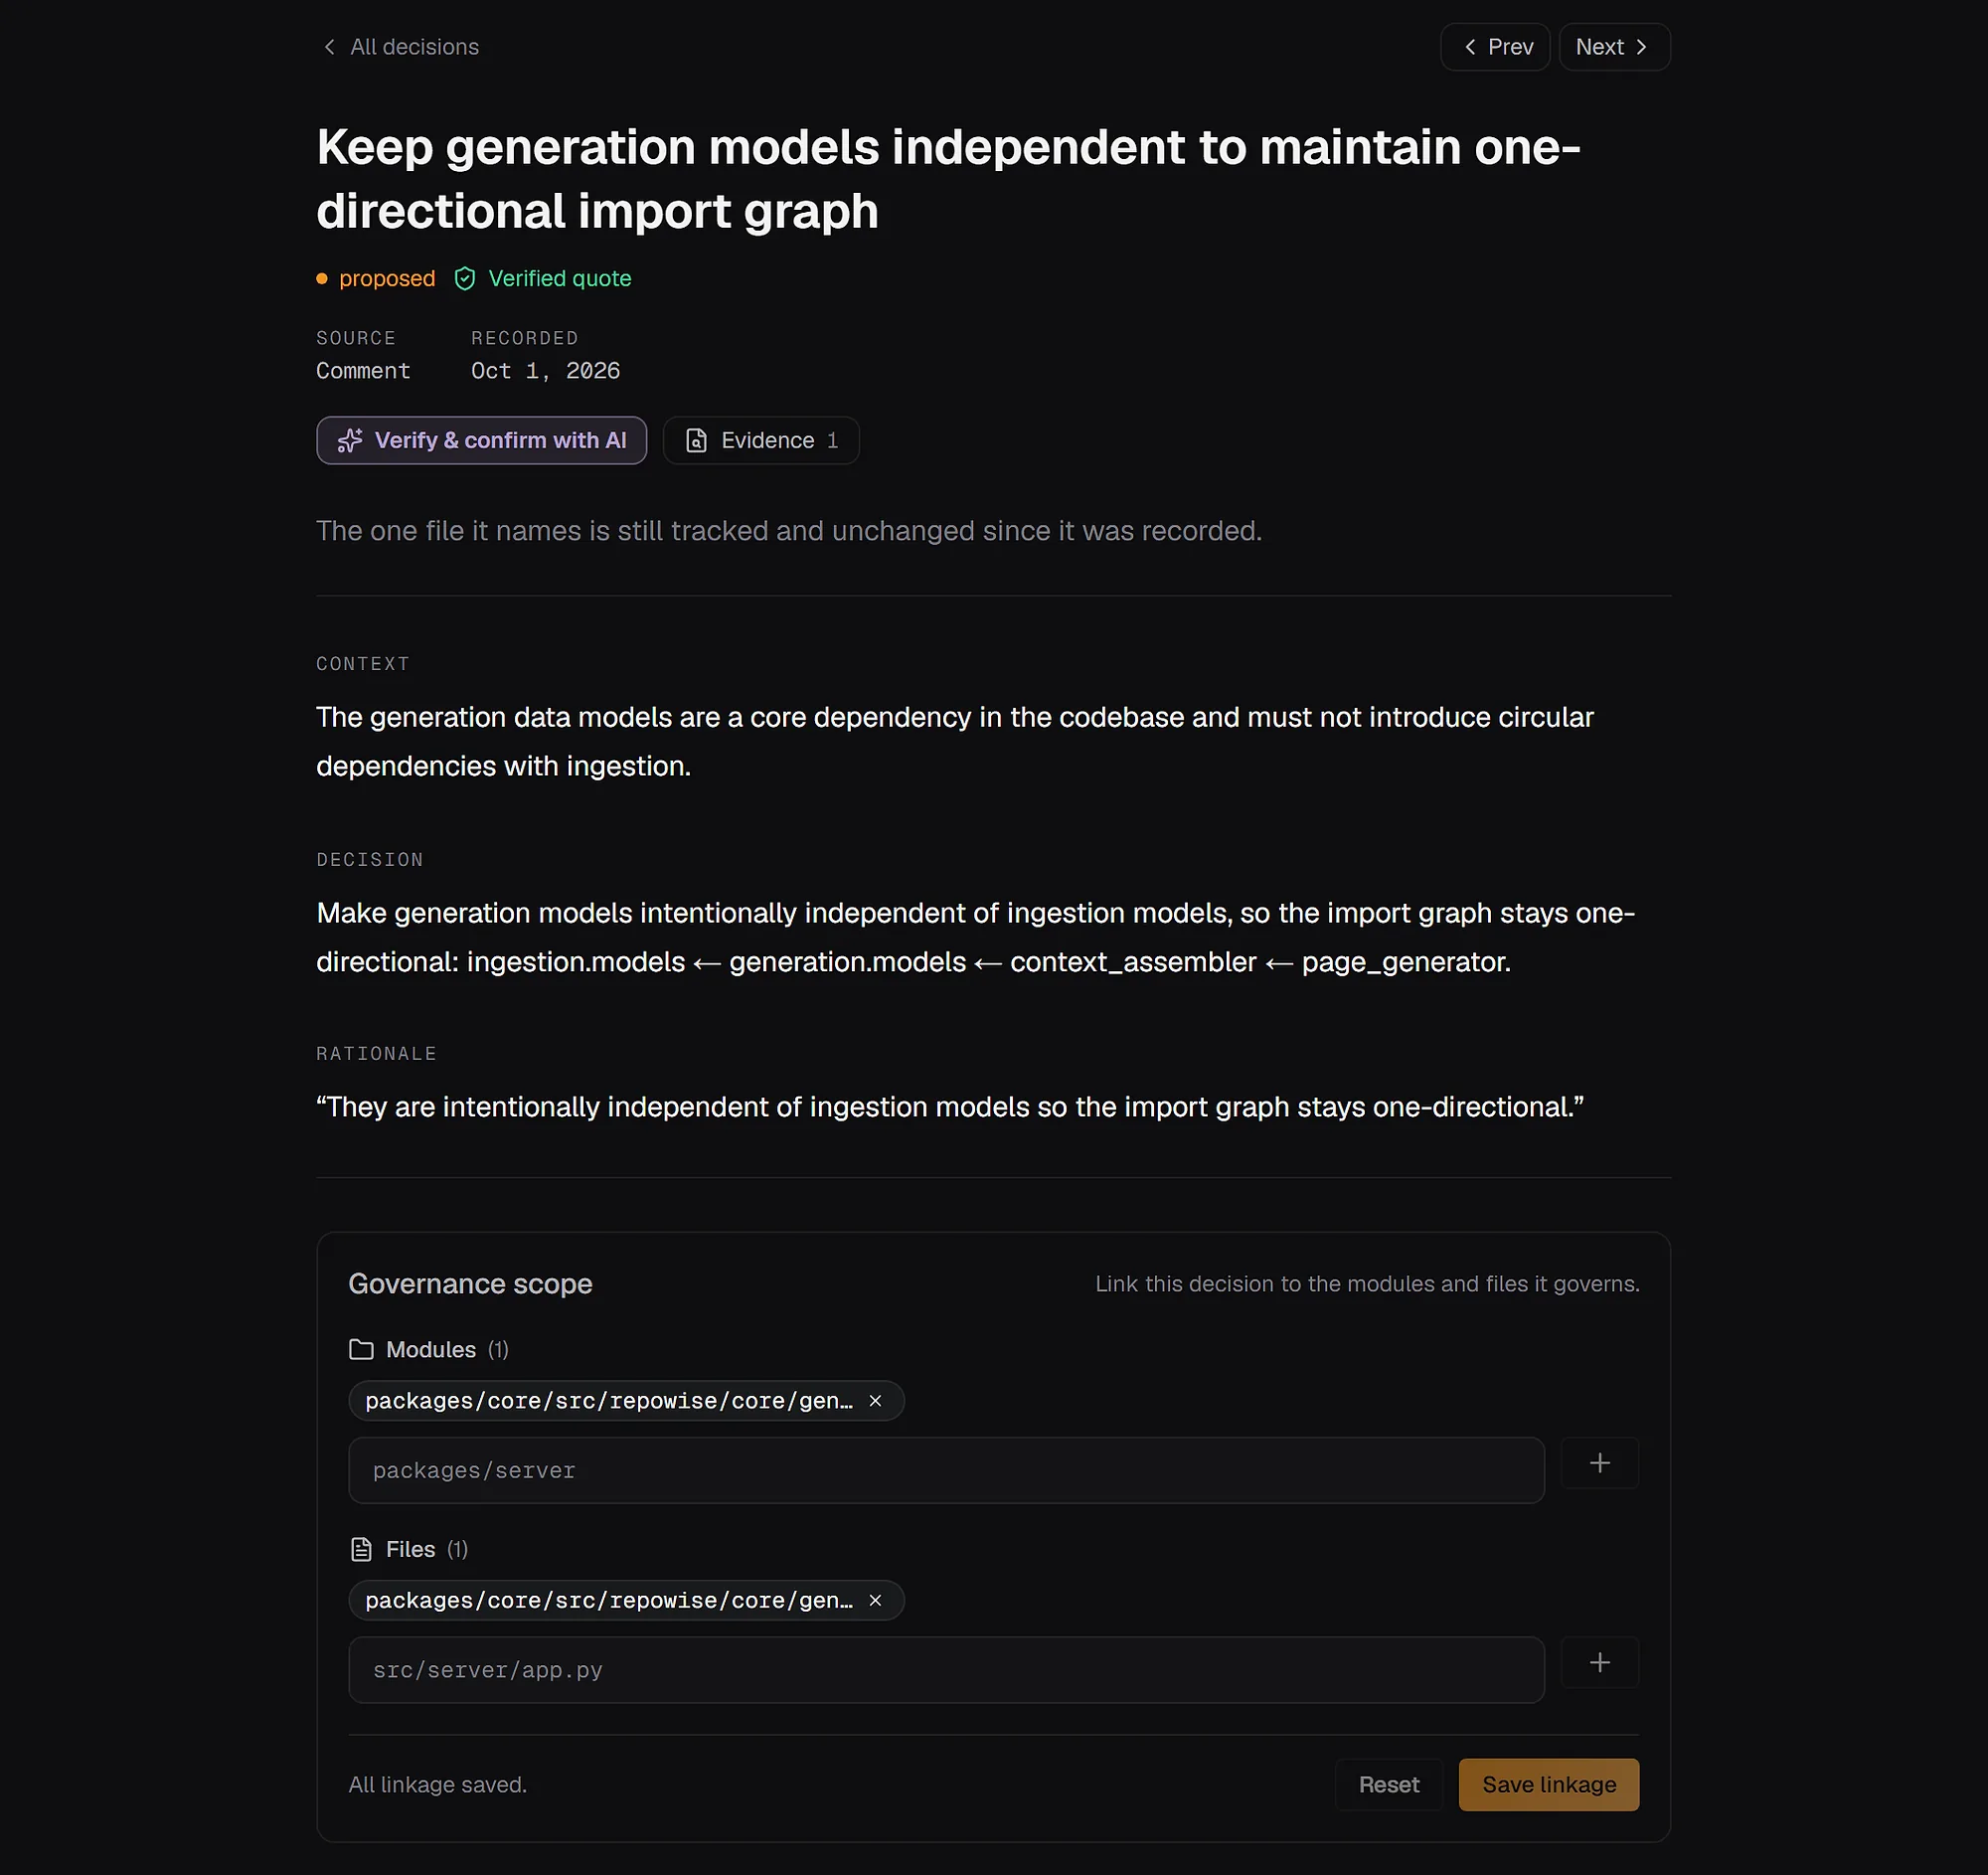
Record a decision yourself from a script or an agent:
repowise decision add --title "JWT over sessions" \
  --decision "Authenticate API calls with signed JWTs" \
  --rationale "Stateless horizontal scaling" \
  --affects src/auth
How do you keep ADRs from going stale?
repowise checks every accepted decision against the code on each read. The staleness score is the fraction of its governed files committed to since the decision was recorded. At 0.5 or above it is flagged needs_review, and if every file it names is gone it is stale and stops governing.
repowise decision health

  Active decisions          14
  Proposed (needs review)    3
  Stale decisions            2

  Stale decisions (2):
    9f3c1a44  JWT over sessions          (staleness: 0.72)
When a decision is replaced, record the successor so lineage survives: repowise decision deprecate ID --superseded-by ID2. Review decision health during architecture reviews, the same way you review any other drift. For the wider picture of keeping documentation current, see codebase documentation that stays current and where architecture decisions live.
How do AI agents read your decisions?
Through hooks and the get_why MCP tool, so the agent sees the rule before it breaks it. At session start repowise injects the most relevant accepted decisions under a hard cap of about 400 tokens. When the agent edits a file a decision governs, it gets a one-line notice with the rationale, once per session.
get_why is one of ten MCP tools and picks its mode from the call:
| Call | Returns |
|---|---|
get_why() | Governance health: counts, stale decisions, ungoverned hotspots |
get_why(query="src/auth/jwt.py") | Decisions governing the file, candidates, history, and an origin story from git |
get_why(query="why JWT over sessions?") | Ranked decision search, optionally anchored with targets |
Scroll the table sideways to see every column.
Only the decisions lane is a rule; candidates and history are labelled and never mixed in. When no decision covers a path, get_why falls back to git history, then to a rationale comment in the source. Accepted decisions also appear in the generated CLAUDE.md and in get_risk as a governance flag. See decisions for the full feature.
Building an ADR practice
- Run
repowise initand readrepowise decision candidates. Accept what is right and dismiss the rest; a dismissed candidate is never proposed again. - Write new ADRs only for one-way-door decisions, and add
WHY:comments for smaller ones. - Add manual decisions for business reasons code cannot show, such as a vendor chosen for a compliance requirement.
- Review
repowise decision healthon a schedule and supersede what no longer holds.
FAQ
- What is an architectural decision record?
- An ADR is a short document, usually markdown in the repository, that records one significant architectural decision with its context, the decision itself and its consequences. It is kept with the code so it is versioned and reviewed like code.
- How many ADRs should a project have?
- There is no target. If you have hundreds, you are likely recording implementation details. A healthy project has one for each decision that would be costly to reverse.
- Where should ADRs be stored?
- In the repository, in a folder such as
docs/adr/, one file per decision. repowise also scansadr/,docs/decisions/,architecture/and other common folders. - Do I need a specialized ADR tool?
- No, markdown files are enough to start. A tool such as repowise adds mining of existing history, a check that each decision still matches the code, and delivery of decisions to AI agents.
- Does repowise write ADRs for me?
- It proposes candidates from your ADRs, comments, commits and pull requests, each backed by a verbatim quote. A person accepts them; nothing governs until then.
- Does decision capture need an LLM key?
- ADR files, inline markers and manual entry need no key. Commit, pull request and comment mining use a model and are skipped, with a stated reason, when none is configured.