On this page
- The design in one picture
- What are the five layers of codebase intelligence?
- Layer 1: the graph, built from ASTs
- Layer 2: git history as a signal
- Layers 3 and 4: docs and decisions
- Layer 5: health, computed without a model
- Why three stores?
- Keeping the index fresh
- The MCP server: one call that ends the task
- Decisions we made, and why
- Try it
- FAQ
repowise is one local index built from five layers (the dependency graph, git history, docs, decisions and health), and everything the product does is one of those layers or a combination of them. The index is rebuilt incrementally after each commit and served to people through a CLI and a web dashboard, and to AI agents through ten MCP tools. This post is the codebase intelligence architecture behind that: what each part does, and the decisions that shaped it.
The design in one picture
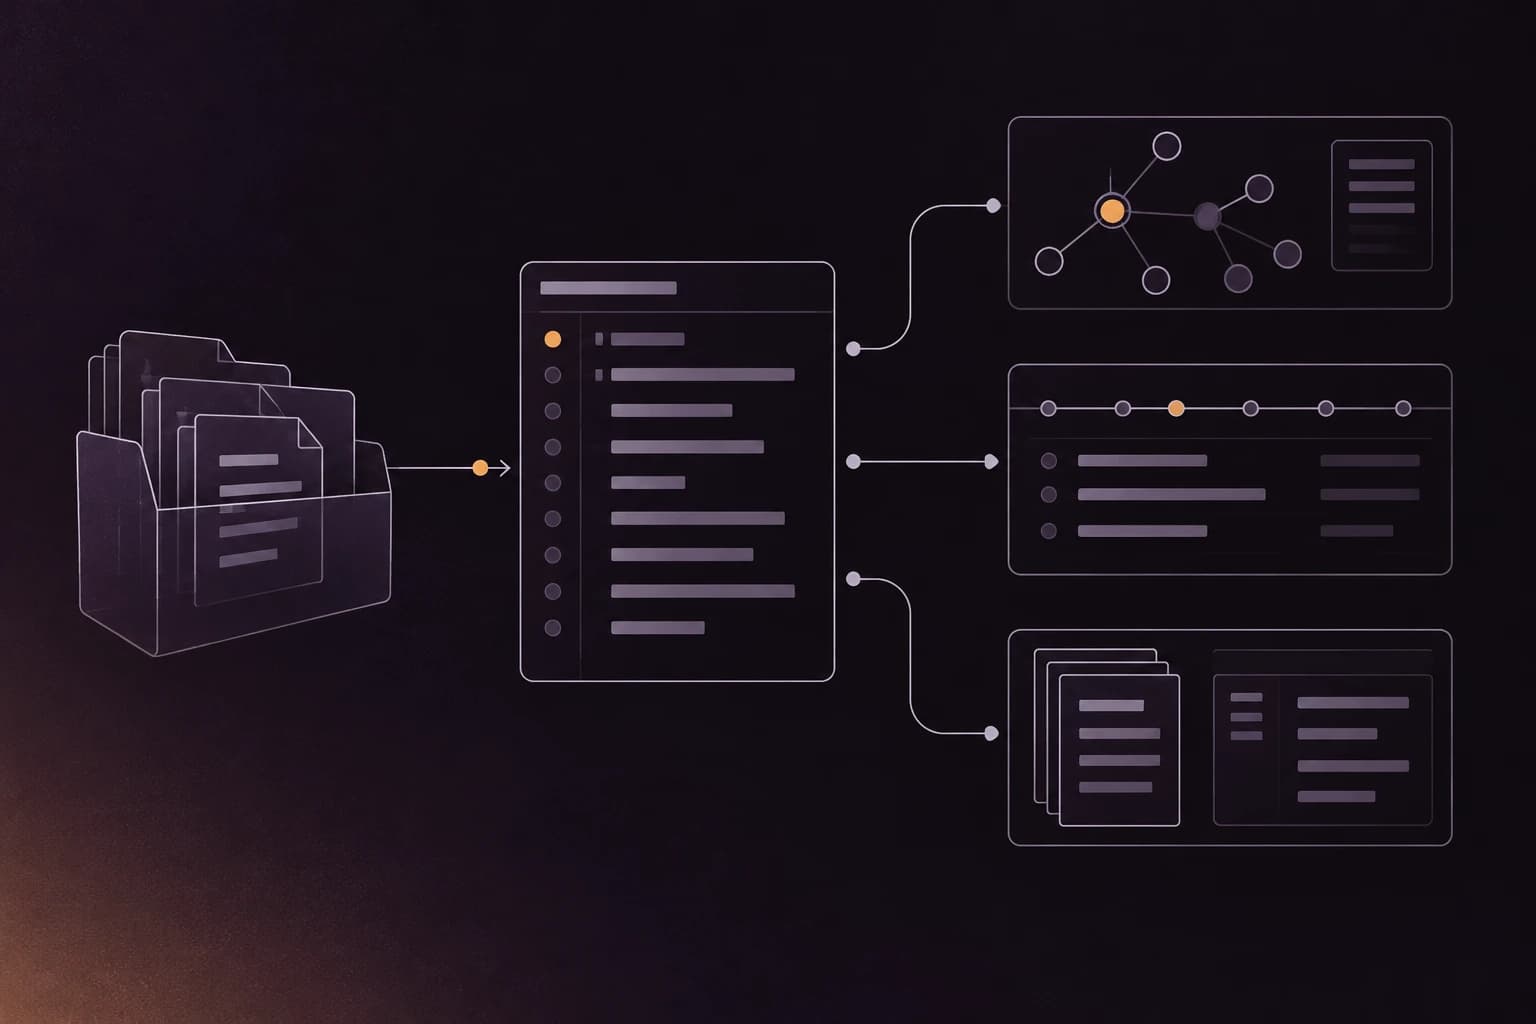
Source code, git history, your markdown and optional coverage reports go in; one index comes out; three kinds of consumer read it. repowise init parses the repository and reads its history once, and repowise update keeps the index current by re-analysing only what changed.
The code is a Python monorepo, chosen because the AST, graph and LLM ecosystems are strongest there:
| Package | Role |
|---|---|
repowise-core | Ingestion, analysis, generation, persistence and LLM providers |
repowise-cli | The repowise command: init, update, dead-code, health, risk, mcp and the rest |
repowise-server | FastAPI REST API, the MCP server, webhooks and the scheduler |
packages/web | The Next.js dashboard |
Scroll the table sideways to see every column.
What are the five layers of codebase intelligence?
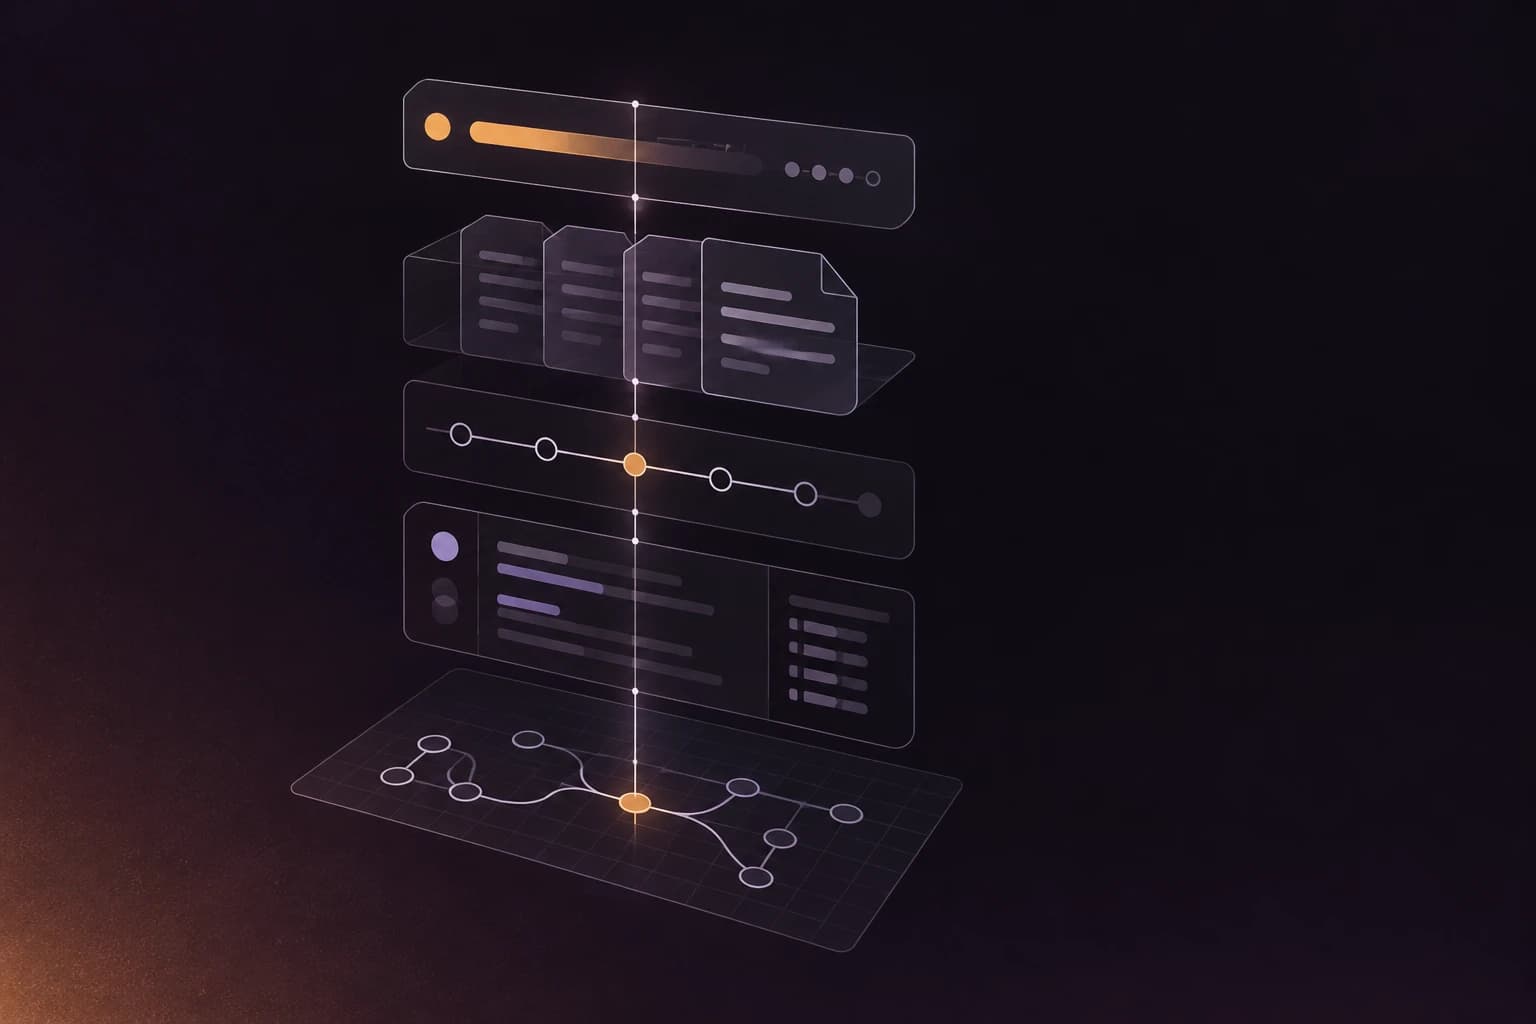
The layers are the graph (what connects to what), git history, docs, decisions and health. Each is built from a different kind of evidence, and each attaches to the files the graph knows about, which is why one question can cross layers in a single call.
| Layer | Question it answers | Built from |
|---|---|---|
| Graph | What is connected to what? | Tree-sitter ASTs, import and call resolution |
| Git history | Who changes this, how often, and with what? | Full git log and blame |
| Docs | What does this code do? | Structure, optionally model-written prose |
| Decisions | Why is it shaped this way? | Commits, comments and decision records |
| Health | Where is it likely to break or hurt? | Static markers over the graph and history |
Scroll the table sideways to see every column.
The rest of this post covers the parts that carry the most design weight.
Layer 1: the graph, built from ASTs
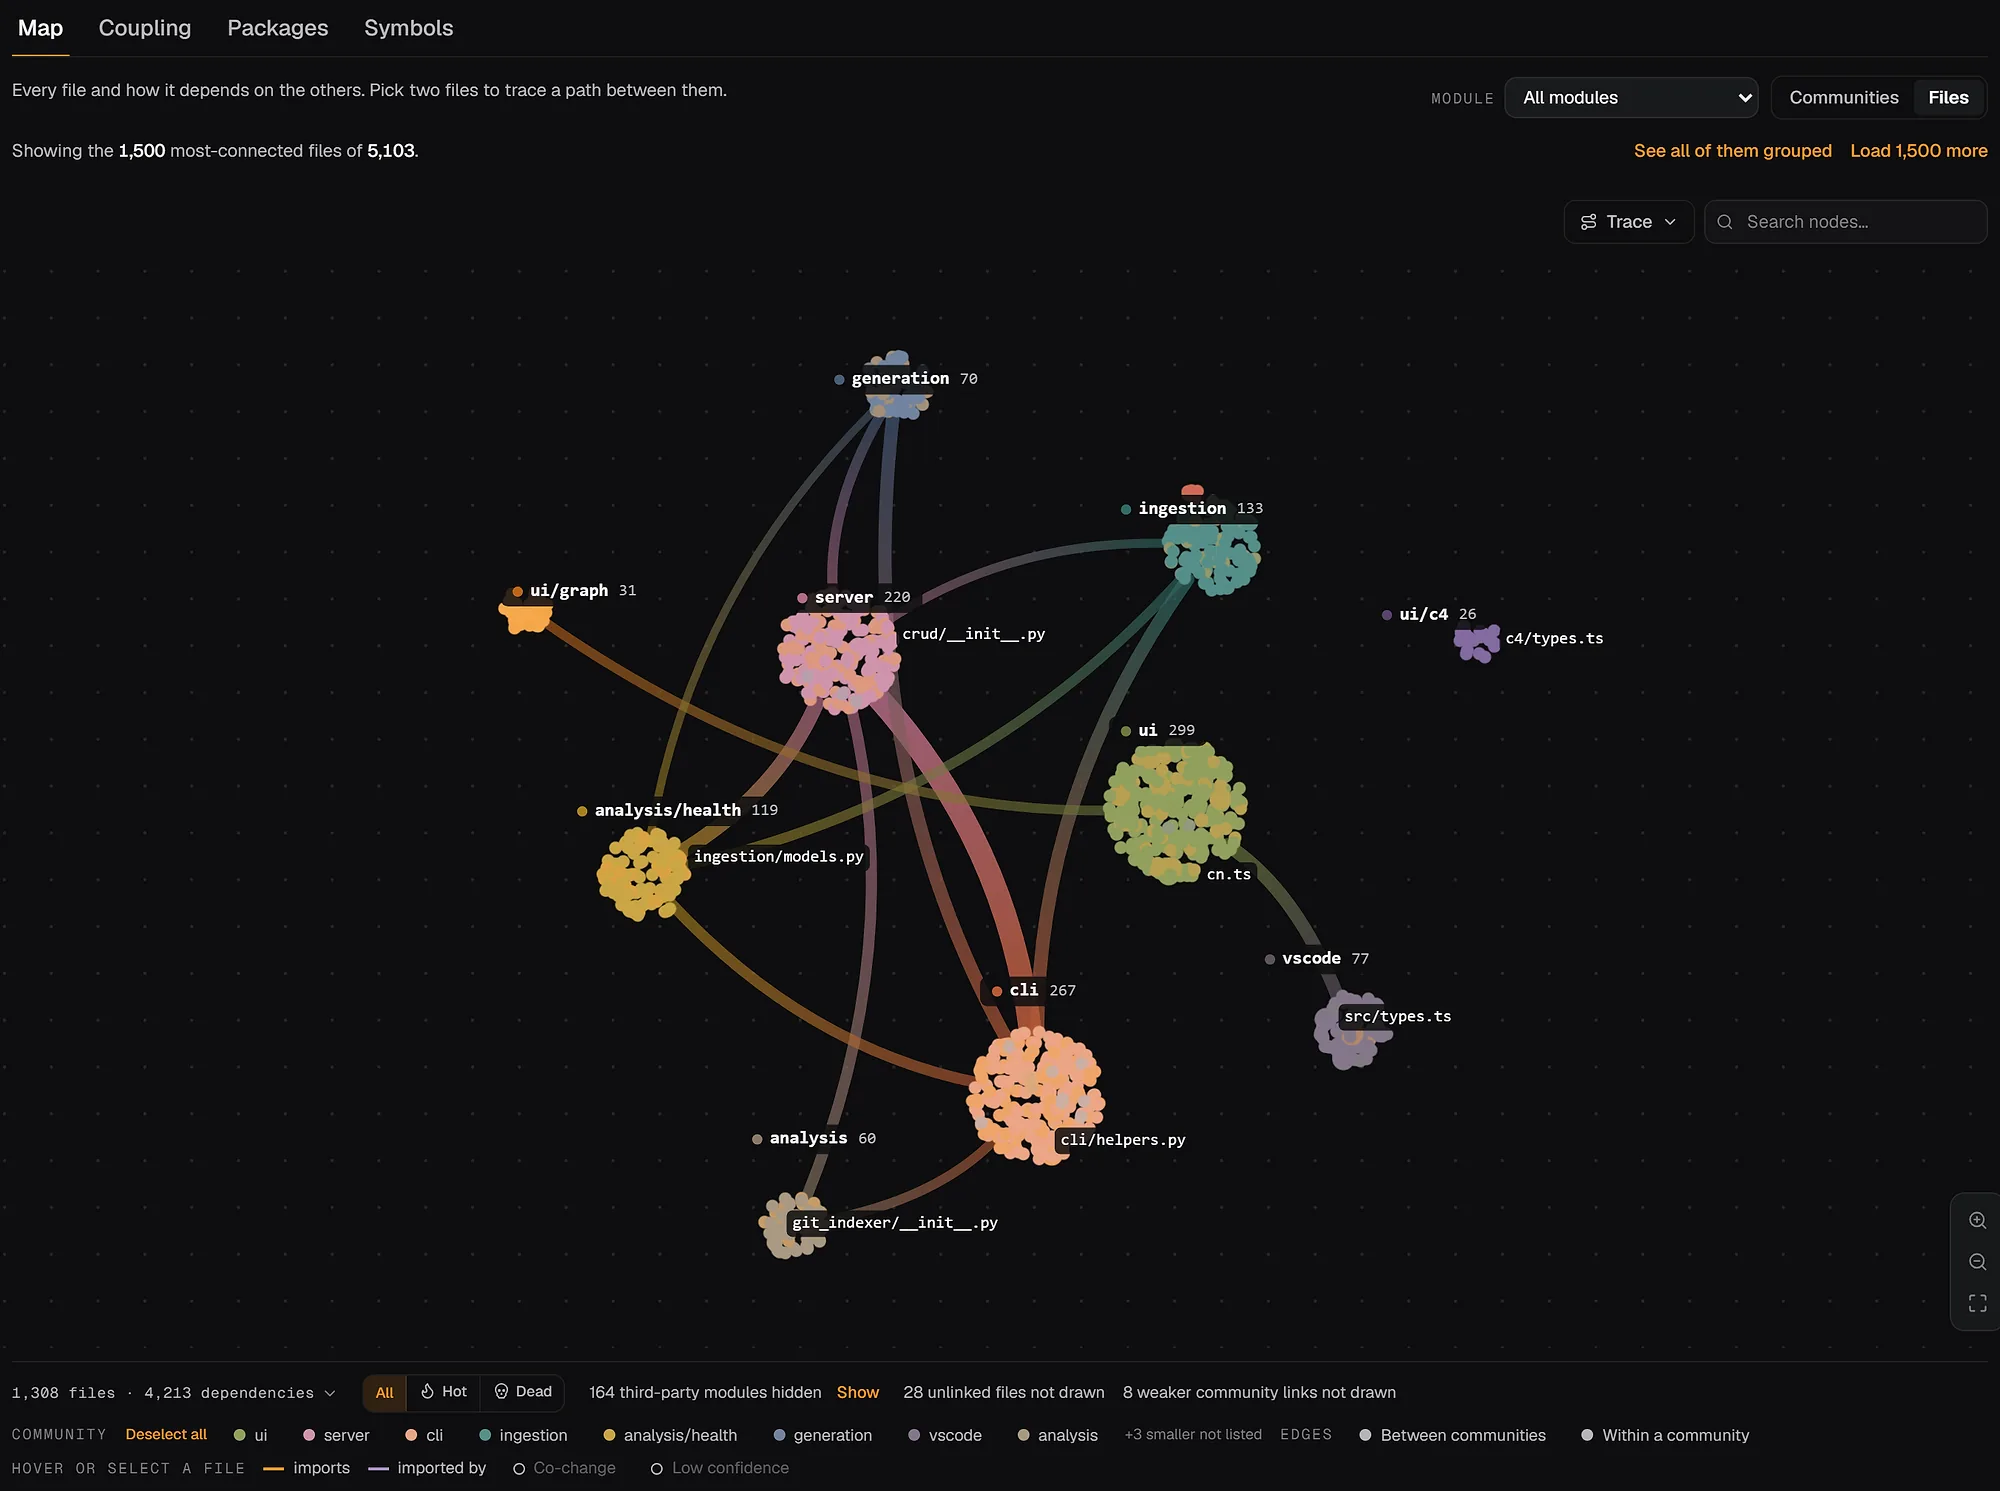
repowise parses 28 languages to a full AST with Tree-sitter and builds a directed graph of files, symbols, imports and calls. Tree-sitter produces a concrete syntax tree, so symbols are identified structurally instead of by regex. One ASTParser class handles every language: a language is one .scm query file plus a config entry, with consistent capture names (@symbol.def, @import.module) across all of them. 15 languages are at the Full tier, where every pipeline stage produces real output.
Calls are the hard part. A CallResolver resolves each call site after the import graph is built and stamps every edge with how it was resolved, from same_file at 0.95 confidence down to global_unique at 0.50, a repo-wide name match. There are 39 named resolution origins and 17 edge types, so a consumer can ask not only who calls a function but how sure the graph is.
Centrality metrics run on a file-level subgraph so symbol nodes do not distort them. PageRank finds the most central files, betweenness finds bridges, strongly connected components find import cycles, and Leiden or Louvain community detection finds the real modules even when the directory layout does not show them. You can see the result for a public project in the FastAPI architecture map.
Layer 2: git history as a signal
Git history adds what a syntax tree cannot: ownership, churn and hidden coupling. The git indexer runs after graph construction and computes, per file, commit volume over 30 and 90 days, the primary owner from blame, the top contributors, and the meaningful commit messages that explain why code changed.
Two signals matter most. A hotspot is a file in the top quartile of decayed churn that also clears absolute activity floors, so quiet repositories do not flag everything. Co-change partners are files that changed in the same commit at least three times with no import between them, which is coupling no static analysis sees. Co-change edges join the graph but are deliberately kept out of PageRank, because files edited together for process reasons would otherwise look architecturally central.
Layers 3 and 4: docs and decisions
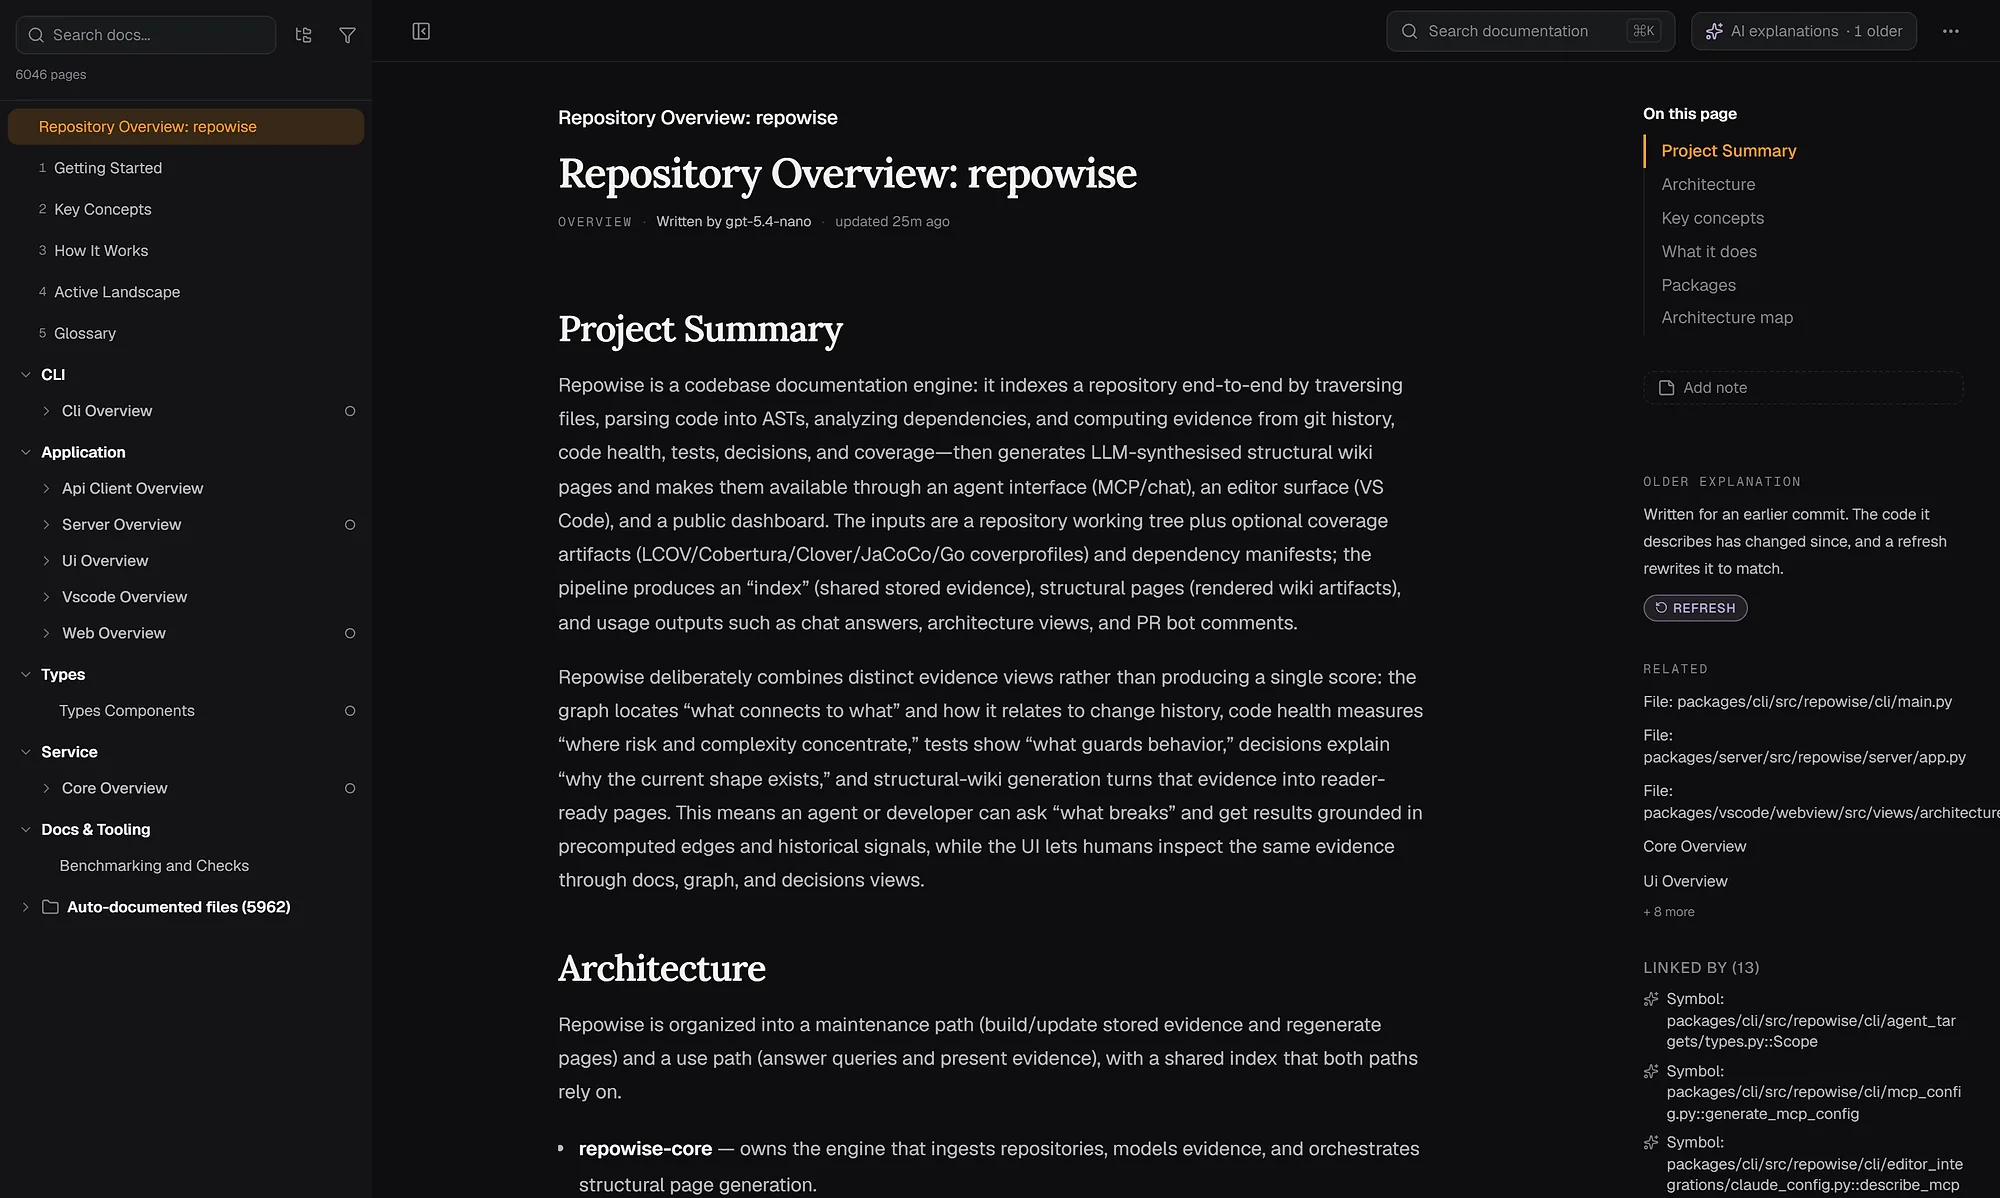
The wiki is rendered from structure first, and a model writes prose only where prose adds value. File, symbol, cycle, API and infrastructure pages come from the parsed structure with no key and no cost. With a provider configured, the subsystem pages, repo overview and onboarding collection are written as model prose. repowise init --no-prose keeps the whole wiki keyless, and repowise generate fills the prose in later.
When a model does write, the ContextAssembler builds the prompt in priority order: source, signatures, graph context, git context, import summaries, retrieved pages, co-change partners and dead-code findings. Git context is the last thing dropped under a token budget, because commit history is what turns "what this does" into "why it exists". Providers sit behind one BaseProvider interface, each described once by a ProviderSpec, covering hosted SDK providers, OpenAI-compatible endpoints, a local Ollama instance and local agent CLIs, so a sensitive repository can stay on one machine.
Decisions are the fourth layer: architectural choices captured from commit history, code comments and records, tied to the files they govern and checked for staleness. They are what get_why reads.
Layer 5: health, computed without a model
Dead code, code health and change risk are static analyses over the graph and the history, so they run in seconds and make no LLM calls. Dead-code detection is graph traversal plus SQL, and it is conservative on purpose: a finding is marked safe to delete only at confidence 0.7 or higher after excluding dynamically loaded paths. Health scores defect, maintainability and performance markers per file, and change risk scores a commit or range from the shape of its diff. Because they share the graph and git layers, a hotspot with many dependents ranks above one with none.
Why three stores?
repowise keeps a SQL store, a vector store and a graph store because each answers a question the other two cannot. This is the decision we would defend first.
| Store | Answers | Implementation |
|---|---|---|
| SQL | What exists, what changed, when | SQLAlchemy over SQLite, PostgreSQL for multi-worker servers |
| Vector | What is semantically similar | LanceDB embedded, pgvector when PostgreSQL is in use |
| Graph | How things connect and how central they are | NetworkX in memory, SQLite-backed networkit above 30,000 nodes |
Scroll the table sideways to see every column.
We started with vector search for everything and learned that vectors answer similarity, not structure. Asked for the dependents of a class, a vector index returns similar classes, not the import list. The graph returns the import list. Semantic search then covers the other half: "where is the authentication logic" works even when no filename says authentication. Full-text search runs on SQLite FTS5, so search works with no embedder at all.
The storage choices favour a local setup. SQLite and LanceDB are embedded, so repowise init creates a .repowise/ folder next to the repository and nothing else runs. NetworkX handles tens of thousands of nodes in-process, which is why we did not take on a graph database server for data that can be rebuilt from source at any time.
| Concern | Embedded (SQLite, LanceDB) | Server (PostgreSQL, pgvector) |
|---|---|---|
| Setup | None, files under .repowise/ | A database to run |
| Best for | One developer or one repository | Multi-worker servers |
| How to select | Default | Set DATABASE_URL |
Scroll the table sideways to see every column.
Keeping the index fresh
repowise update re-analyses only what changed and propagates the change through the graph. The change detector reads the git diff, walks the dependency graph to the pages that reference changed symbols, and decays their confidence instead of marking them fresh or stale. A directly changed page decays sharply and an indirect one gently, and hotspot files decay faster than stable ones. A cascade budget caps how many dependent pages regenerate immediately, ranked by PageRank, so changing a utility imported by 200 files does not rewrite 200 pages on every push. A nightly job catches the rest.
The MCP server: one call that ends the task
The MCP server exposes the index through ten tools, designed so an agent builds a mental model before it opens source. Model Context Protocol is the open standard Claude Code, Codex, Cursor, Cline and other agents use to call local tools. Instead of loading a repository into a context window, an agent asks for what it needs.
| Tool | Use it to |
|---|---|
get_answer | Answer a how, where or why question with cited evidence |
get_overview | Get the architecture map of an unfamiliar repository |
get_context | Triage files, modules or symbols: docs, owners, history, decisions |
get_symbol | Read one verified symbol body |
search_codebase | Find an identifier, path or concept |
get_risk | Check history and structural reach before editing |
get_change_risk | Score the pre-merge defect risk of a commit or range |
get_why | Read the decisions and history behind the code |
get_health | Self-check a change for defect, maintainability and performance findings |
get_dead_code | List unreachable files and unused exports by confidence |
Scroll the table sideways to see every column.
Every response carries its own freshness and completeness metadata, so an agent knows when to trust a result and when to read the file. The tools never edit your code. repowise init registers the server with Claude Code, and repowise mcp starts it over stdio or HTTP.
Decisions we made, and why
Python over Go. Go gives static binaries, but the LLM, embedding and AST ecosystems are first-class in Python, and the Tree-sitter bindings are mature.
Almost everything without a model. Parsing, resolution, git mining, dead code, health and risk are static, so they are fast, repeatable and free. A provider key adds prose and a few extras and never switches a layer on.
One parser class, not one per language. Adding a language is a query file and a config entry, with no change to the parser.
AGPL-3.0, or a commercial license. The core engine stays open and self-hostable, and using repowise inside a company does not require open-sourcing your code.
Local first. The index lives in .repowise/ beside the repository, and with a local model through Ollama no code leaves the machine.
Try it
uv tool install repowise      # or pipx / pip install repowise
repowise init                 # builds the index; no API key needed
repowise mcp                  # serve it to your agent
To see the output before installing, browse the live example repositories, read the architecture documentation, or see what the health layer reports in the code health feature.
FAQ
- What is codebase intelligence?
- Codebase intelligence is a queryable model of a repository built from its code structure, git history, documentation and decisions, rather than from the text alone. It answers questions about connections, ownership, risk and intent that grep and embeddings cannot answer individually.
- How does repowise handle very large repositories?
- It indexes incrementally: after the first scan,
repowise updatere-parses only changed files and their dependents. Above 30,000 graph nodes the graph moves to a SQLite-backed store so only the subgraph an operation needs is loaded. - Does repowise need an LLM key?
- No. Parsing, the graph, git history, dead code, health, risk and the structural wiki all run with no key. A provider adds model-written prose for the subsystem pages and overview, and
repowise init --no-proseskips it entirely. - Can I use repowise on private code?
- Yes. The open-source version runs on your machine and keeps its index in
.repowise/next to the repository. With a local model through Ollama, no code is sent to a model provider. - Does repowise support monorepos?
- Yes. The traverser detects multiple package manifests, treats each package as a semi-independent unit, and tracks cross-package edges in the graph. Workspace mode extends this to several repositories.