On this page
- How do you build a dependency graph?
- Why resolution is the hard part
- What a dependency graph tells you
- PageRank: which files are load-bearing
- Community detection: the modules you really have
- Cycle analysis: circular dependencies
- Fan-in and fan-out
- How repowise builds the graph
- How accurate is the graph?
- Reading the graph
- What teams do with it
- FAQ
A code dependency graph is a directed graph where each file is a node and each import is an edge, built by parsing every file into a syntax tree and resolving each import to the file it names. Once you have it, three algorithms answer most structural questions: PageRank finds the files everything depends on, community detection finds the modules your code actually has, and strongly connected components find the circular dependencies. This post covers how the graph is built, where each language makes it hard, and how to get one for your repository.
Part of the Architecture guide.
How do you build a dependency graph?
You parse, resolve, then model. Three steps, and the second is where tools differ.
- Parse each file into an abstract syntax tree (AST), so a real import is never confused with a comment or a string that looks like a path.
- Resolve each import to a concrete file or package, using the language's own module rules.
- Model the result as a directed graph: nodes are files (or packages), and an edge
A -> Bmeans A imports B.
A grep for import fails the first step immediately. It counts commented-out lines, misses dynamic imports and cannot follow a re-export through a barrel file.
In TypeScript alone, a parser has to handle four shapes:
import { func } from "./module";          // static
const m = await import("./module");       // dynamic
export * from "./module";                 // re-export
import type { User } from "./types";      // type-only
Why resolution is the hard part
Extracting the import string is easy; knowing which file it points at is the work. Each ecosystem has its own answer.
| Language | What the resolver has to know |
|---|---|
| Python | Package layout from __init__.py, so from ..utils import helper lands on the right sibling. Imports inside functions count too |
| TypeScript / JavaScript | ESM and CommonJS, plus path aliases from tsconfig.json, so @/components/Button maps to the real file |
| Go | Imports name packages, not files. Every file in a directory shares one package, so file paths must map to package names |
| Rust | mod declarations and mod.rs define the tree, and crate boundaries separate internal modules from external dependencies |
| Java, C#, Kotlin | Package or namespace membership, with sibling files visible without an import |
Scroll the table sideways to see every column.
A tool that skips alias resolution draws a broken graph: the import is seen, the target is never found, and the edge silently disappears. Third-party packages are better kept as lightweight external nodes, so a dependency is visible without being analysed.
If you only need one ecosystem, purpose-built tools do it well. madge draws module graphs and runs madge --circular src/app.js for JavaScript. dependency-cruiser validates and visualises dependencies against rules for JavaScript and TypeScript (as of October 2026). A polyglot repository needs one resolver per language behind one graph, which is what the rest of this post describes.
What a dependency graph tells you
Four measurements cover most of what a team wants to know.
PageRank: which files are load-bearing
PageRank scores a file highly when many important files depend on it. The top of that ranking is your core: the files where a bug is a systemic failure and a refactor needs care. A high-PageRank file that also changes often is a hotspot, the strongest structural risk signal there is. In repowise, centrality is computed over the import and call edges only. Co-change edges are excluded, because "changes alongside many things" is not "many things depend on it".
Community detection: the modules you really have
Leiden clustering (with Louvain as fallback) groups files that are densely connected to each other and sparsely connected to the rest. These communities are often the true logical modules. When they disagree with your folder layout, the folders are misleading you.
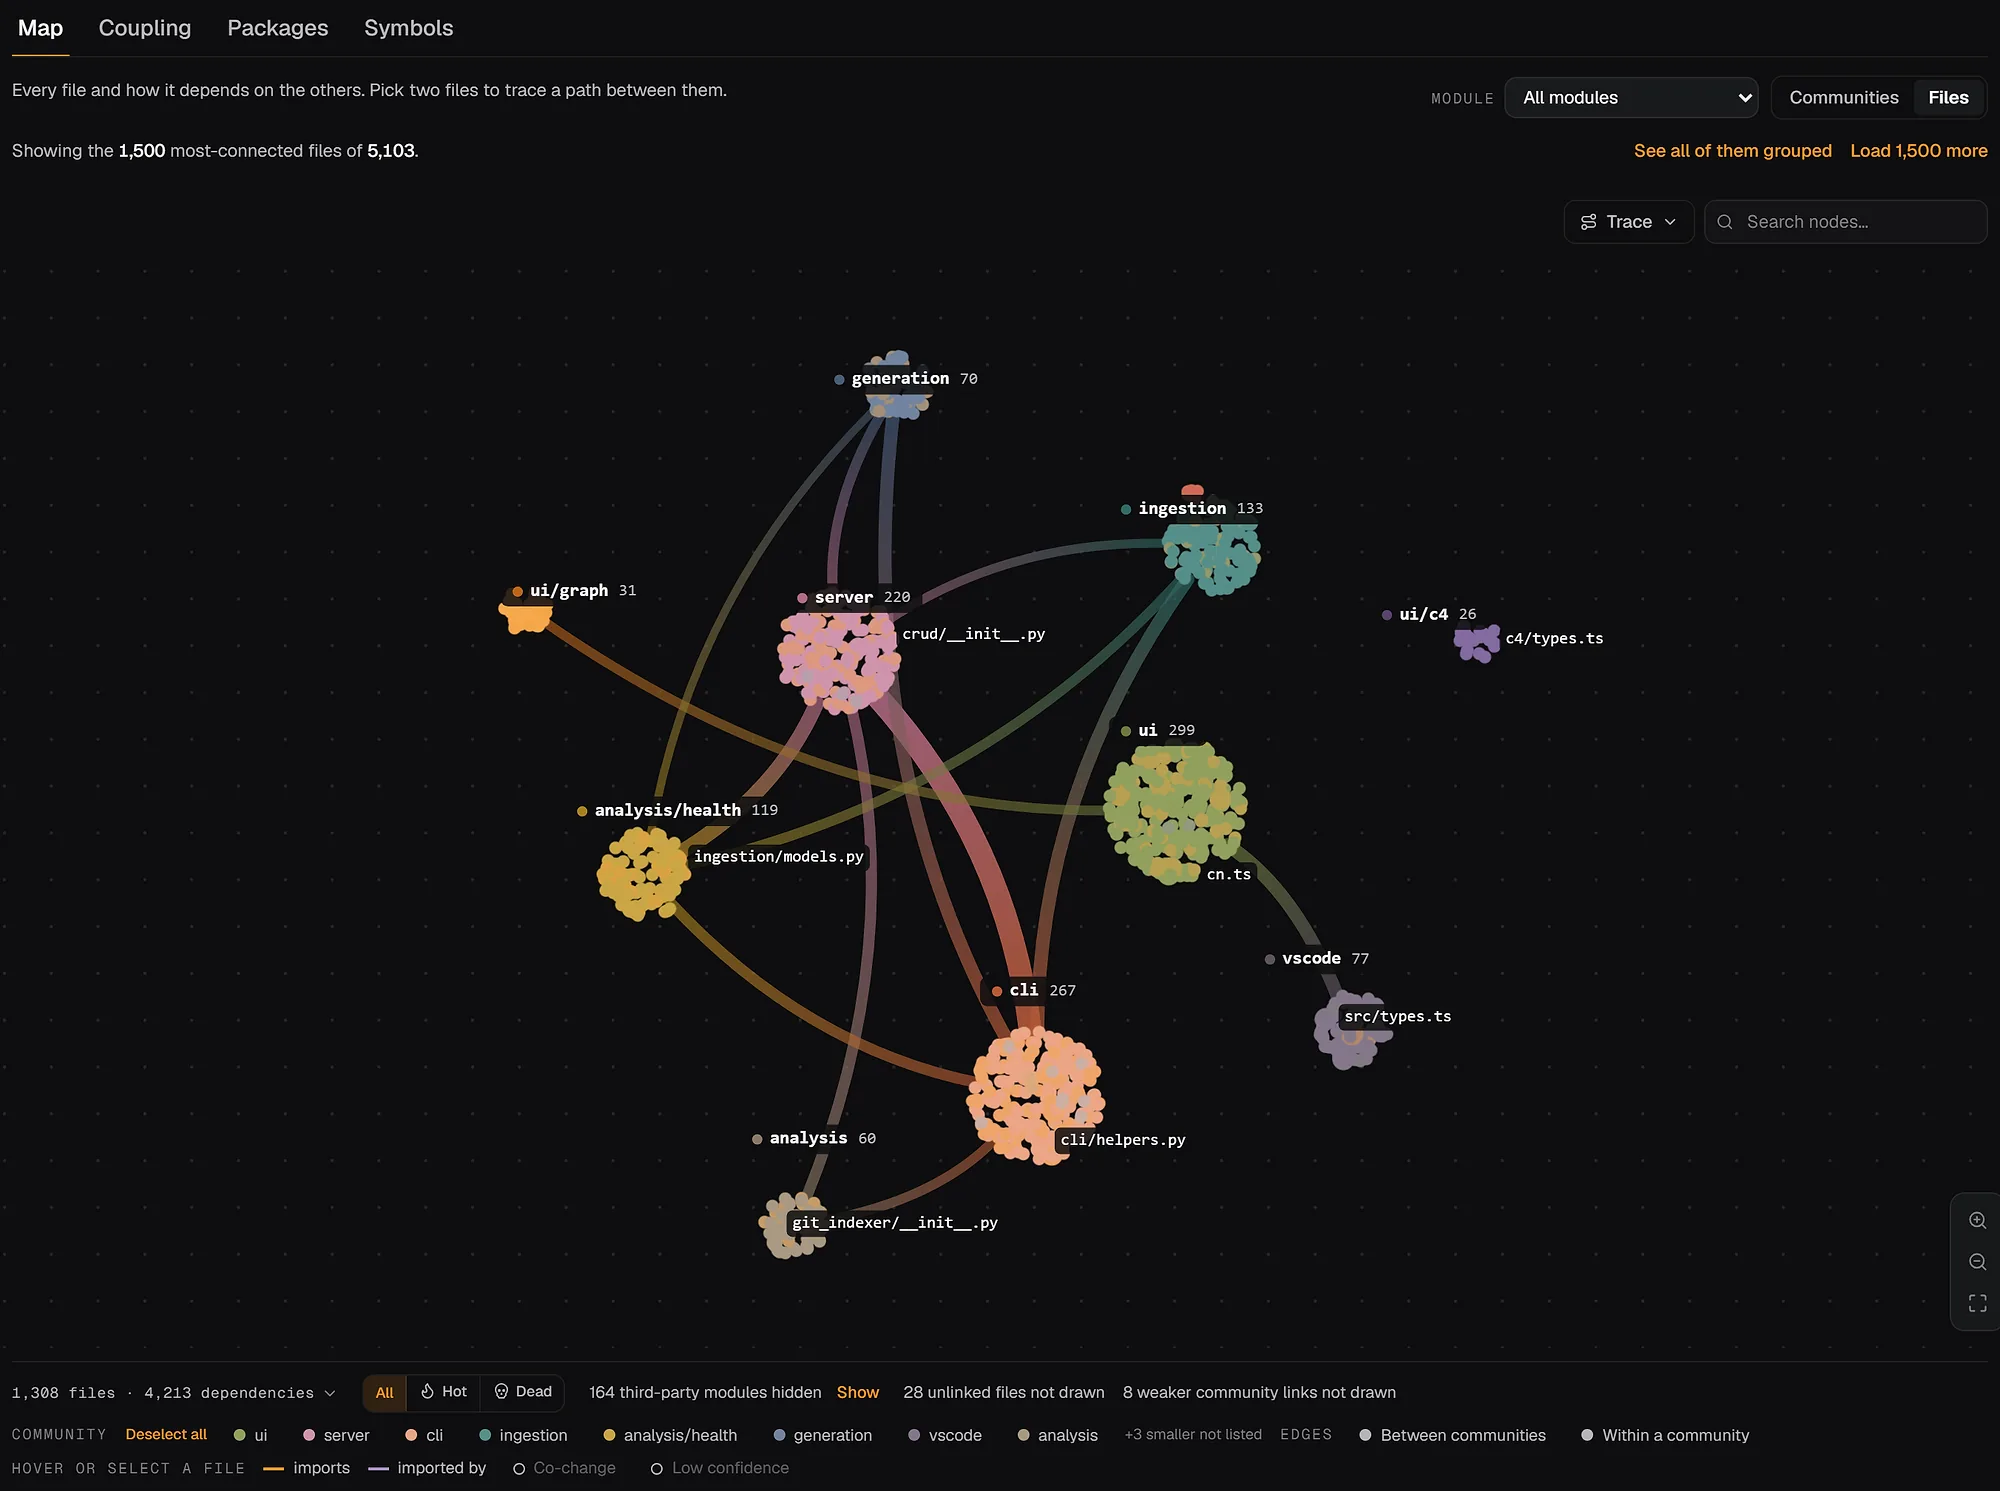
The Architecture map in the repowise dashboard, shown on repowise's own repository: files grouped by community, edges weighted by how many imports cross between them.
Cycle analysis: circular dependencies
If A -> B -> C -> A, you cannot test A without B and C. Strongly connected components find every such group directly. Breaking the weakest edge in each returns that part of the graph to an acyclic shape.
Fan-in and fan-out
Fan-in counts the files that import a file; high fan-in marks a stable, reusable component. Fan-out counts what a file imports; high fan-out marks a coordinator. A file high on both is usually a God Object that should be split.
How repowise builds the graph
repowise builds a two-tier graph during repowise init, with no model calls and no network. One tier holds files and packages. The other holds functions, classes, methods and interfaces. It covers 28 languages parsed to a full AST, and it needs no LLM key.
repowise init                                    # builds the graph; no API key needed
repowise context src/app.py --include callers    # who depends on this file, with confidence
repowise serve                                   # dashboard: Graph, Architecture, Coupling, Blast radius
Two design choices set it apart from a plain import graph.
Every call edge says how it was found. A call like user.save() can be resolved by working out what user is, or by guessing from the method name. repowise stamps each edge with a named resolution origin (39 in total), each with one fixed confidence, from 0.95 for a call in the same file down to 0.50 for a repo-wide unique name. Agents and reviewers can then act on 0.9 edges and treat 0.5 edges as leads.
Structure and history stay separate. Imports, calls and inheritance are one family of edges. Files that keep changing together without importing each other are another (co_changes). Both are real signal, but mixing them would put "edited in the same commit" into your import graph. The git intelligence guide covers the history side.
How accurate is the graph?
We measure edges against answer keys we do not control. Against the Go and TypeScript compilers, call-edge precision runs 0.976 to 0.995, and in 7 of 7 compiler-graded cells no tool in the five-tool comparison beats both our precision and recall. In a hand-graded audit of 280 call edges across nine languages, 85.7% were correct, against 58.6% for CodeGraph 1.5.0. Method, per-language tables and source data are on the benchmarks page.
Reading the graph
The same graph is available in four places:
- Dashboard:
repowise serveopens the Graph, Architecture, Coupling, Blast radius, Knowledge graph and Dead code views. Pick two files on the map and trace a path between them. - CLI:
repowise context <file> --include callerslists dependents with confidence. - MCP:
get_contextreturns dependencies, dependents and co-change partners, andget_symbolreturns a verified body. The opt-inget_dependency_path(source, target)returns the shortest path between two files, and when none exists it returns the nearest common ancestors and bridge suggestions to debug the gap. - Workspaces: across several repositories, a service-level graph adds declared dependency rules, cycle detection and an architecture score.
get_dependency_path(source="src/api/routes.py", target="src/db/models.py")
Ask an agent "how does the API layer reach the models?" and it can answer from that path instead of reading directories.
What teams do with it
Architecture reviews. The graph shows what the architecture is, not what the diagram says it is, so drift past a boundary is visible. Browse a live example on the FastAPI architecture view.
Refactor planning. Before moving a module, list every dependent that needs a new import. The blast radius view walks dependency edges from a changed file and shows the downstream set, with confidence attached to each hop.
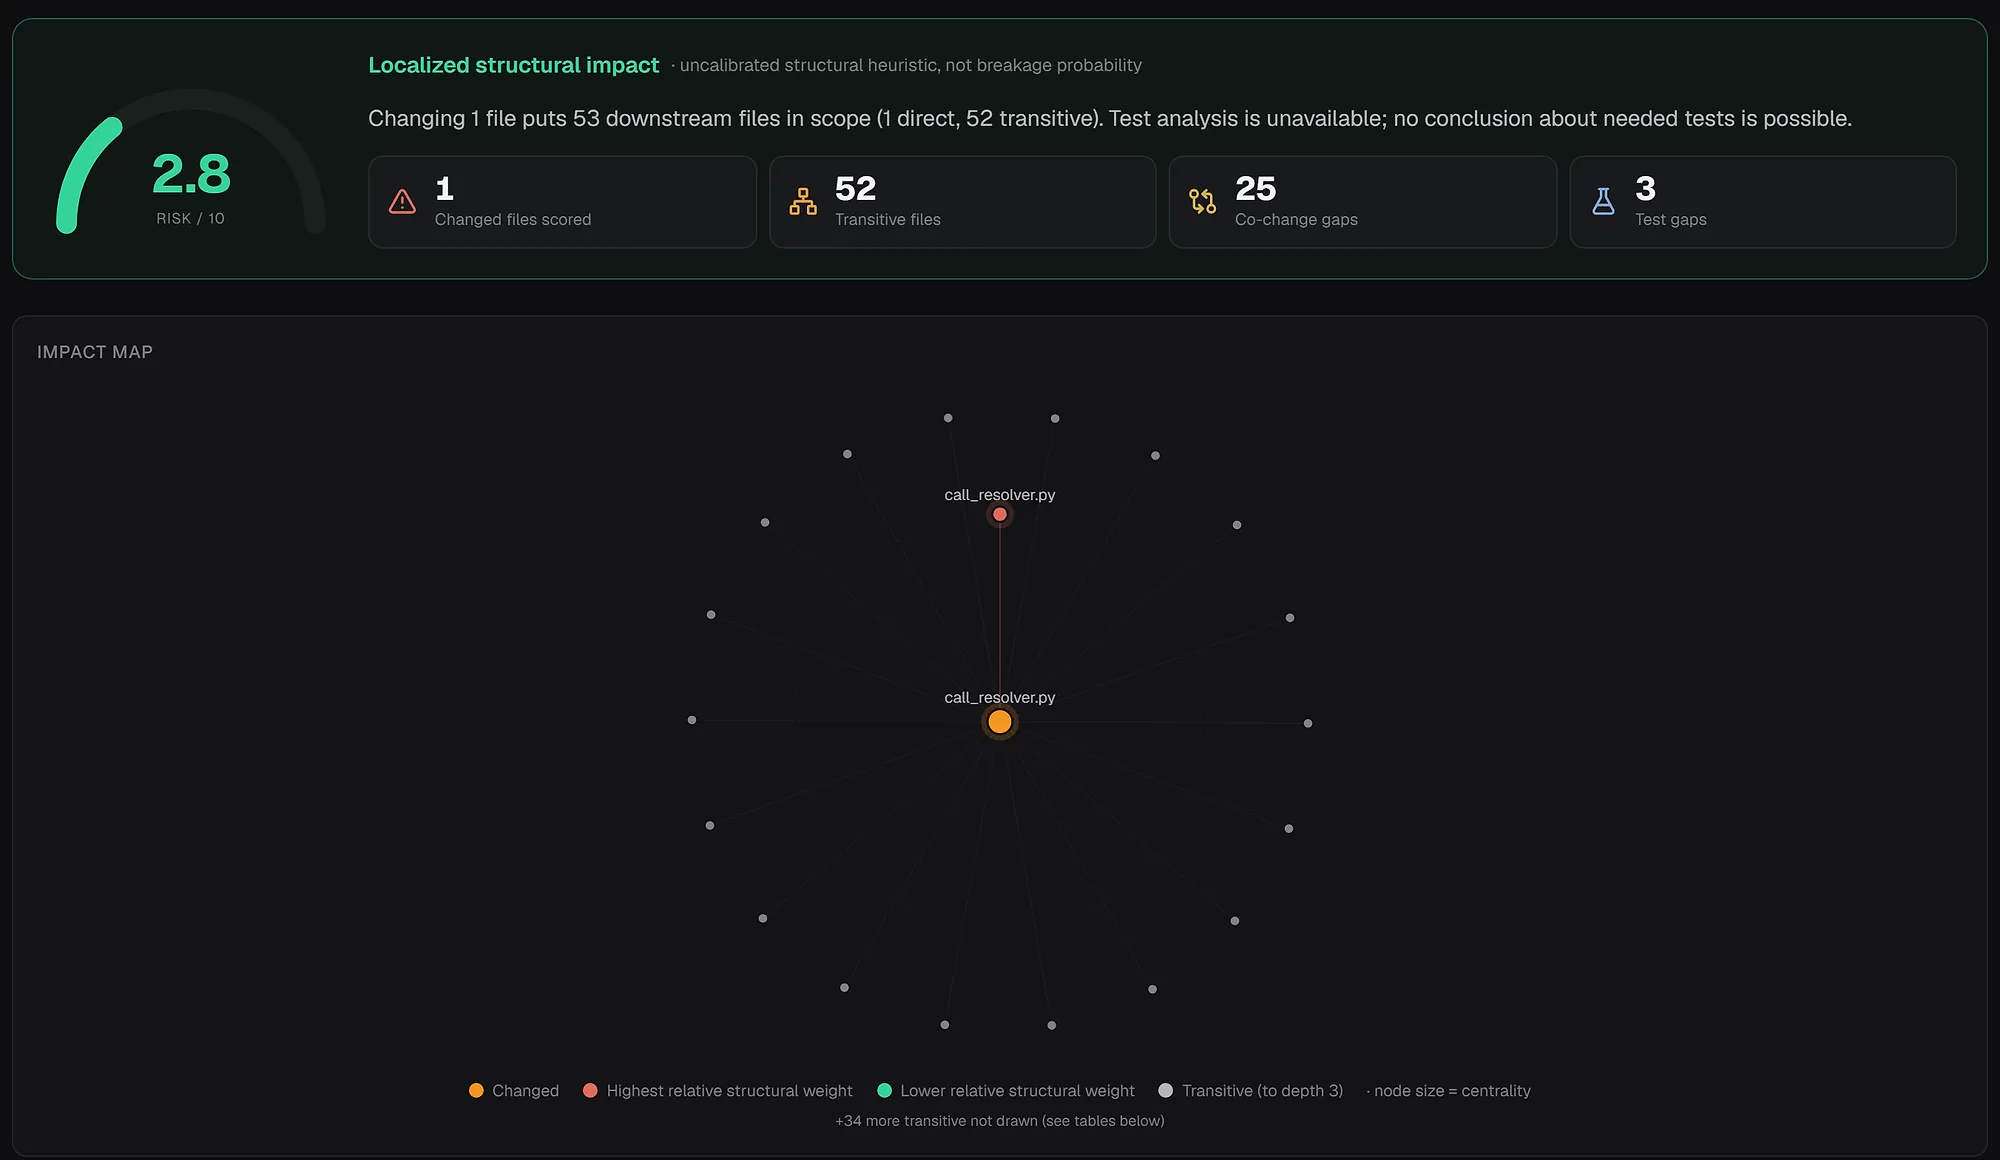
Blast radius for one changed file in repowise's own repository: the impact map draws the changed file at the centre and the downstream files it can reach.
Dead code. Reachability over the graph finds files and exports nothing reaches. A symbol reached only through a framework, a dispatch table or a type reference is not dead, which is why those are distinct edge types. See how to find dead code.
Onboarding. Follow edges from an entry point such as main.go or index.ts to trace how control and data move, instead of reading folders top to bottom.
FAQ
- Can I generate a dependency graph for a polyglot repository?
- Yes. repowise parses 28 languages into one graph, so a Python backend and a TypeScript frontend in the same repository appear together. Single-language tools such as madge or dependency-cruiser cover JavaScript and TypeScript only.
- How is a dependency graph different from an import linter?
- A linter checks rules, such as "never import X from Y". A graph is the whole structure, which supports global analysis a linter cannot do: PageRank, community detection and cycle finding across every file at once.
- Do I need an LLM or API key to build the graph?
- No. The graph is built from the syntax tree and git history with no model calls, so it is reproducible and indexing needs no key. An LLM is an optional upgrade for the generated wiki prose only.
- How do I find circular dependencies?
- Find the strongly connected components of the file graph. For JavaScript alone,
madge --circular src/does this. repowise reports cycles across all supported languages from the same index. - Is the graph kept up to date?
- Yes.
repowise updaterefreshes the graph incrementally from the files that changed, and CI can run it on every commit.