On this page
- Why grep is not enough for semantic code search
- How semantic search over code works
- What to embed: documentation, not raw code
- Embedding model choice
- LanceDB or pgvector?
- Searching with search_codebase
- Three queries, grep against semantic search
- Keeping search quality high
- How semantic search compares with grep and GitHub code search
- Try it
- FAQ
Semantic code search embeds your code, or the documentation written about it, as vectors and returns the nearest matches to a natural-language query, so "where do we throttle requests?" finds a RateLimiter class that never uses the word "throttle". For storage, LanceDB is the embedded choice with no server to run, and pgvector is the choice when your team already runs PostgreSQL. repowise uses both: LanceDB on a SQLite install, pgvector on PostgreSQL, selected from your database URL.
Why grep is not enough for semantic code search
Grep matches characters, and a codebase names the same idea many ways. Search for get_user_balance and you will never find fetch_account_equity, even though they do the same job.
The failure shows up when you search by concept. Looking for the grace period on subscription cancellations, you grep "grace", "cancel" and "subscription" and get log lines, test mocks and variable declarations. Semantic search starts from the question instead. Queries such as these resolve to the right module:
- "Where do we validate JWT tokens?"
- "How do we handle database retries in the worker service?"
- "Find the logic that calculates shipping for international orders."
Grep stays the right tool for an exact error string or a known identifier. Semantic search covers the cases where you do not know the name yet.
How semantic search over code works
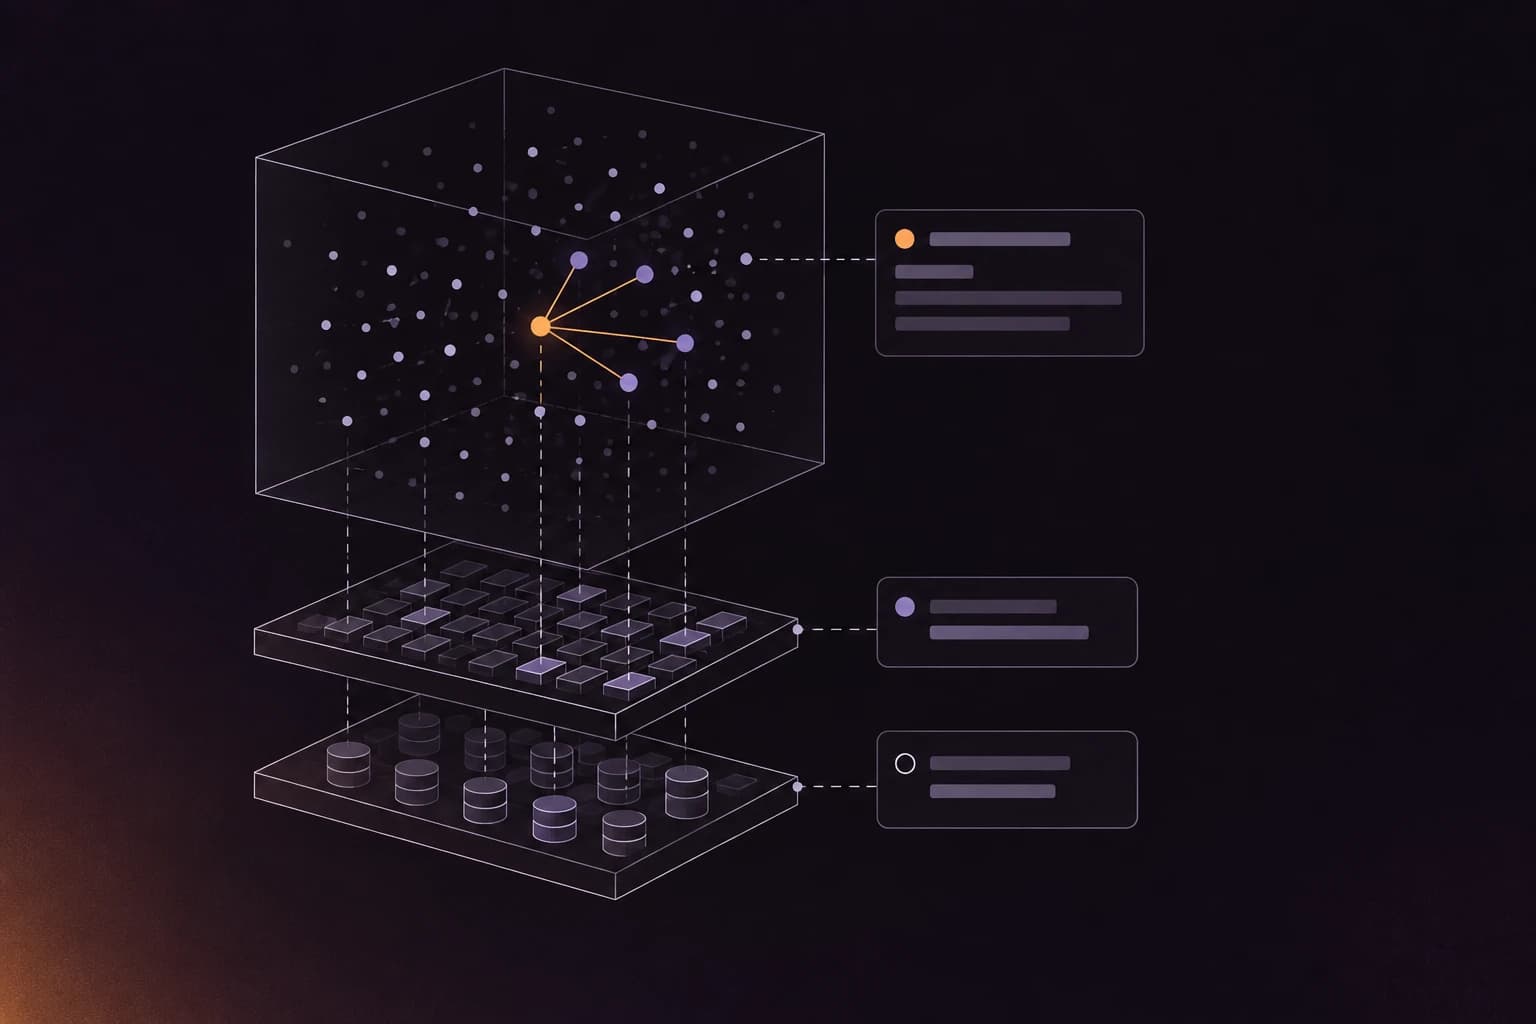
A semantic search pipeline has four steps: embed, store, embed the query, rank. Each step has a choice that affects quality.
- Embed. An embedding model turns a piece of text into a vector of a few hundred to a few thousand numbers. Texts with similar meaning land close together.
- Store. The vectors go into an index built for nearest-neighbour lookup, usually HNSW or IVF-based, so a query does not scan every row.
- Embed the query. The user's question goes through the same model.
- Rank. The store returns the vectors nearest the query by cosine distance, best first.
What to embed: documentation, not raw code
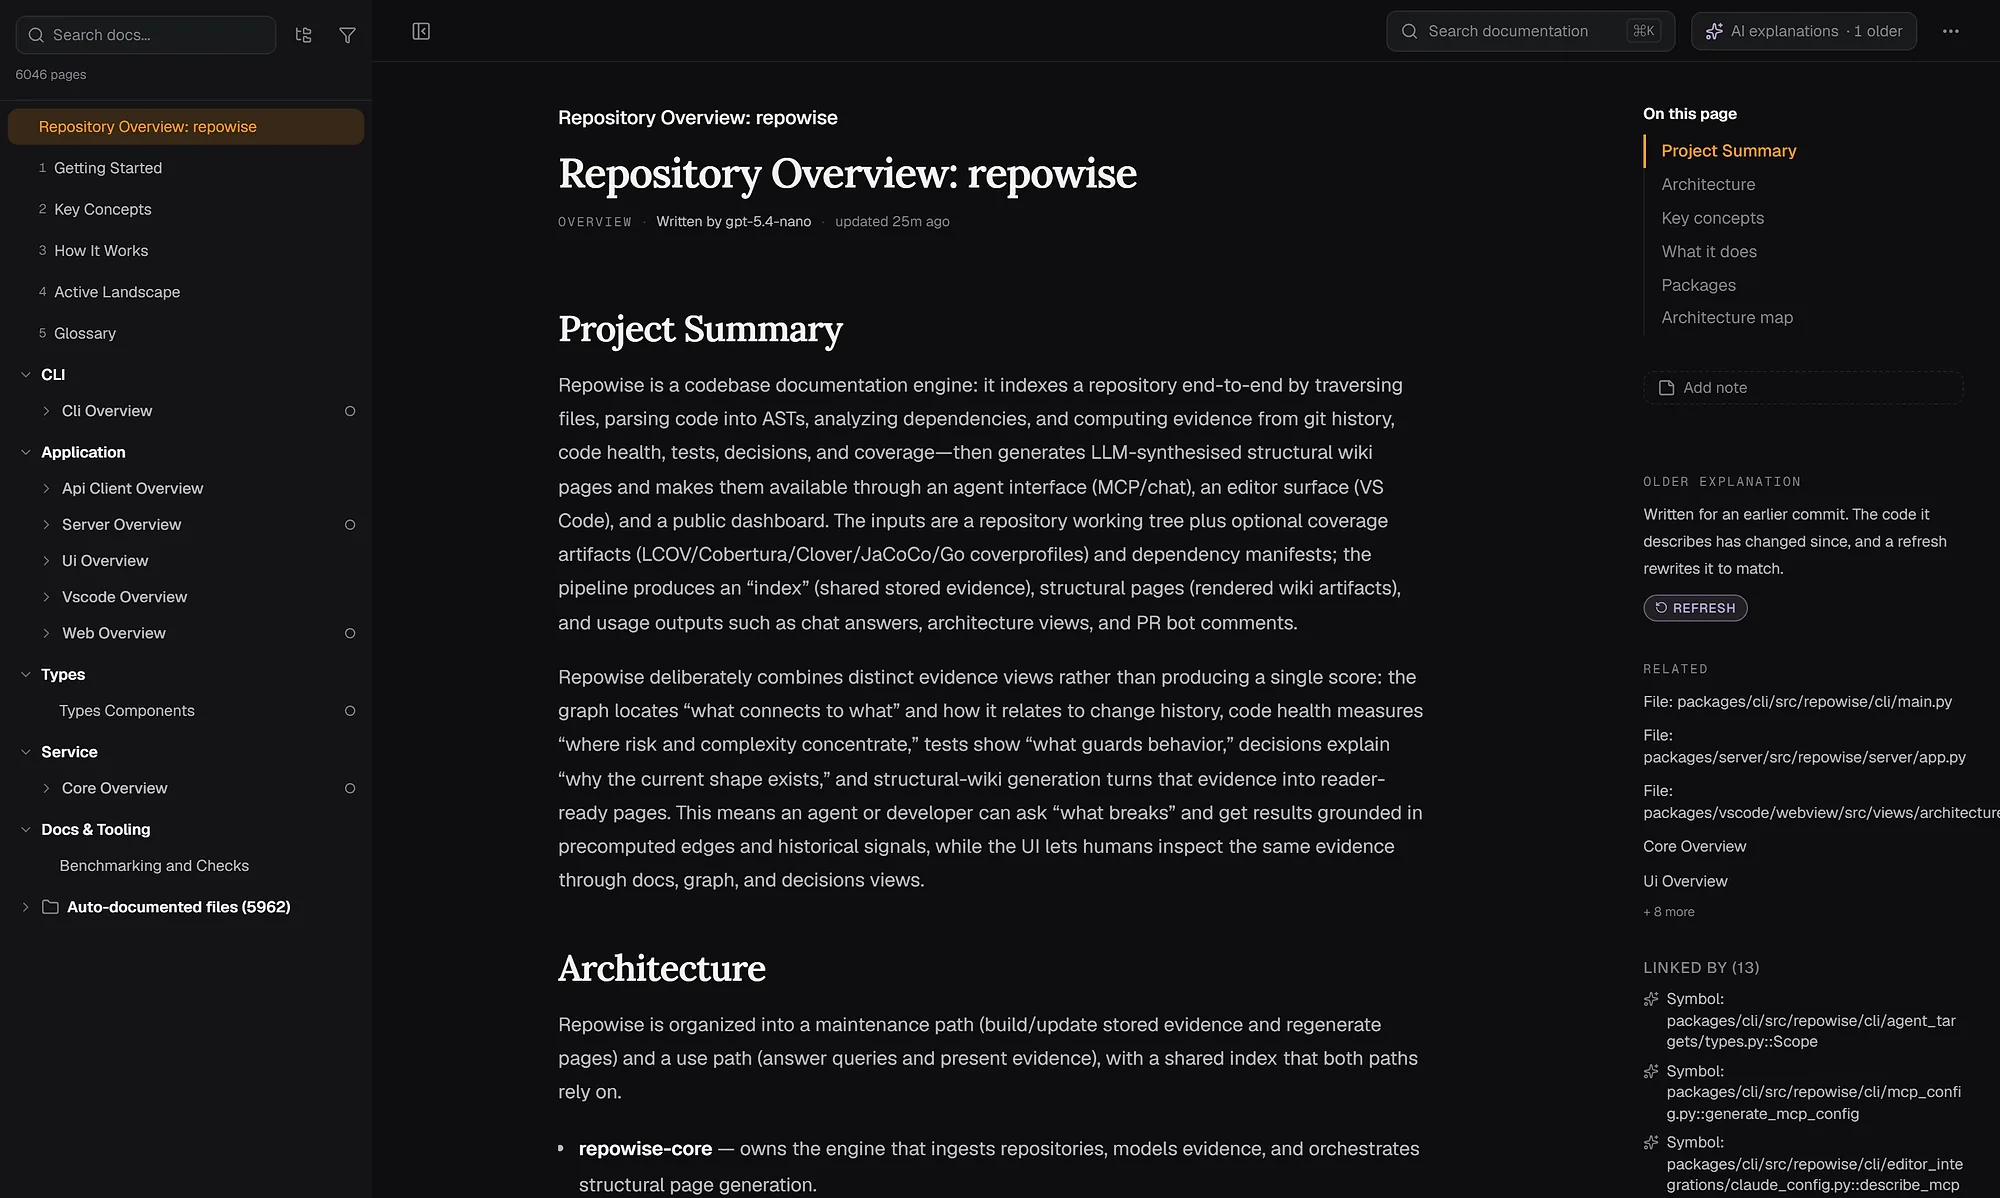
Embed the description of the code, not the code. Raw source carries imports, boilerplate and local variable names that dilute meaning, and a user's question is written in prose. repowise embeds each generated wiki page, one per file and module, so the vector represents what the code does and why it exists.
Pages follow the structure the parser already knows, a file or a module, rather than fixed token windows, so a vector stands for one unit of logic. Each page is embedded right after it is generated, and the same index feeds the context used to write the next page: a file's page is written knowing what the files it imports actually do.
Embedding model choice
The embedder is configured separately from the language model that writes pages. repowise supports these embedders (see the configuration reference):
| Embedder | Needs | Notes |
|---|---|---|
gemini | GEMINI_API_KEY | Default when the key is present |
openai | OPENAI_API_KEY | text-embedding-3-small by default |
openrouter | OPENROUTER_API_KEY | Routed through OpenRouter |
ollama | OLLAMA_EMBEDDING_MODEL | Runs locally, no API key, code stays on your machine |
Scroll the table sideways to see every column.
REPOWISE_EMBEDDING_MODEL overrides the model for any embedder. To switch models, run repowise reindex --embedder gemini. It re-embeds existing pages with embedding calls only, no language-model calls, and records the embedder in config.yaml so queries and writes use the same vector width.
LanceDB or pgvector?
Use LanceDB when the index lives next to one developer or one install; use pgvector when the index should live in the database your team already operates.
LanceDB is an embedded vector database that runs inside your process and stores data in the Lance columnar format, with SDKs for Python, JavaScript and TypeScript, Java and Rust. pgvector is an open-source PostgreSQL extension that adds a vector type, distance operators (<-> L2, <=> cosine, <#> inner product) and HNSW and IVFFlat indexes.
| LanceDB | pgvector | |
|---|---|---|
| Architecture | Embedded library, no server | Extension inside PostgreSQL |
| Setup | pip install, a local directory | Enable the extension, add a vector column |
| Where data lives | Local disk or object storage | Your PostgreSQL tables |
| Query | Python and JS API, SQL-style filters | Plain SQL, joins with relational data |
| Index | IVF-PQ, HNSW | HNSW, IVFFlat |
| Backup | Copy the directory | Your normal pg_dump and backups |
| Fits | CLI tools, local agents, single-user installs | Shared, multi-worker team deployments |
Scroll the table sideways to see every column.
In repowise the choice is automatic. A SQLite install stores vectors in .repowise/lancedb/. A PostgreSQL install adds an embedding vector(N) column to the wiki_pages table and queries it with <=> cosine distance over an HNSW index, so there is no second storage system to back up. Both sit behind one VectorStore abstraction, which is why switching databases does not change how search behaves.
Searching with search_codebase
search_codebase is one of the ten MCP tools. It routes by the shape of the query: identifiers search the symbol index, paths resolve files, prose runs semantic search over wiki pages, and mixed queries run both. A concept hit carries a relevance score and a snippet, and each result names its file so an agent can open it next.
search_codebase(query="how is rate limiting applied to the API?")
search_codebase(query="login", mode="symbol", symbol_kind="method")
search_codebase(query="billing webhook", kind="implementation")
For a question that needs an answer rather than a list of hits, get_answer runs the same retrieval internally and returns a cited answer. Use search_codebase when you want the ranked hits themselves: to enumerate matches, resolve an identifier to a symbol id, or scope a later get_context call. The full parameter list is in the MCP tools reference.
You can try the same search without installing anything on the FastAPI wiki, which repowise indexed from the public repository.
Three queries, grep against semantic search
| Question | grep result | Semantic result |
|---|---|---|
| "Where is authentication handled?" | Every auth in tests, vendored code and CSS | The middleware and identity modules whose pages describe session validation |
| "Find the rate limiting logic" | Nothing, if the code says "throttling" or "quota" | The limiter class, because the embedding treats the terms as close |
| "How does billing work?" | Every file naming invoice, price or stripe | The billing module page, with the flow from checkout to webhook handlers |
Scroll the table sideways to see every column.
Keeping search quality high
Search quality tracks the quality and freshness of what you embed. Three habits matter most.
- Keep the pages current. An embedding of a stale page points at old behaviour. repowise tracks whether each page still matches its code and refreshes pages when files change, so the index follows the repository. See keeping codebase documentation current.
- Pin the embedder. Vectors from different models and widths do not compare. The
embedderkey inconfig.yamlrecords what built the store, and queries read it from there. - Rebuild after deleting the store. If you remove the LanceDB directory or the pgvector embeddings, run
repowise reindex. It rebuilds the index from existing pages.
How semantic search compares with grep and GitHub code search
| grep and ripgrep | GitHub code search | repowise semantic search | |
|---|---|---|---|
| Matching | Exact string or regex | Exact terms and symbol search | Meaning, plus symbol and path routing |
| Synonyms | No | No | Yes |
| Natural-language questions | No | No | Yes |
| Runs on | Your files | GitHub-hosted repositories | Your index, local or hosted |
Scroll the table sideways to see every column.
Pick grep for an exact string you already know. Pick semantic search when you know what the code does but not what it is called. search_codebase routes identifiers to the symbol index, so one call covers both cases.
Try it
pip install repowise
repowise init
repowise search "where do we validate session tokens"
Add --embedder ollama to keep embeddings on your machine. To see what an index looks like first, browse the live examples or read how repowise is built.
FAQ
- Does semantic search replace grep?
- No. Grep is better for an exact error string or a variable name you already know. Semantic search is for discovery, when you know the behaviour but not the name. repowise routes each query to the right index, so you do not choose between them.
- Is my code sent to an LLM?
- Only if you pick a hosted embedder such as
openaiorgemini, in which case the text being embedded is sent to that provider. Withollamathe embeddings run locally and nothing leaves your machine. - Should I embed raw code or generated documentation?
- Embed the documentation. Raw code is full of boilerplate and short variable names, while a page describing a file reads like the questions people ask. repowise embeds its wiki pages for that reason.
- When should I use pgvector instead of LanceDB?
- Use pgvector when your deployment already runs PostgreSQL and several workers share one index, because embeddings then live in an existing table and are covered by your existing backups. Use LanceDB for a single-user or SQLite install, where an embedded directory is the simplest option.
- How often do I re-index?
- After each change to the main branch.
repowise updaterefreshes the pages for changed files and re-embeds them, so the index stays in step with the code.