On this page
To prioritize technical debt, score each candidate by what it costs you now (how often the file changes, how many bugs were fixed in it, how many files depend on it) against what it costs to fix (size, test coverage, blast radius), then work the top of that ranking. Run repowise health to get that list from your repository's own history, or build it by hand with the four steps below.
Most teams do not have a debt problem, they have a sequencing problem: there is always more code that could be better than time to improve it. Ranking by impact per effort keeps attention on the code that actually slows delivery.
What is technical debt prioritization?
Technical debt prioritization is ordering cleanup work by the value it unlocks divided by the effort it takes. The output is a short queue, not a backlog of everything that looks untidy.
Martin Fowler's technical debt quadrant sorts debt by whether it was deliberate and whether it was prudent. That tells you where debt came from. Prioritization asks a different question: which of it is costing you today.
A file can be ugly and harmless if nobody touches it, and tidy-looking while sitting on the critical path of every release. People estimate both badly. We over-weight the code we just read and under-weight the code we never open, so a signal that scores every file the same way corrects the bias.
The four signals that rank debt
Four signals do most of the work: change frequency, bug history, reach and coverage. Each is measurable from the repository without asking anyone.
| Signal | What it tells you | Where it comes from |
|---|---|---|
| Churn | How often the file changes, so how often its problems are paid for | Git history, last 90 days |
| Bug-fix history | Files where fixes keep landing | Commit messages and diffs |
| Reach | How many files import it, so how far a mistake travels | Dependency graph |
| Coverage | Whether a change is protected by tests | LCOV, Cobertura, Clover, JaCoCo, Go coverprofile |
Scroll the table sideways to see every column.
Complexity and size sit on top of these: a 4,000-line function in a rarely touched file is a lower priority than a 300-line function that changes weekly and is imported everywhere.
Step 1: Rank files by risk, not by ugliness
Start from where bugs are likely to land. repowise health prints the Fix first list, one ranked queue of refactoring plans, performance fixes and code-shape findings.
uv tool install repowise      # or pipx / pip install repowise
repowise init                 # indexes the repo, scores every file; no LLM key needed
repowise health               # Fix first, KPIs, lowest-scoring files
Fix first (3 of 41 eligible items, 12 due)
 1. Extract the retry branch from parse_config  now, effort M, +1.4 health
    src/config/loader.py:212
    CCN 47 and nesting 6 in a file changed 19 times this quarter.
    verify: pytest tests/unit/test_loader.py

Code health: 7.4/10 [Good], Hotspot: 6.1/10, Worst: 2.3/10 (src/config/loader.py)
Each item names the change, the file and line, why it ranks, the expected gain, the effort bucket (S, M, L, XL) and the command that checks it. Items rank by how far the code sits past size and complexity bars, then by how widely the file is imported, and the tier says whether to start now, plan it, or defer it. See the code health layer docs for the full rules.
Does the ranking point at real risk? Across n = 2,826 · 21 repositories, 9 languages, 2,826 files · 2026-08, repowise's code health score reached 0.74 ROC AUC predicting which files get bug-fixed over the next six months, and it beat ranking by recent churn by +0.10 AUC (benchmark methodology).
Step 2: Turn the top items into concrete plans
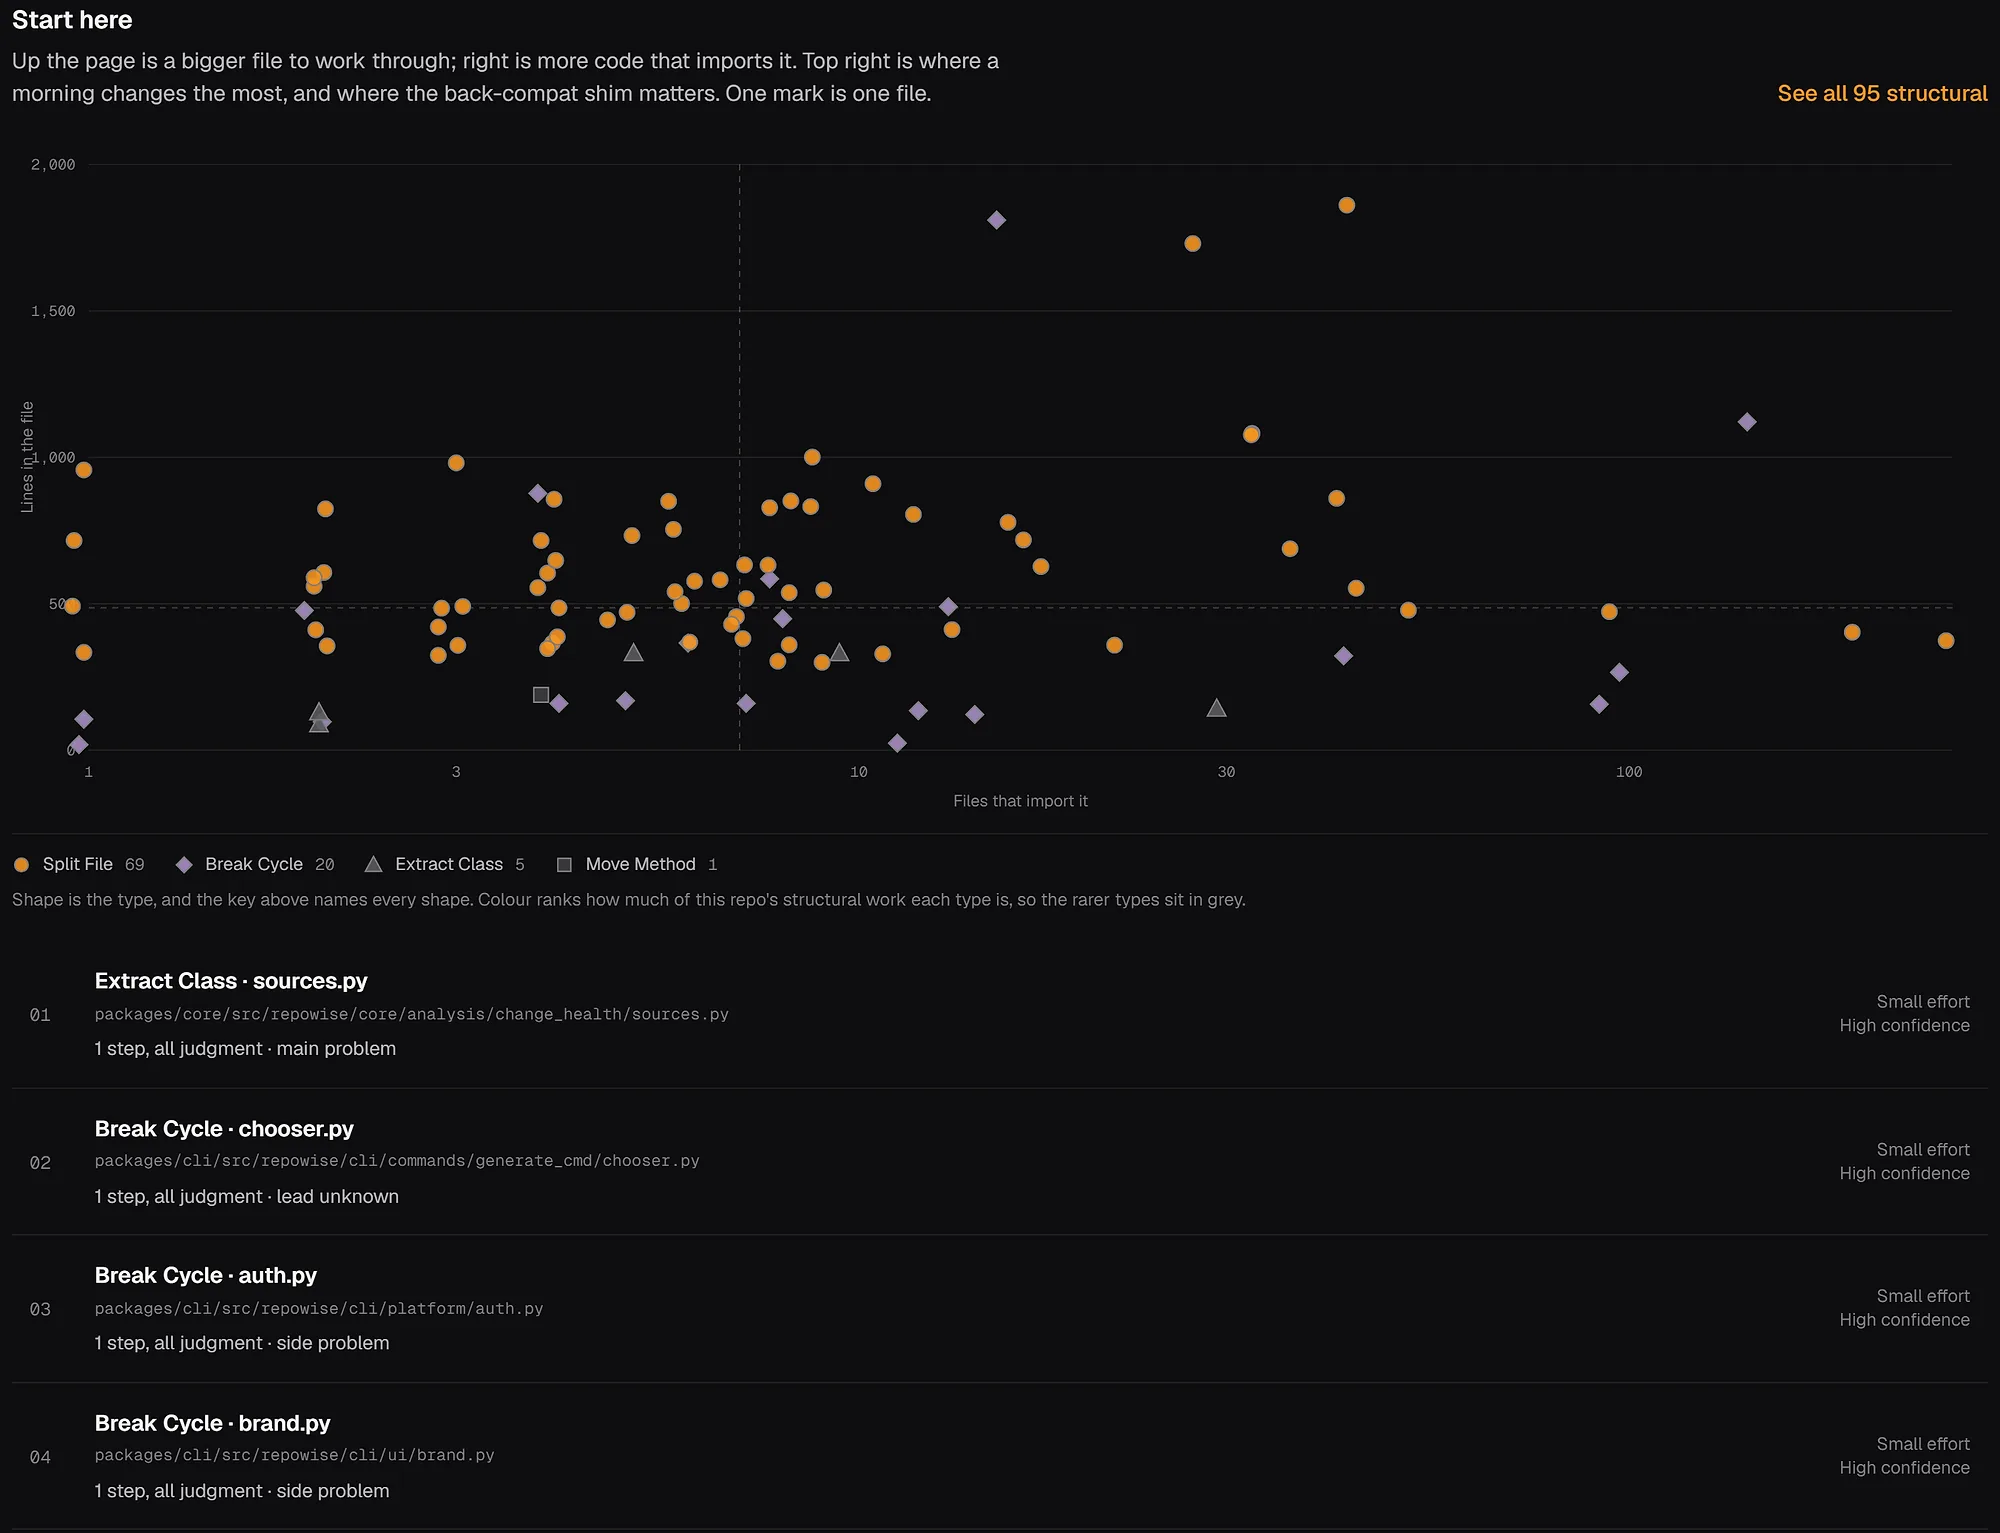
A ranked file is not yet a task. A refactoring plan is. Each plan is a typed change computed from the graph and git history:
| Plan | What it names |
|---|---|
| Extract Method | A line span to lift out, with the helper's parameters and return value |
| Extract Helper | Every copy of a duplicated block and where the shared helper belongs |
| Extract Class | The cohesive groups a god class splits into |
| Move Method | A method that uses another class more than its own, and where it belongs |
| Split File | Which symbols go to which new file, and the import edits in dependents |
| Break Cycle | The smallest set of import edges to invert (advisory) |
| Performance Fix | One shared change for an N+1 or I/O-in-loop problem |
Scroll the table sideways to see every column.
repowise health --refactoring-targets            # the stored queue
repowise health --refactoring-targets --format json
repowise health --plan <plan-id>                 # one plan as a prompt an agent can apply
Plans carry a confidence and an effort bucket, so you can pick the high-confidence, small-effort ones for a Friday cleanup and schedule the rest. repowise ranks and explains; it does not edit your code unless you ask for generated code on one plan.
Step 3: Read coverage as a risk multiplier
Coverage tells you how safe a change is, not whether the code is good. One repo-wide percentage hides a well-tested utility layer next to a dark payments module. Cross coverage with churn and reach instead.
pytest --cov --cov-report=lcov:coverage.lcov
repowise coverage add coverage.lcov
repowise health          # untested hotspots now surface
The untested_hotspot finding fires when a file is a hotspot (8 or more commits in 90 days), has at least four dependents and sits under 40% line coverage. Those go first, because the cheapest way to make a risky refactor safe is a characterization test. When no test reaches a plan's code, the plan says so and asks for one before the edit. Without a report, repowise still infers which tests reach a file from the call graph. More in untested hotspots.
Step 4: Delete before you refactor
The cheapest debt to remove is code nobody runs. Check for dead code first, because refactoring a function you could delete is wasted effort. Fix first already leaves out code covered by a sure dead-code finding for that reason.
repowise dead-code --safe-only
Findings carry a confidence tier, so you batch the high-confidence deletions and review the rest. The full workflow is in how to find dead code in your repository.
Do not forget performance debt
Performance debt is structural: a query inside a loop, a blocking call in async code, a string rebuilt every iteration. repowise detects these shapes statically, follows the call graph up to three hops to attach the path from caller to sink, and reports them as a separate signal, never blended into the defect score. It is high precision and low recall and measures no latency, so confirm anything on a hot path with your profiler. Details are in the performance layer docs.
Keep the list short and current
- Cap the queue. Work the top three to five items per sprint and ignore the rest until they move.
- Re-rank after merges.
repowise updatere-scores only the files that changed, so the list stays fresh. - Make it a team list.
repowise nextmerges Fix first with fragile files, dead-code batches and stale coverage into one Do next list. - Let agents help. The
get_healthMCP tool, one of repowise's ten tools, returns the same ranked items, so a coding agent can pick up item one with its verify command.
Related reading: refactoring priorities by impact per effort, best refactoring tools and the code health feature.
FAQ
- How do you prioritize technical debt?
- Score each item by its impact (change frequency, bug fixes, number of dependents) against its effort (size, test coverage, blast radius) and work the highest ratio first. Do not rank by how messy the code looks, since untouched messy code costs little.
- What is the best metric for ranking technical debt?
- No single metric works alone. Churn combined with bug-fix history and reach is the strongest starting point, then adjust for effort. repowise's code health score combines these and reached 0.74 ROC AUC across n = 2,826 · 21 repositories, 9 languages, 2,826 files · 2026-08.
- Should I fix untested code before refactoring it?
- Yes, when the file is a hotspot. Add a characterization test first so the refactor has a safety net. repowise flags these as untested hotspots and tells you when a plan needs a test before the edit.
- Does repowise refactor my code automatically?
- No. It ranks targets and produces structured plans with the first edit and the tests to run. Generated code is off by default and only runs when you ask for it on a specific plan.
- Is the ranking reproducible?
- Yes. The scoring is deterministic and built from 59 markers, so the same commit gives the same ranks and plan ids. No model call is needed to produce the list.
- Which coverage formats does repowise read?
- LCOV, Cobertura, Clover, JaCoCo, Go coverprofile and repowise JSON. Add a report with
repowise coverage add <file>. - How often should I re-prioritize?
- After meaningful merges and at sprint planning.
repowise updatere-scores only changed files, so re-ranking is cheap enough to do routinely.