

On this page
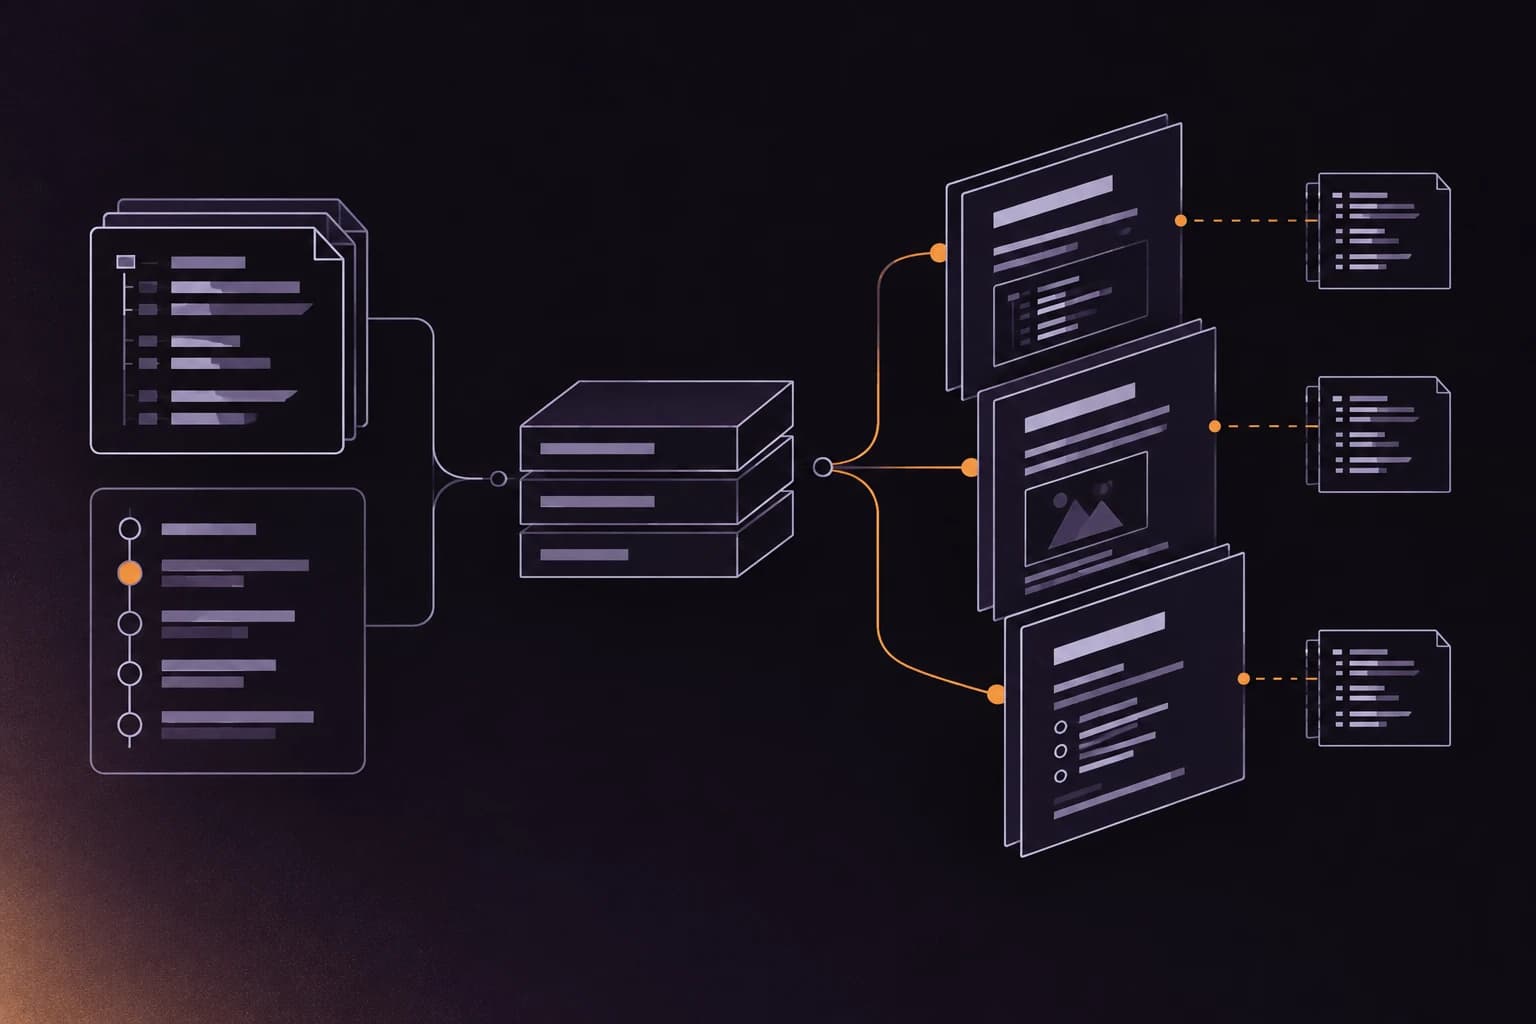
To generate documentation from a codebase with AI, parse the code into a dependency graph first, add git history for ownership and churn, then render pages from that structure and let a model write prose only where explanation matters. Regenerate only the pages whose inputs changed, on every merge. A model that sees one file's text can summarize it. A model that is handed the graph and the history can say why the file matters.
Part of the Auto Wiki guide.
Which approach fits
Five kinds of tool produce documentation from code. They differ in what they read and in how they stay current (as of October 2026).
| Approach | What you get | Stays current | Examples |
|---|---|---|---|
| API reference generators | Reference from signatures and doc comments | On every build | Sphinx autodoc, TypeDoc, rustdoc, Javadoc |
| Inline AI docstrings | Comments written into source, one function at a time | When someone reruns it | Editor assistants |
| Hosted repo wikis | Model-written pages and chat for a repository | Refreshed by the vendor | DeepWiki (free for public GitHub repositories; private repositories need the Devin app) |
| Docs coupled to code lines | Walkthroughs that flag themselves when the code moves | On change, with human curation | Swimm |
| Index-first wiki | Pages built from a parsed graph plus git history, optional model prose, served over MCP | Incremental update on every merge | repowise |
Scroll the table sideways to see every column.
For a tool-by-tool comparison, see codebase documentation tools compared and repowise vs DeepWiki.
The eight steps, in order
These apply whichever tool you use.
- Parse every file into a syntax tree. List functions, classes and imports. This is cheap and needs no model.
- Build the dependency graph. Resolve imports into edges. Files that many others import are the ones whose docs matter most.
- Mine git history. Record who changes each file, how often, and which files change together. Teams rarely write this down.
- Render the structural pages. File lists, dependencies and owners come straight from steps 1 to 3.
- Write the explanatory pages. What a subsystem is for and how data flows come from a model that receives the structure as input, not raw text.
- Draw diagrams from the graph. Rendered from edges, they cannot drift from the code.
- Track freshness. Store a hash of what each page was built from, and refresh only pages whose hash changed.
- Serve it. A browsable site for people, and an MCP server (Model Context Protocol, the standard way coding agents call external tools) so agents read the same pages.
Why hand-written docs drift
Stale documentation is worse than none, because people trust it. A page is accurate the day it is written and wrong the day after a refactor merges. Nobody owns the upkeep, and the context readers most need (why a decision was made, which files are brittle, who to ask) is the context that never gets written.
Generation fixes the first two problems by deriving the reference from the code. Git history fixes the third, because ownership and co-change are recorded in commits whether anyone documents them or not.
Why the input matters more than the model
Prompting a model with raw source produces a restatement of the code. Prompting it with structure produces an explanation. repowise prompts model-written pages with assembled material: parsed structure and signatures, what the subject imports and what imports it, ownership and churn, the significant commits from its history (merges, dependency bumps and lint-only commits filtered out), and the pages it should link to.
That is the difference between "this is a login function" and "this is the authentication entry point, two modules depend on it, and it changed nine times this quarter."
Generate docs with repowise
repowise is open source (AGPL-3.0) and runs locally or in CI. It builds the wiki as part of indexing. The architecture page shows how the parser and the page generator fit together.
pip install repowise
cd /path/to/your/repo
repowise init
init parses the repository, builds the graph, mines git history and writes the wiki. It parses 28 languages to a full syntax tree. In a terminal it asks which model provider to use; exclude paths with -x, for example -x vendor/ -x 'src/generated/**'.
No API key needed
repowise init --no-prose
--no-prose is free and guaranteed to spend nothing. Almost the whole wiki is rendered from structure, so a keyless index is a complete wiki, not a placeholder. File pages, symbol pages, dependency cycles, infrastructure files, hotspots, ownership, dead code and decision archaeology are identical with or without a key. A key adds model-written prose to three page types: subsystem pages, the repository overview and the onboarding pages.
What gets generated
| Page type | One per | Written by |
|---|---|---|
| File page | eligible source file | structure |
| Symbol spotlight | selected public symbol | structure |
| API contract | file classified as an API surface | structure |
| Dependency cycle | strongly connected component | structure |
| Infrastructure page | Dockerfile, CI or IaC file | structure |
| Subsystem (module) page | subsystem in the concept tree | model, structure when keyless |
| Repository overview | repository | model, structure when keyless |
| Onboarding | Getting Started, Key Concepts, How It Works, Active Landscape, Glossary | model, structure when keyless |
Scroll the table sideways to see every column.
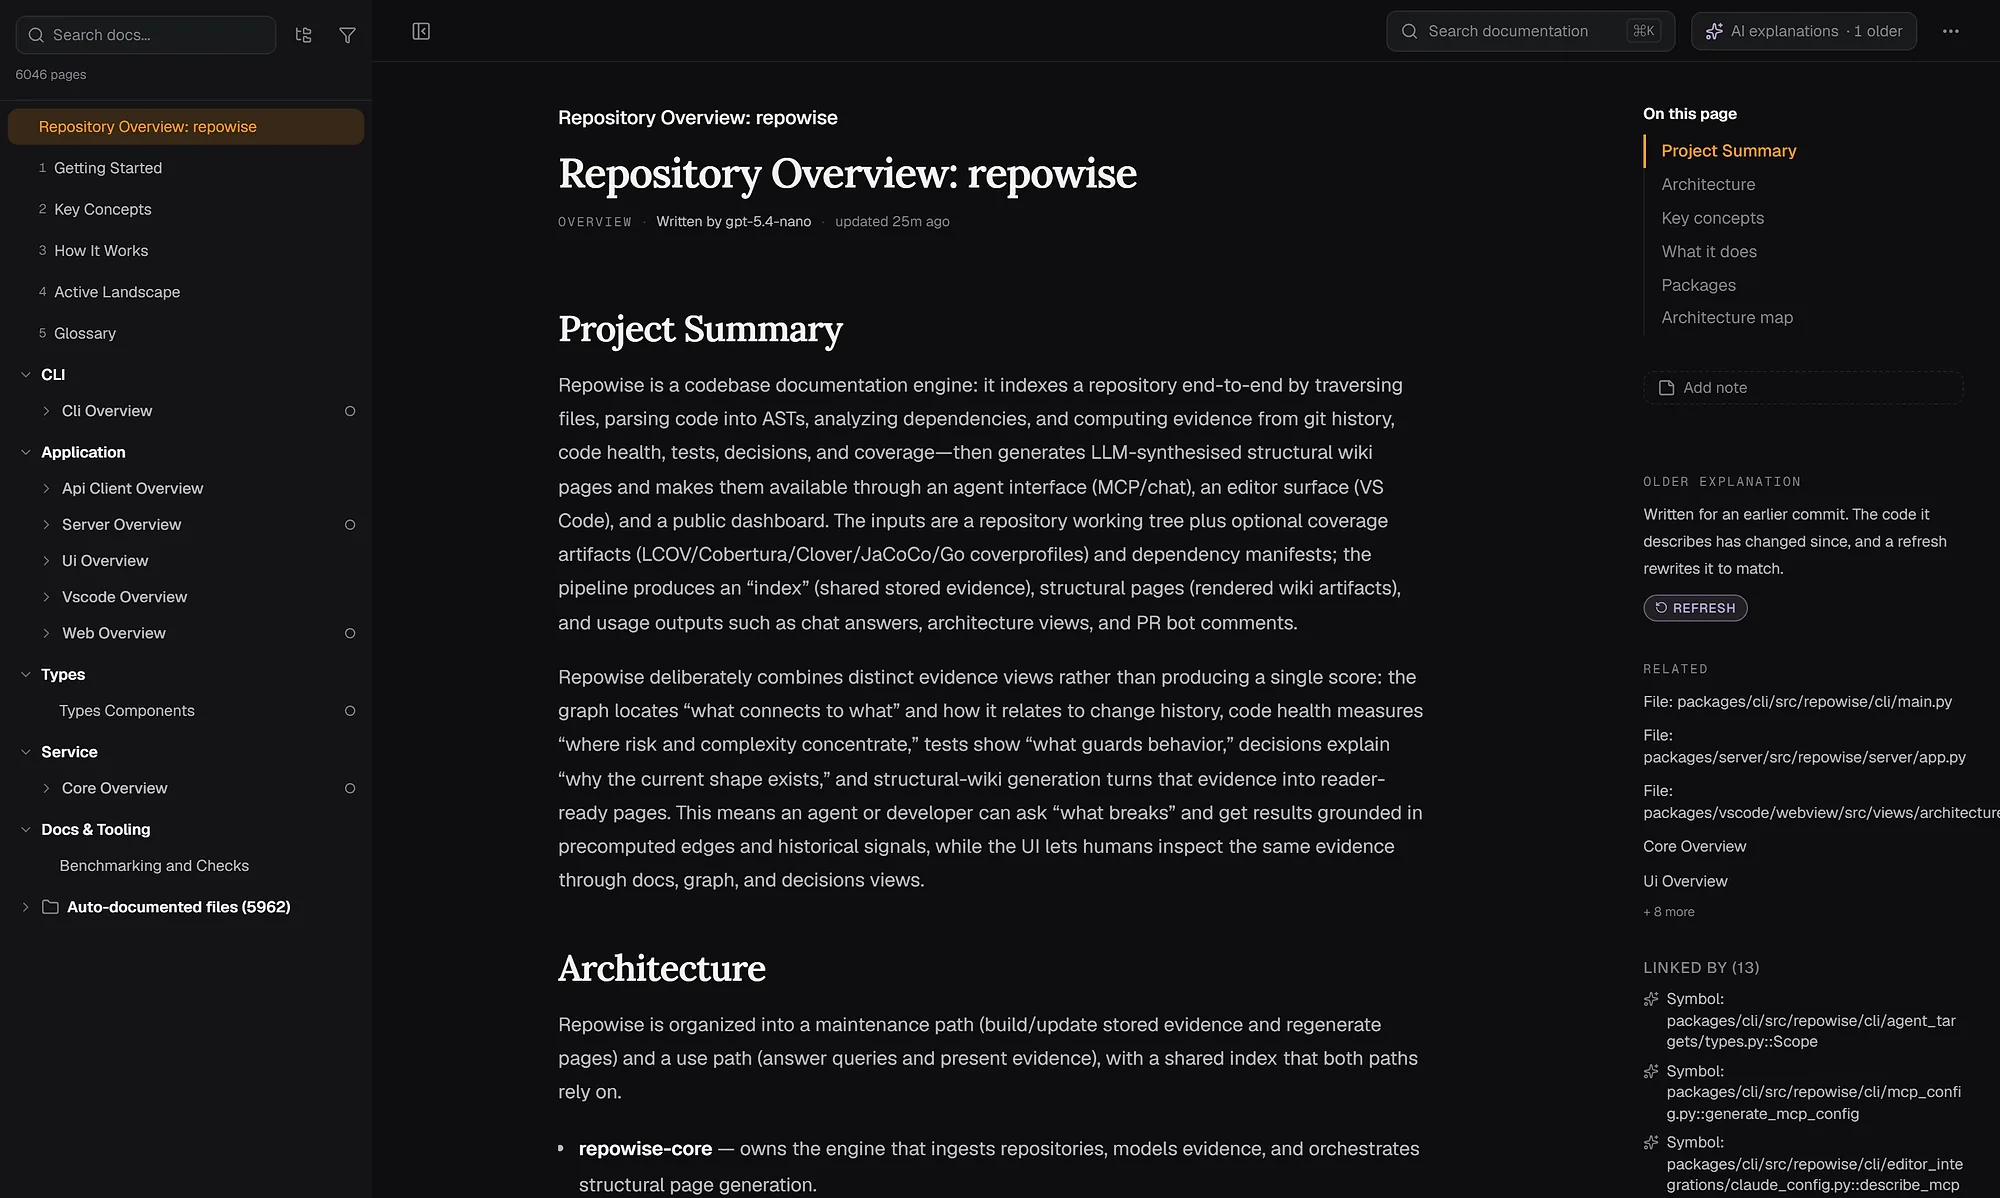
The repository overview carries a system map drawn from the graph: structure picks the boxes and arrows, and a configured model only names them.
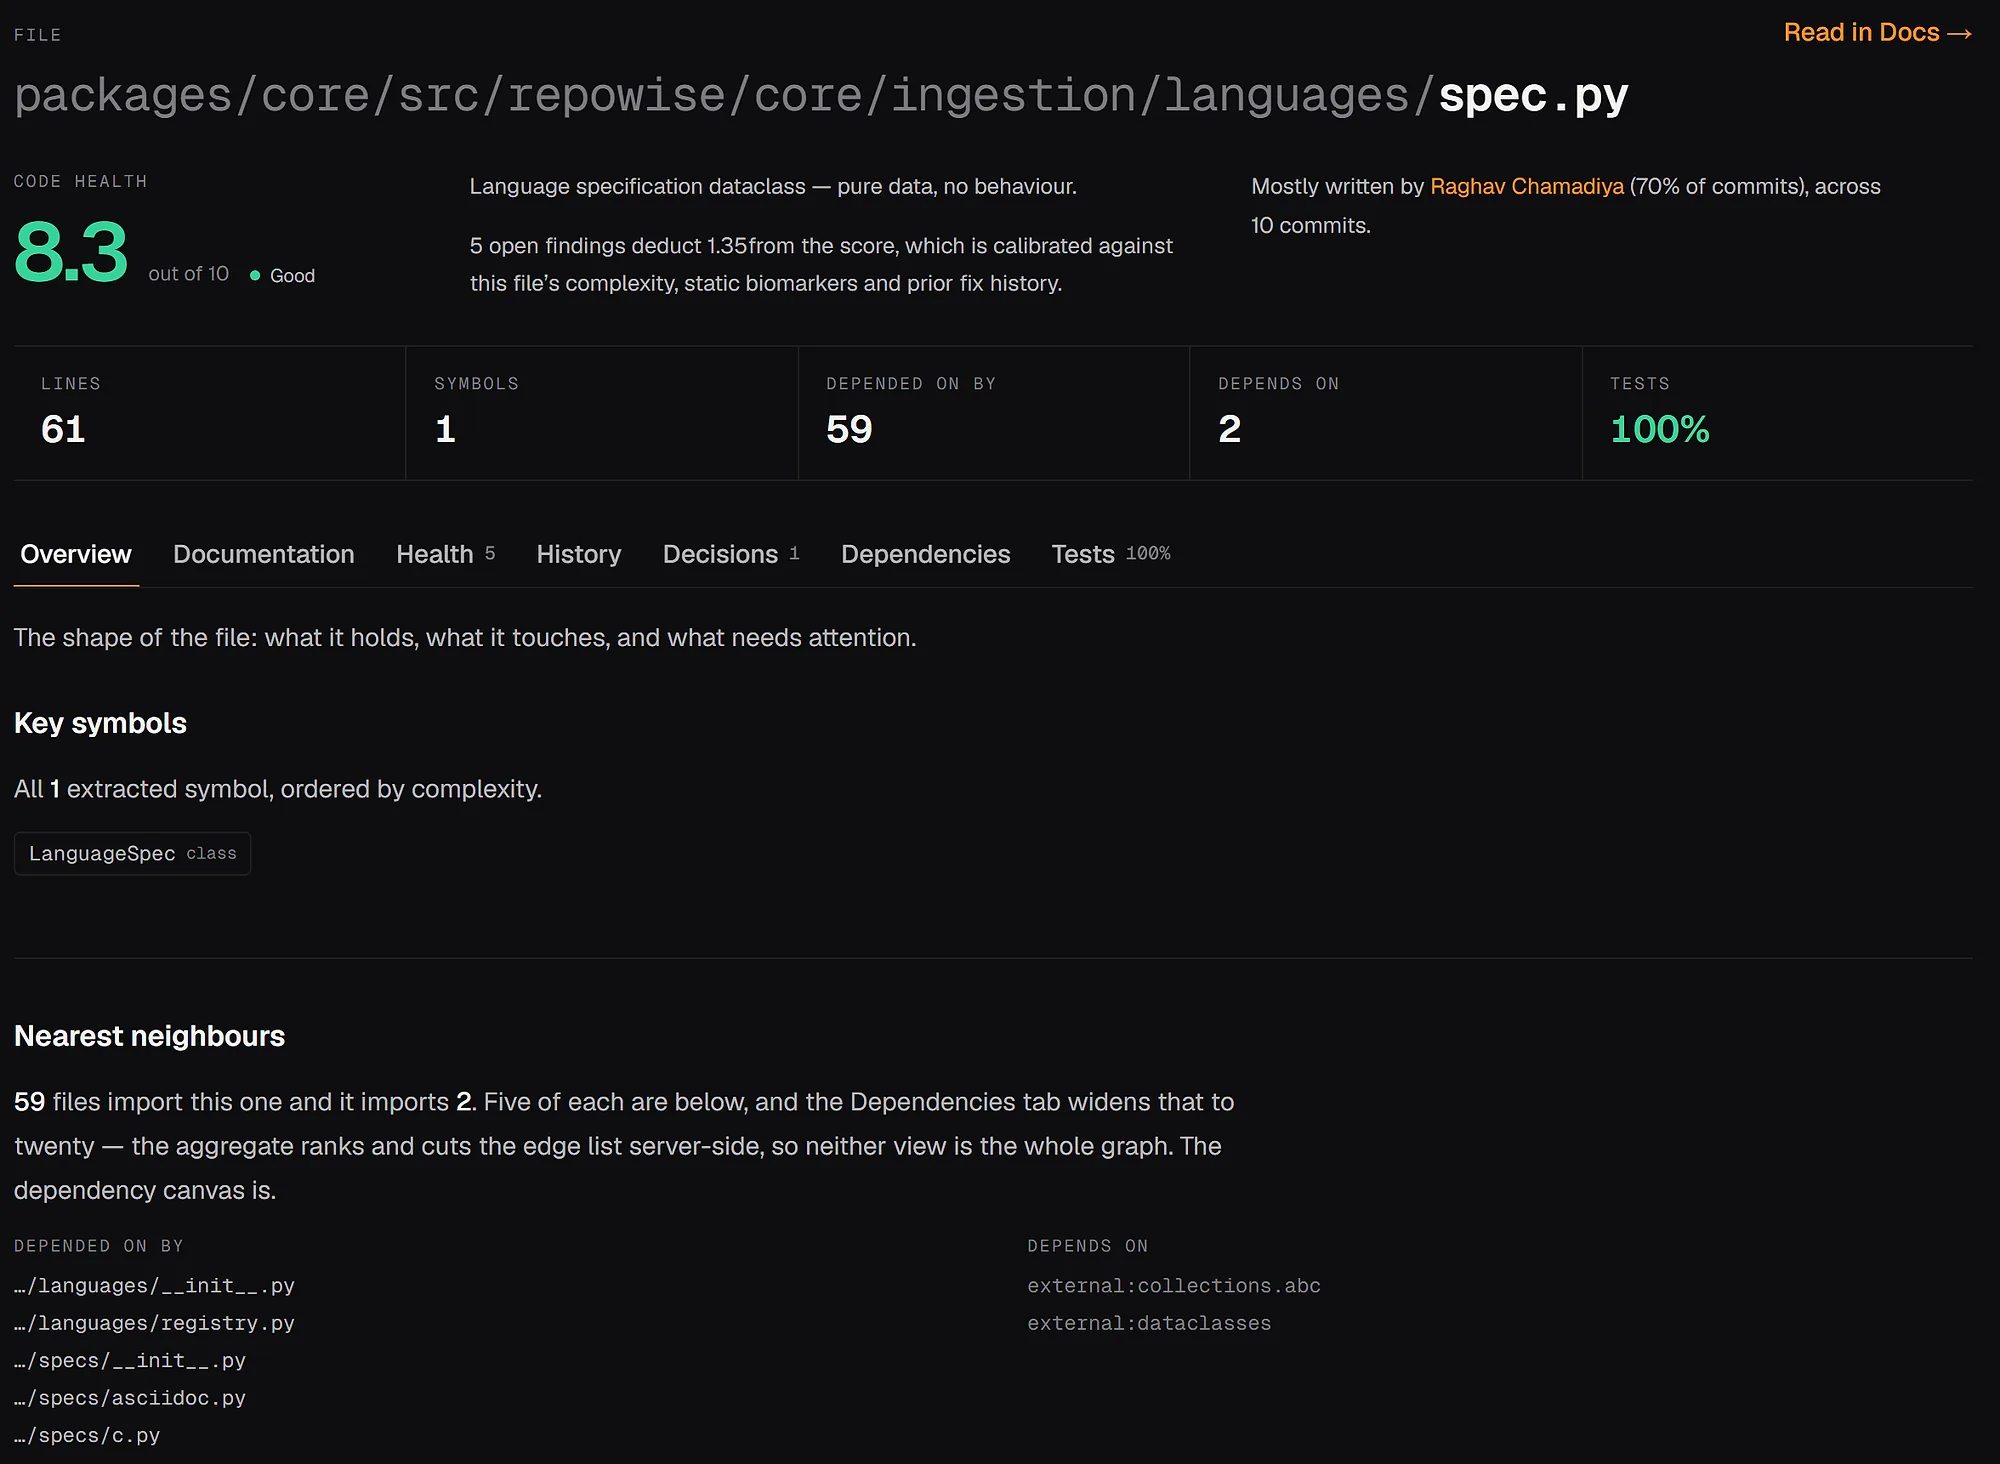
Each file page puts the dependency edges, ownership, code health and tests next to the description.
You can browse generated output on real repositories in explore, including the FastAPI docs and its ownership map, before installing anything.
Choose a voice
A style changes the prose without changing headings, so search and links keep working.
| Style | Best for |
|---|---|
comprehensive (default) | Humans and AI, full narrative |
reference | Library consumers, signature-dense |
tutorial | New contributors, guided |
caveman | Agents and token budgets, about 70% smaller |
Scroll the table sideways to see every column.
repowise init --wiki-style reference
repowise restyle tutorial      # re-render every page in a new voice
Custom styles live in .repowise/styles/<name>/style.yaml. language in .repowise/config.yaml (or init --language <code>) sets the natural language of the wiki; code, paths and symbol names are never translated.
Keep it fresh on every merge
repowise update re-renders only what your commits touched. It finds the files changed since the last sync, walks the dependency graph for the pages those changes affect, and rebuilds that handful, typically a few per commit.
repowise update                 # incremental, fast enough for every merge to main
repowise generate --stale       # rewrite pages whose code changed since they were written
repowise generate               # fill in subsystem prose you skipped at init
Two checks decide what is stale. A model-written page compares a hash of its rendered prompt with the stored one: same prompt and same model means the prior page is reused, with no tokens spent. A structure-rendered page folds the subject's hash together with a fingerprint of the renderer, so a template improvement triggers exactly one regeneration. Every page carries a status of fresh, stale, expired or unknown, which gives you a list to act on instead of a feeling that the docs are old. For wiring this into CI, see keeping documentation fresh.
Serve it to people and agents
repowise serve opens the wiki locally, and repowise export --format markdown writes it out as files. The same pages power the ten MCP tools, so Claude Code, Cursor, Codex and other agents query architecture, file pages and dependencies directly instead of reading files one at a time. See how to generate a CLAUDE.md for the agent-facing side.
What to generate and what to write
AI replaces the reference layer, not the reasoning layer.
| Documentation | Best source | Why |
|---|---|---|
| API reference | Generated | Follows the source exactly and is tedious to maintain |
| Module summaries | Generated | Covers the code nobody wants to document |
| Ownership and risk maps | Generated | Needs thousands of commits read |
| Architecture decision records | Human, with decision mining | A model sees what was done, not always the business reason |
| Onboarding narrative | Both | Generated steps, human gotchas |
Scroll the table sideways to see every column.
Pitfalls
- Generating from raw file text. The output restates the code and misses how files relate. Check that your tool builds a graph first.
- Regenerating everything on a schedule. It wastes tokens and churns diffs. Rebuild by hash, on merge.
- Treating prose as extraction. A structure-rendered page is extracted and reports confidence 1.0; a model-written page is a grounded summary and reports 0.8. Read them accordingly.
- Leaving refresh as a manual step. If it is not automated, it will be skipped within a month.
FAQ
- How do I generate documentation from my codebase?
- Parse the code into a dependency graph, add git history, then generate pages from that structure, with or without a model writing prose. With repowise that is
pip install repowiseandrepowise initin the repository, orrepowise init --no-prosewith no API key. Then runrepowise updateon every merge. - Can AI generate documentation from code for free?
- Yes. Sphinx, TypeDoc and rustdoc are free and local. DeepWiki is free for public GitHub repositories. repowise's
--no-prosemode builds a complete structural wiki with no model call, and the hosted Free plan covers two public repositories. - Is my code sent to an LLM provider?
- Only if you configure one. With
--no-prose, or a local model through Ollama, nothing leaves your machine. With a hosted provider such as Anthropic or OpenAI, the assembled context for each model-written page is sent to that provider's API under its data terms. - How does it handle large repositories?
- Parsing and graph building are cheap. Model cost is limited to three page types, and updates rebuild only changed pages.
max_file_pagescan cap file pages, highest importance first, for very large repositories. - How do I keep generated docs up to date?
- Run
repowise updatein CI or on push tomain. Each page stores a hash of its inputs, so changed code marks exactly the affected pages stale and only those are rewritten. - Can coding agents use the generated docs?
- Yes. repowise serves the wiki over ten MCP tools, so agents get architecture, file pages and dependency context in one call instead of scanning files.