On this page
A code hotspot is a file that changes far more often than the rest of the repository; the risky ones are also complex, bug-prone or owned by one person. To find them, count each file's recent commits with one git command (git log --since="90 days ago" --name-only --pretty=format: | sort | uniq -c | sort -rn | head -20), then check the top of the list for complexity, past bug fixes and owners. repowise init does all of it from your git history with no LLM: it flags files in the top quartile of recency-weighted churn that clear activity floors, and ranks them beside bug fixes, complexity and bus factor.
Part of the git intelligence guide.
What is a code hotspot?
A code hotspot is a file that changes frequently and is costly or risky to change. Most development activity lands in a small part of any codebase, and that part is where bugs, merge conflicts and slow reviews cluster. Adam Tornhill popularised the method in Your Code as a Crime Scene, and CodeScene's hotspot documentation gives a typical result: prioritized hotspots were 1.2% of the codebase, took 12.5% of development effort, and held 45% of the bugs found and fixed.
Two kinds of file look similar and are not hotspots. A complex file nobody touches is stable debt: ugly, but quiet. A simple file that changes daily is active development. The hotspot is the intersection, a file that is both hard to read and constantly edited.
Step 1: Rank files by churn with one git command
The fastest hotspot list is a count of commits per file over the last 90 days. It needs nothing installed.
git log --since="90 days ago" --name-only --pretty=format: \
  | grep . | sort | uniq -c | sort -rn | head -20
The output is a commit count next to each path:
  71 src/cli/update/command.py
  55 src/server/tool_answer.py
  55 src/ingestion/call_resolver.py
  12 src/config/settings.py
Ninety days is long enough to smooth over one busy sprint and short enough to ignore files that were reworked and settled last year. Exclude lockfiles, generated code and changelogs, which churn without carrying risk.
Step 2: Add complexity, bug fixes and people
Churn tells you where the work is. Bug-fix history tells you where it breaks. Rank the same files by commits whose subject mentions a fix:
git log --since="180 days ago" -i --grep="fix" --name-only --pretty=format: \
  | grep . | sort | uniq -c | sort -rn | head -20
A file near the top of both lists is a stronger candidate than one near the top of either. For complexity, a per-function tool such as lizard (pip install lizard, then lizard -w src/) lists functions over a cyclomatic complexity threshold. Intersect that list with your churn and fix lists. For packaged options, see the code hotspot analysis tools compared.
The third signal is people. In a 2008 Microsoft Research study of Windows Vista, Nagappan, Murphy and Basili found organizational metrics (how many engineers touch a component, how ownership is spread) were significantly better predictors of failure-proneness than code churn, complexity and dependencies. A hotspot with one person who understands it and no backup is a different problem from one with six active owners.
| Signal | What it answers | Where it comes from |
|---|---|---|
| Churn (commits in 90 days) | Where is the work happening? | git log |
| Bug-fix count | Where does it break? | Commit subjects plus the diff |
| Complexity | How hard is it to change safely? | AST metrics per function |
| Bus factor and owner | Who can review and fix it? | Commit authorship |
| Co-change partners | What else moves with it? | Files in the same commits |
Scroll the table sideways to see every column.
Doing this by hand works for one repository and one afternoon. It does not stay current, and it does not join the signals for you.
Step 3: Get a ranked hotspot list with repowise
repowise init indexes your repository, walks its full git history, and produces a hotspot ranking with bug-fix counts, bus factor and owner beside each file. It runs locally. The git analysis and the hotspot list need no LLM key and make no network calls.
uv tool install repowise      # or pipx / pip install repowise
repowise init                 # indexes code and git history
repowise serve                # opens the dashboard; open Hotspots
The Hotspots page ranks files by change frequency and prior bug fixes. Each row shows commits in the last 90 days, bug-fix count and age of the last fix, churn percentile, trend, bus factor, lines changed and the primary owner. Filters narrow the list to Hot, Bus factor risk, Accelerating or Bug magnet files.
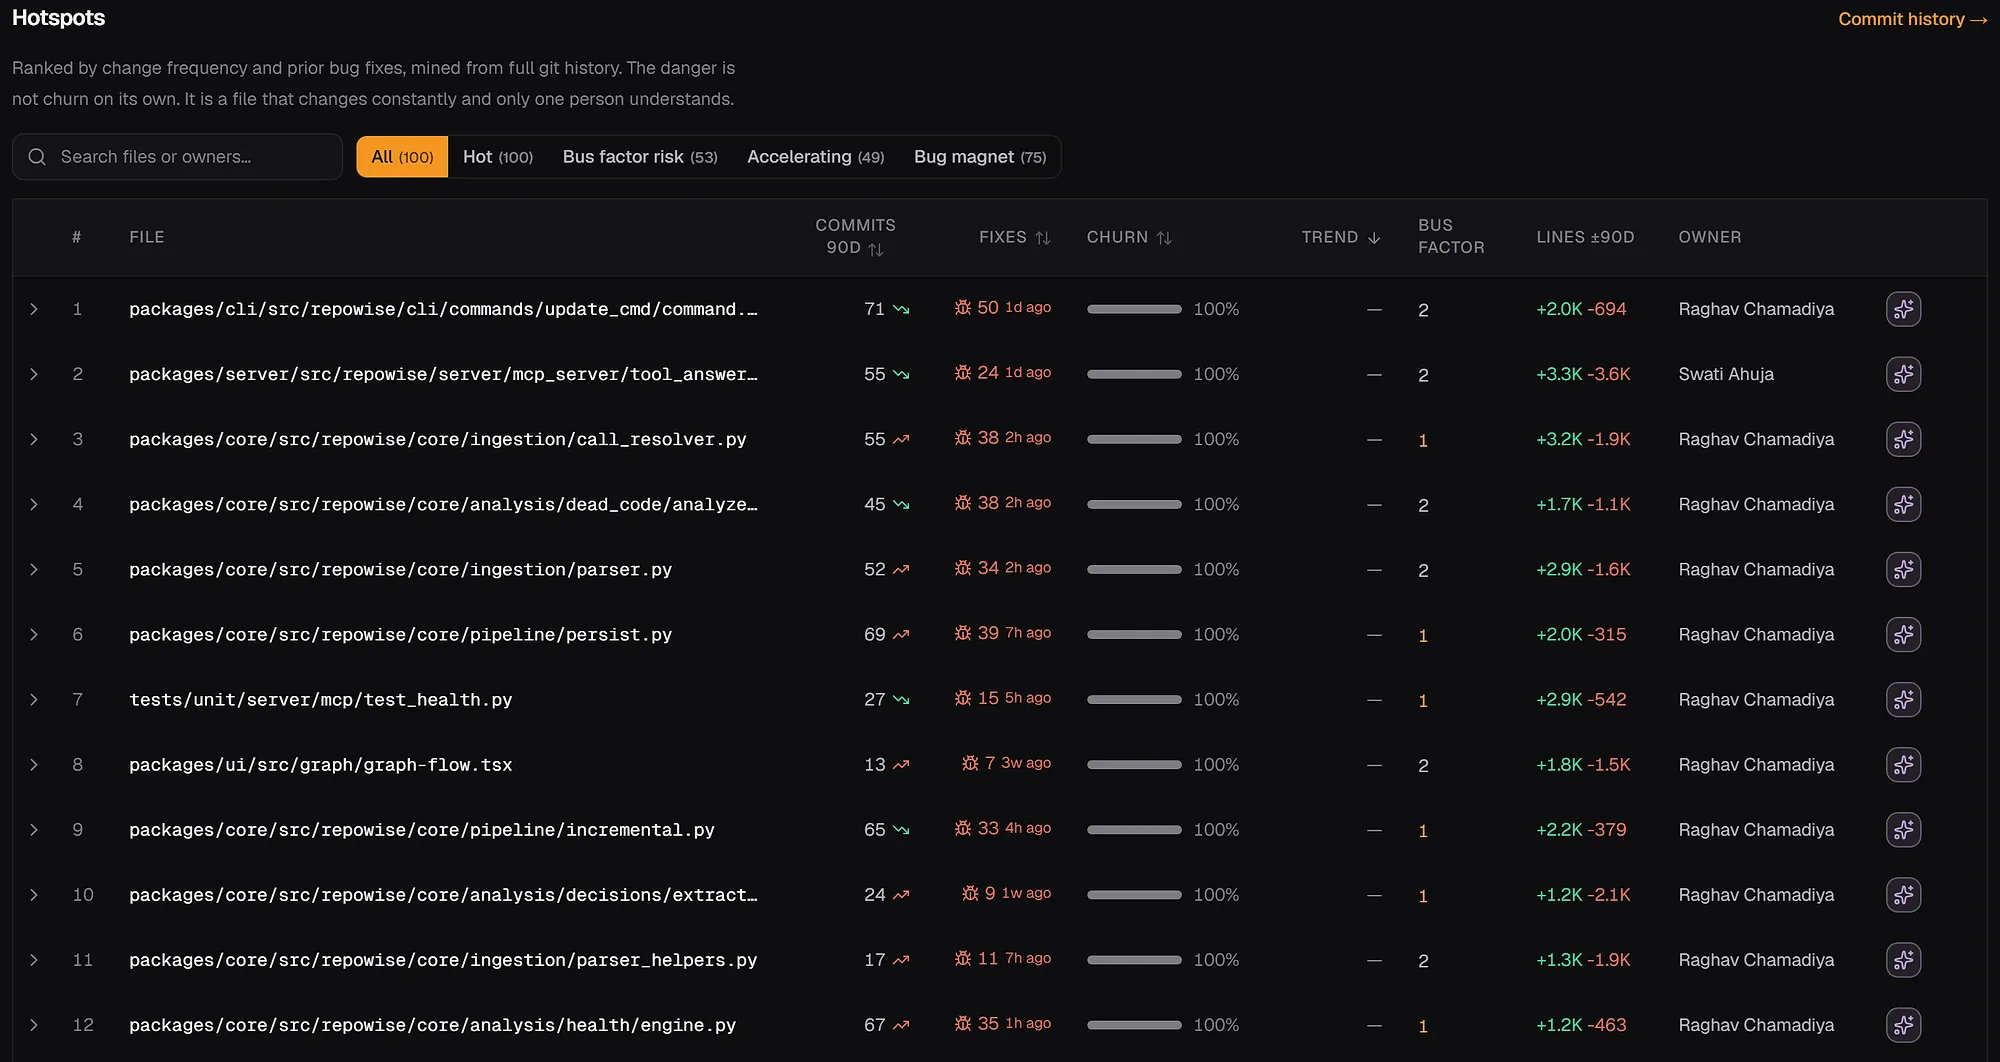
Two definitions explain the flags. A file is a hotspot when its recency-weighted churn sits in the top quartile of the repository and it clears two activity floors: at least 3 commits in the last 90 days, plus either 8 or more commits or a decayed churn score of at least 0.5. Churn is weighted by age with a 180-day half-life, so last week's commit counts more than last year's. A file is a bug magnet when its decayed bug-fix count over 180 days reaches 3.0. Merge commits, docs-only fixes, test-only fixes and comment edits are not counted as fixes. Details are in the bug-fix history and ownership docs.
Complexity enters through the code health layer, which scores each file from 1 to 10 with deterministic detectors and reports a separate hotspot health figure for hotspot files only. That makes "how healthy is the code we change most" a single number you can track.
You can browse the same views on a public repository without installing anything: the FastAPI hotspots page and its ownership map.
Step 4: Check one file before you change it
repowise risk --target <file> prints what history says about a single file: hotspot score, bug-fix record, owners and co-change partners. Run it before a risky edit or while reviewing a pull request.
repowise risk --target src/pipeline/persist.py
Agents get the same answer through the get_risk MCP tool, one of ten tools:
get_risk(targets=["src/pipeline/persist.py"])
# hotspot_score (0 to 1), defect_profile {fix_count, last_fix_days_ago, bug_magnet},
# co_change_partners, primary_owner, dependents_count, test gaps
When an agent is about to edit a file with a recent run of fixes, the pre-edit hook adds a line to its context:
[repowise] pipeline/persist.py has been bug-fixed 5x in the last 6 months,
last 2 weeks ago (bug magnet); mostly in run_pipeline.
Co-change partners are the files that changed in the same commits at least three times, with or without an import between them. If get_risk lists a partner your diff does not include, that is the file most likely to be missed. See hidden coupling and co-change detection.
For a whole change rather than a file, repowise risk main..HEAD ranks the diff against the repository's own recent commits and reports whether the files it touches have broken before.
What to do with the list
Spend effort on the top of the list, in this order. The goal is to lower the cost of changing the files you change most.
- Add tests before refactoring. A hotspot with no coverage is the highest-regret place to edit. See untested hotspots and coverage priority.
- Split files that grow for no reason. A file that collects every feature change is usually several responsibilities. Splitting does not remove complexity, but it spreads churn so each file changes for one reason.
- Give hotspots an owner. A hotspot with a bus factor of one needs a second person who reviews its changes. See code ownership and bus factor.
- Make the case with data. "This file changed 71 times in 90 days and was fixed 50 times" gets a refactoring slot in planning more reliably than "this code is messy".
- Surface it in review. The repowise bot flags pull requests that touch hotspots and bug magnets, so the reviewer sees the history while reading the diff.
Pitfalls
- High churn is not always a problem. A file in the middle of a new feature should be busy. Read the trend and the fix count, not churn alone.
- Big refactors and renames inflate counts. Mechanical commits (formatting, moves) add churn without adding risk. Rename tracking and ignore lists help.
- Squash merges hide history. If your team squashes every pull request into one commit, per-file commit counts understate how much work a file absorbs. Lines changed gives a second view.
- Shallow clones undercount. CI checkouts often fetch limited history. Run
git fetch --unshallowbefore analysing. - Fix detection is keyword based. Commit subjects that never say "fix" are invisible to the count. A consistent commit style makes the signal stronger.
FAQ
- What is git hotspot analysis?
- Git hotspot analysis ranks the files in a repository by how often they change, usually combined with a measure of how hard they are to change safely. The files that score high on both are where bugs and review effort concentrate. It reads commit history, so it needs no running code.
- How do I find hotspots with git alone?
- Run
git log --since="90 days ago" --name-only --pretty=format: | grep . | sort | uniq -c | sort -rn | head -20. That lists the twenty most frequently changed files in the last 90 days. Cross-check them against a complexity tool and a count of bug-fix commits to separate risky files from merely busy ones. - Is churn alone a good predictor of bugs?
- Not on its own. Churn shows where work happens, which is often just where the product is growing. Bug-fix history, complexity and how many people understand the file are stronger together, and Microsoft Research found organizational metrics outperformed code metrics for predicting failure-prone components in Windows Vista.
- What time window should I use?
- Ninety days is a sound default for churn, and 180 days for bug fixes. Shorter windows chase single sprints, and longer ones keep flagging files that were fixed and stabilised long ago. repowise weights older commits less, with a 180-day half-life, so recent changes count most.
- How does repowise rank hotspots?
- repowise ranks files by recency-weighted change frequency and prior bug fixes, then shows bus factor, owner, trend and lines changed beside each. A file is a hotspot when its churn is in the top quartile of the repository and it clears the activity floors above. Code health scores add complexity, and none of it needs an LLM key.
- Can I run hotspot analysis on a private repository?
- Yes. repowise runs on your machine, and the git analysis never sends code anywhere. The hosted version supports private repositories on the Pro plan, and public repositories are free.