On this page
Codebase context for AI agents is a queryable index of a repository (its structure, dependencies, history, owners and risk) that an agent asks for through tools, one question at a time, instead of receiving files pasted into its prompt. repowise builds that index once and serves it over the Model Context Protocol through ten task-shaped tools. In a real agent loop on django/django, that cut output tokens 31.6% against a bare agent, and the agent reached its answer in 3.8 tool calls.
Part of the AI Context & MCP guide.
What is codebase context for AI agents?
Codebase context is whatever an agent knows about your repository beyond the file it has open. A bare agent builds it the slow way: it greps, opens files, and keeps what it finds in its window. An agent with an index asks instead: "what breaks if I change this?", "where does this request get validated?", "why is this written this way?". Each question returns a short, cited answer.
The window is not the constraint. The constraint is that the facts an agent needs most (who depends on a file, how often it breaks, which decision shaped it) are not in the text of the file at all. They live in the dependency graph and in git history.
One index, ten tools
repowise indexes a repository once: it parses source into AST-backed entities across 28 languages, mines git history for churn and ownership, resolves cross-file dependencies, and writes a wiki on top. repowise init registers the MCP server with Claude Code, and repowise init --codex writes project-local Codex config. Any other MCP client can start the server with repowise mcp.
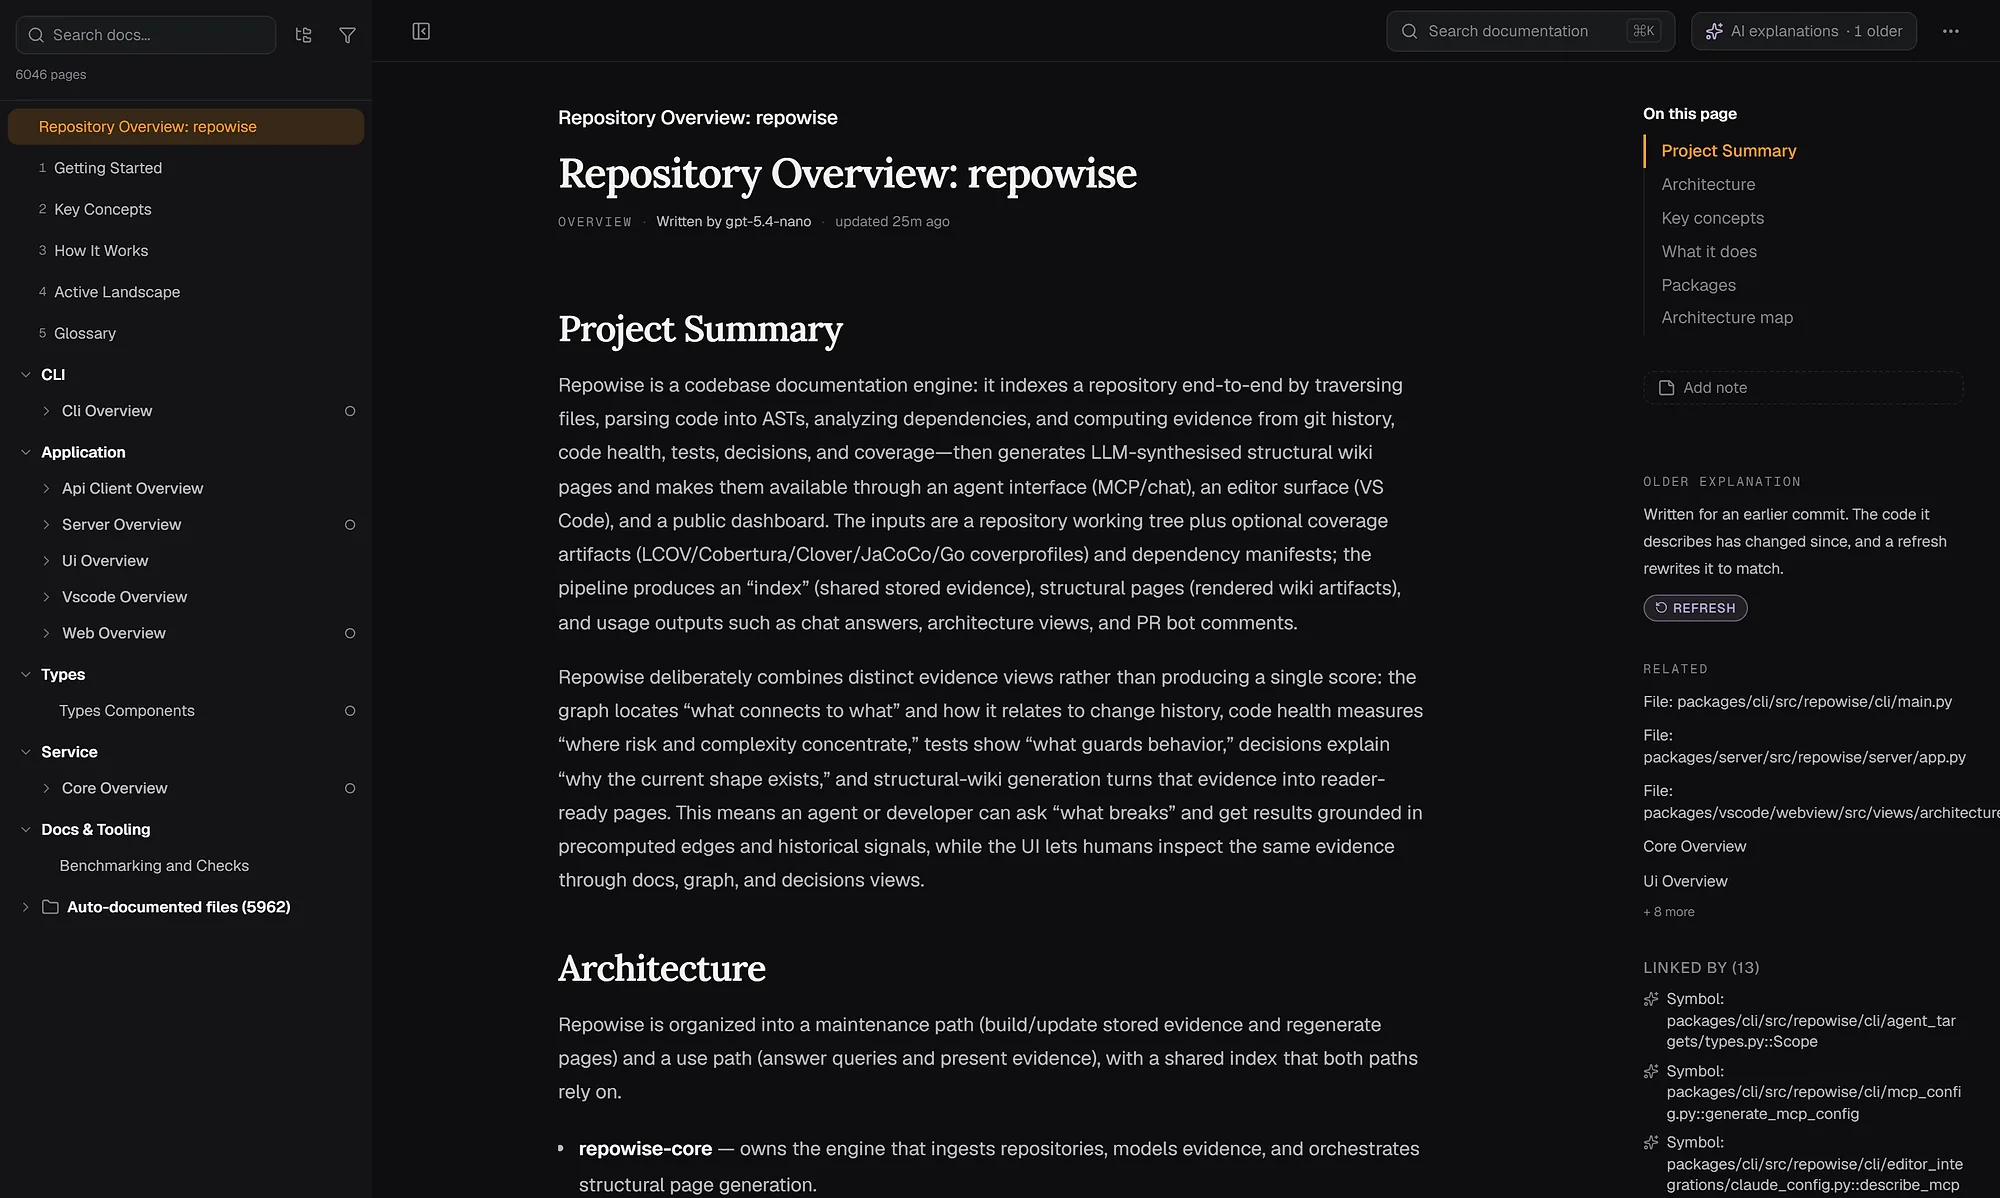
The agent never reads the index directly. It calls one of 10 tools, each shaped around a question, and gets back just enough: a triage card, a risk summary, one verified function body.
| Tool | The question it answers |
|---|---|
get_overview | What is this repo and how is it organized? |
get_answer | How does X work, or where does Y live? One cited, confidence-rated answer. |
get_context | Give me a triage card for these files, modules or symbols. |
get_symbol | Show me the exact source of this function. |
search_codebase | Find code by identifier, path or concept. |
get_risk | What breaks if I touch these files? |
get_change_risk | What is the defect risk of this commit or diff range? |
get_why | Why is the code shaped this way? Decision records and git history. |
get_dead_code | What is unreachable, unused or a zombie package? |
get_health | What are the defect, maintainability and performance signals? |
Scroll the table sideways to see every column.
Task-shaped tools move orientation work out of the prompt and into the index. A generic search tool makes the agent triage results itself. get_risk returns churn, owners and blast radius in one call. The full argument reference is in the MCP tools documentation.
What does an agent call look like?
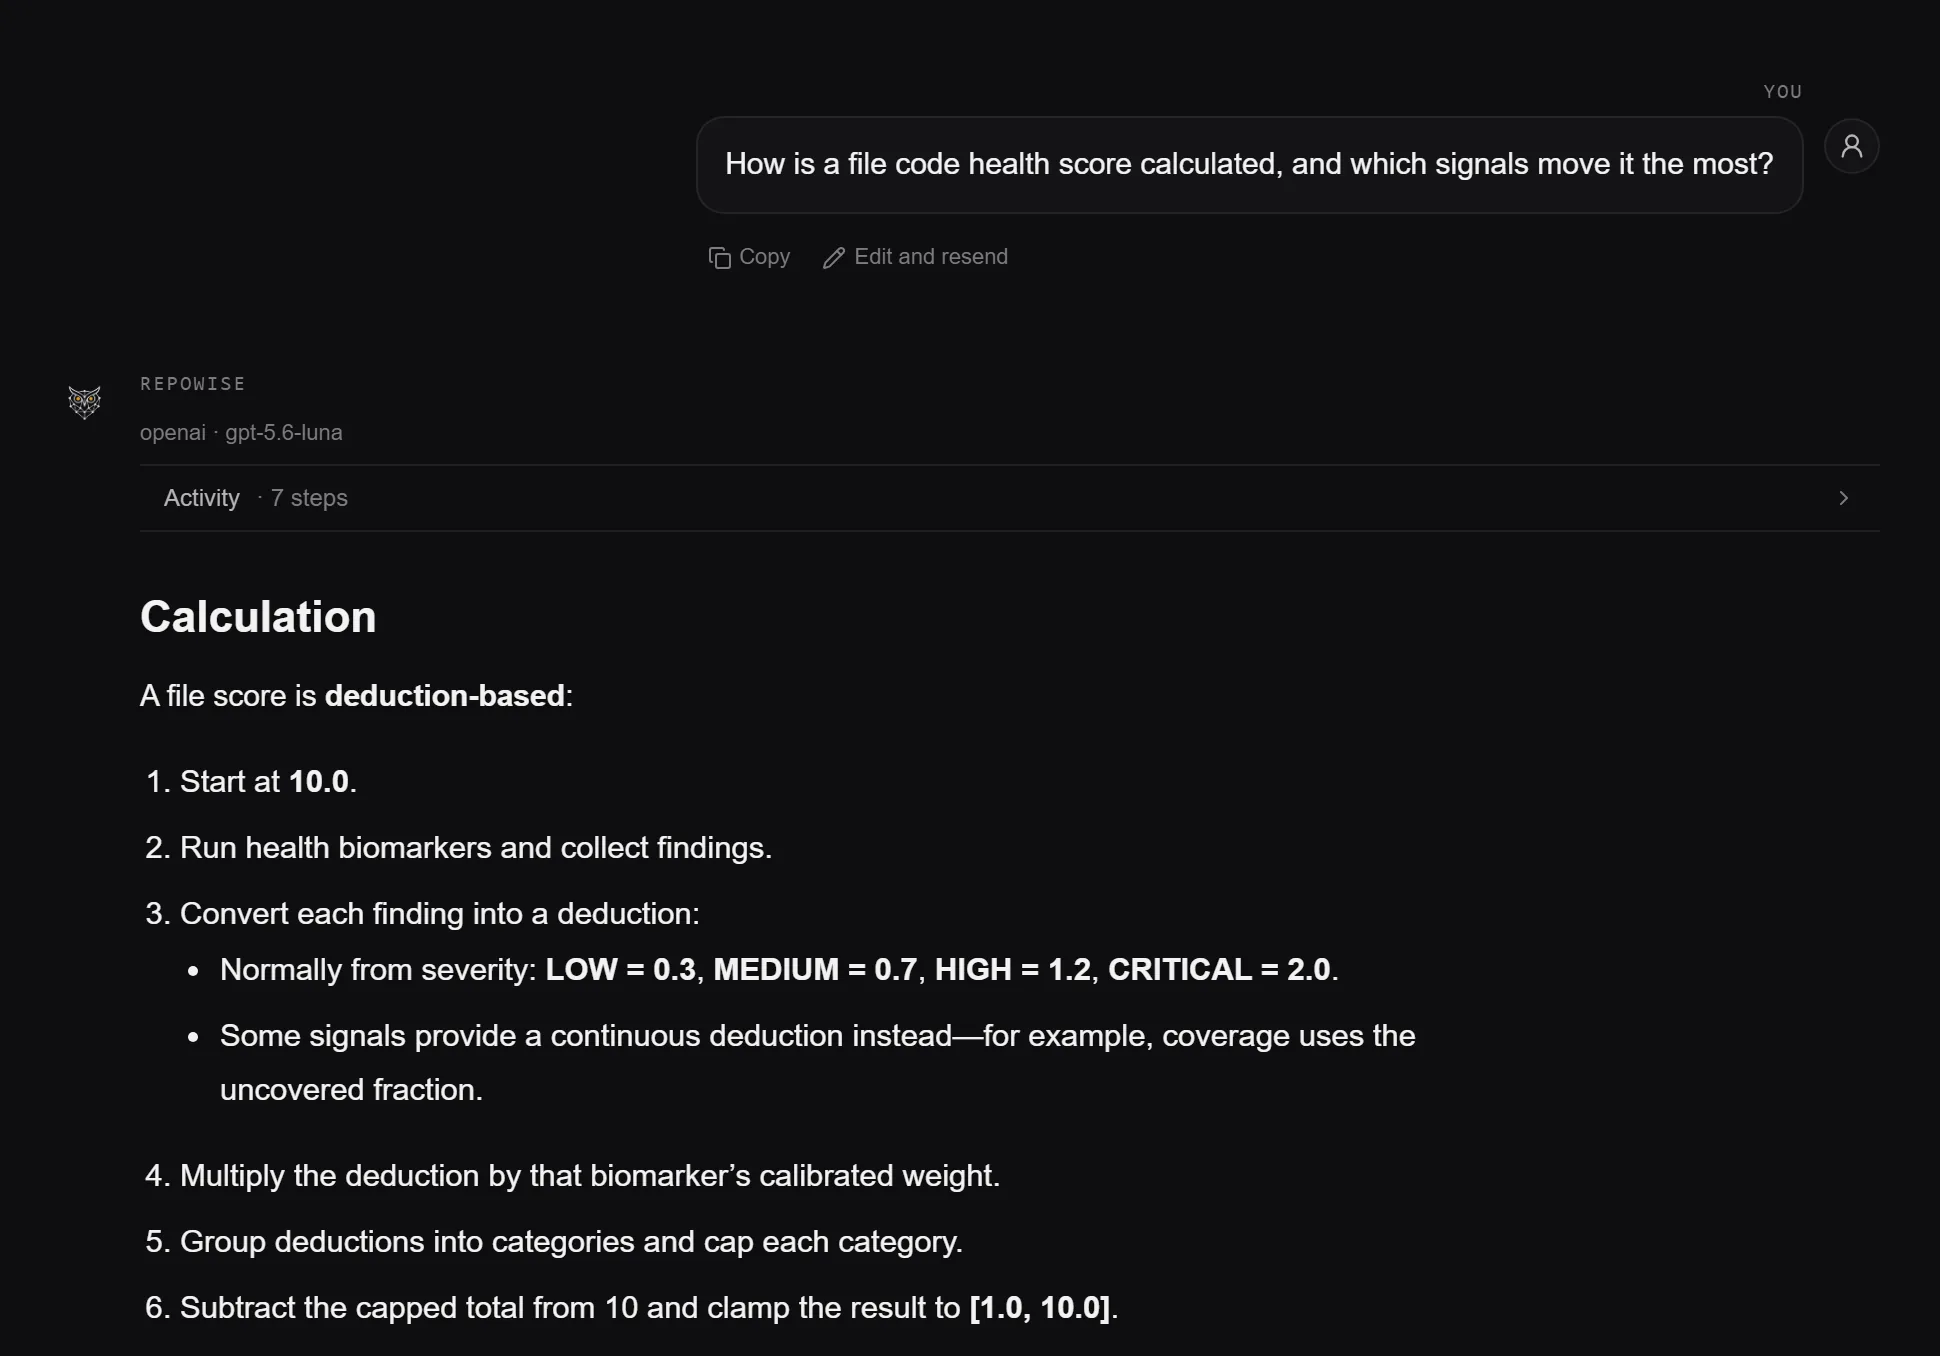
An agent asking a how-question makes one get_answer call and gets prose with citations and two quality fields, confidence (how good the prose is) and retrieval_quality (how good the evidence is). The same question in the product chat shows the shape of the answer:
For a change, the agent asks get_risk before editing a widely imported file and get_change_risk before committing a multi-file diff. For a pattern it is about to break, it asks get_why. That sequence is the one a senior engineer follows by habit: check the blast radius, then check why the code looks that way, then edit.
Why does structured context beat prompt-stuffing?
Prompt-stuffing means pasting files until the answer is probably in the window. It fails in three ways, and a longer window fixes none of them.
- It is wasteful. Most of a stuffed prompt is imports, boilerplate and comments unrelated to the task, and the model pays latency and cost to read them.
- It degrades recall. Detail buried in the middle of a long context is easier for a model to miss; research on long contexts found accuracy drops when the relevant passage is not at the start or end.
- It hides the signal. A file does not say that it is a churn hotspot, that three packages import its exports, or that it was last changed to fix a race condition. That knowledge is in the graph and the history.
We measured what the alternative buys. The run used Codex on django/django, 43 paired questions, against a bare-agent control (August 2026):
Every question in django's question set, six arms, byte-identical prompts, each tool's full advertised surface, and a freshly built index on the same pinned commit. Every tool was called on every question, so this is like for like.
| Tool | Agent used it | Output tokens | vs bare agent | Tool calls | Leaner on | p |
|---|---|---|---|---|---|---|
| repowise | 44 / 44 | 1,250 | -31.6% | 3.8 | 37 of 44 | <0.0001 |
| CodeGraph | 44 / 44 | 1,383 | -24.4% | 4.0 | 37 of 44 | <0.0001 |
| Serena | 43 / 43 | 1,550 | -14.8% | 10.1 | 35 of 43 | <0.0001 |
| Graphify | 43 / 43 | 1,658 | -8.9% | 7.4 | 31 of 43 | 0.003 |
| code-review-graph | 43 / 43 | 1,710 | -6.0% | 7.2 | 26 of 43 | 0.046 |
| bare agent (control) | 0 / 44 | 1,828 | baseline | 7.2 | n/a | n/a |
Scroll the table sideways to see every column.
Codex (gpt-5.6-sol) on django/django at one pinned commit. Correcting for testing five tools at once, three reductions are solid and two are marginal. 5 of the 48 questions are missing from every arm equally because the run hit an API usage cap, so the figures are over the 43 questions all six arms completed; because all arms lost the same 5, the paired comparisons are unaffected.
Fewer output tokens and fewer tool calls mean the agent holds the whole task in view and reaches an answer sooner. The result is for one repository, one commit and single-session questions, and the full method is on the benchmarks page.
How does an agent know the context is current?
Every tool response carries a _meta envelope. indexed_commit and live_head say which commit the answer describes and whether HEAD has moved. A stale_warning appears only when the index is behind in a way that changed the files served, or when a served file has uncommitted edits. Its absence means current.
Responses marked complete were verified against the live file, so the agent does not re-read them. When the working tree has edits, repowise update --working-tree refreshes the index for them, and repowise update re-indexes incrementally, reprocessing changed files rather than the whole repository.
Where does the index run?
Indexing builds the structural layer (graph, git history, health, dead code) with no LLM and no API key. Generated prose uses a model provider you configure, or a local model for fully offline use. repowise is open source under AGPL-3.0 and self-hostable, so your source and the intelligence built from it stay on your infrastructure. The hosted app is free for two public repositories, with private repositories on Pro.
Set it up
pip install repowise
cd your-repo
repowise init          # builds the index and registers the MCP server with Claude Code
repowise init --codex  # also writes project-local Codex config and hooks
For other clients, add repowise mcp as a stdio server. Setup walkthroughs for each editor:
- Set up an MCP server for Claude Code, Cursor and Cline
- Claude Code context for large codebases
- Cursor codebase context via MCP
- What is MCP?, the protocol underneath
- Give your agent context without prompt-stuffing, the token economics in detail
- Best MCP servers for coding agents
FAQ
- What is codebase context for AI agents?
- It is structured, queryable knowledge about a repository (architecture, dependencies, ownership, git history, health and risk) that an agent requests through tools when a task needs it. The agent reasons over targeted answers instead of raw pasted files.
- How is structured context different from a bigger context window?
- A bigger window lets you paste more text, but not more relevant or fresher text. Structured context returns a targeted answer, such as a risk summary or a cited explanation. In our Codex run on django/django it cut output tokens 31.6% against a bare agent.
- How many MCP tools does repowise expose?
- Ten:
get_overview,get_answer,get_context,get_symbol,search_codebase,get_risk,get_change_risk,get_why,get_dead_codeandget_health. Workspace mode adds a repository discovery tool, and a few specialist tools are opt-in throughmcp.toolsin.repowise/config.yaml. - How does an agent know the context is not stale?
- Each response carries a
_metaenvelope with the indexed commit and astale_warningthat appears only when the index is behind HEAD for the files served, or a served file has uncommitted edits. No warning means the answer is current. - Which agents does this work with?
- Any client that speaks the Model Context Protocol, including Claude Code, Codex, Cursor, Cline and Windsurf.
repowise initregisters Claude Code, andrepowise init --codexconfigures Codex. - Does my code leave my infrastructure?
- Not unless you choose a hosted model provider for generated prose. Indexing runs locally with no API key, repowise is AGPL-3.0 and self-hostable, and a local model gives a fully offline setup.