On this page
- Comparison at a glance
- What repository intelligence is
- The three shapes of tool
- Hosted context engines: Augment, Sourcegraph, Greptile
- Local code graphs: CodeGraph, Serena, GitNexus
- Broader indexes: repowise
- How to choose
- What the published numbers say
- A one-hour test on your own repository
- How we compared
- FAQ
Repository intelligence for coding agents is a prebuilt index of your codebase that an agent queries through tools, usually over MCP, instead of opening files one at a time. Choose on four things: what the index knows (structure only, or also git history and risk), where your code goes, which agents can connect, and cost.
The short version, as of October 2026:
- Code cannot leave your machines: CodeGraph, Serena, GitNexus (check its licence) or the open-source repowise engine.
- You want one index that also knows history, ownership and risk: repowise.
- You already run enterprise code search: Sourcegraph's MCP server.
- You want a managed engine inside an agent product: Augment Code's Context Engine.
- You mainly want pull request review against a whole-repo index: Greptile.
We build repowise, so weigh our entry accordingly. The measurements we publish about it, with their methods, are on the benchmarks page.
Comparison at a glance
| Tool | Code graph | Git history | Generated docs | Health and risk | Where code goes | Starting price (Oct 2026) |
|---|---|---|---|---|---|---|
| Augment Code Context Engine | Semantic index | Recent commits | No | No | Augment's cloud, or local via CLI | $20/month usage allowance |
| Sourcegraph | Search, symbols, navigation | Commit and diff search | No | No | Your servers or single-tenant cloud | Enterprise plan |
| Greptile | Whole-repo index behind an API | Used in reviews | No | Review comments | Greptile's cloud; self-host on Enterprise | Free Starter; Pro $1 per credit, no seat fee |
| CodeGraph | Call graph in local SQLite | No | No | Change impact | Local only | Free, MIT |
| Serena | Live symbols via language servers | No | No | No | Local only | Free; paid JetBrains backend |
| GitNexus | Knowledge graph, call chains, flows | Diff impact | LLM wiki | Blast radius | Local | Free for non-commercial use |
| repowise | Dependency and call graph, 28 languages | Hotspots, co-change, ownership, decisions | Yes | Health score, dead code, change risk | Local (AGPL-3.0) or repowise.dev | Free tier; Pro $15/month |
Scroll the table sideways to see every column.
I build repowise, so check its row the way you would check any other. The test at the end of this post runs on all seven.
What repository intelligence is
A repository intelligence tool reads your codebase once, keeps the result as an index, and answers an agent's questions from it. Without one, Claude Code or Cursor starts each task knowing nothing: it searches for strings and opens files until it finds enough. That works on a small project. On a large monorepo the agent spends most of its budget on files that turn out not to matter, and can still miss the file that breaks when the change ships.
With an index, the agent asks "where is checkout retry handled", "what calls this function", "what usually changes with this file", "who owns this module", and gets a short, sourced answer. MCP (Model Context Protocol) is the plug: a tool that speaks it can be added to Claude Code, Cursor, Codex, Windsurf and others with a few lines of config. You can keep the agent your team likes and swap the context underneath it.
The three shapes of tool
Hosted context engines: Augment, Sourcegraph, Greptile
Hosted engines run the index for you, which buys scale and costs you data residency.
Augment Code prices usage in dollars across models, Context Engine and compute: Standard is $20 a month with a $20 allowance, Business $100, and MCP access is included on paid plans. Its Context Engine can be used from other MCP agents, with a local mode through its CLI.
Sourcegraph is the most mature code search platform. Its MCP server, available on Enterprise plans, exposes keyword and natural-language search, symbol definitions and references, commit and diff search and Deep Search. If you already run it, it is a strong context layer.
Greptile is review-first: it indexes your repositories and comments on pull requests, with an API and MCP server for questions about the codebase. As of November 2026, per its pricing page, the Starter tier is free for one developer with 50 monthly credits, Pro is $1 a credit with no seat fee, and self-hosting is on Enterprise.
Local code graphs: CodeGraph, Serena, GitNexus
Local tools keep code on your machine and differ in how they build the graph.
CodeGraph parses 20+ languages into a call graph stored in SQLite and exposes mainly one tool, codegraph_explore, that returns relevant source and call paths in a single call. It is MIT licensed and the quickest of this group to build. It is the right pick when a fast call graph is all you want.
Serena builds no persistent graph. It asks language servers, the engines behind your editor's go-to-definition, for symbols, references and type hierarchies, and adds symbol-level editing and renaming across 40+ languages. A paid JetBrains backend adds moves and inlining.
GitNexus builds a knowledge graph of dependencies, call chains and execution flows, with blast radius analysis, change detection, graph-aware rename and a generated wiki. It is licensed PolyForm Noncommercial, so commercial teams need a separate licence.
Broader indexes: repowise
repowise indexes more than the call graph: it adds the history and judgement a graph cannot hold. One local index combines the dependency and call graph with git history (hotspots, co-change, ownership), architectural decisions, generated docs, a code health score, dead code and change risk. Agents reach it through ten default MCP tools:
| Question | Tool |
|---|---|
| How does X work? Where is Y? | get_answer |
| What is the shape of this repo? | get_overview |
| What is in this file, who calls this, who owns it? | get_context |
| Is this file risky to touch? | get_risk |
| What could my diff break? | get_change_risk |
| Why was it built this way? | get_why |
Scroll the table sideways to see every column.
pip install repowise
repowise init --yes --no-prose   # graph, git, health, dead code. No API key, no spend.
repowise mcp                     # serve the index to Claude Code, Codex, Cursor
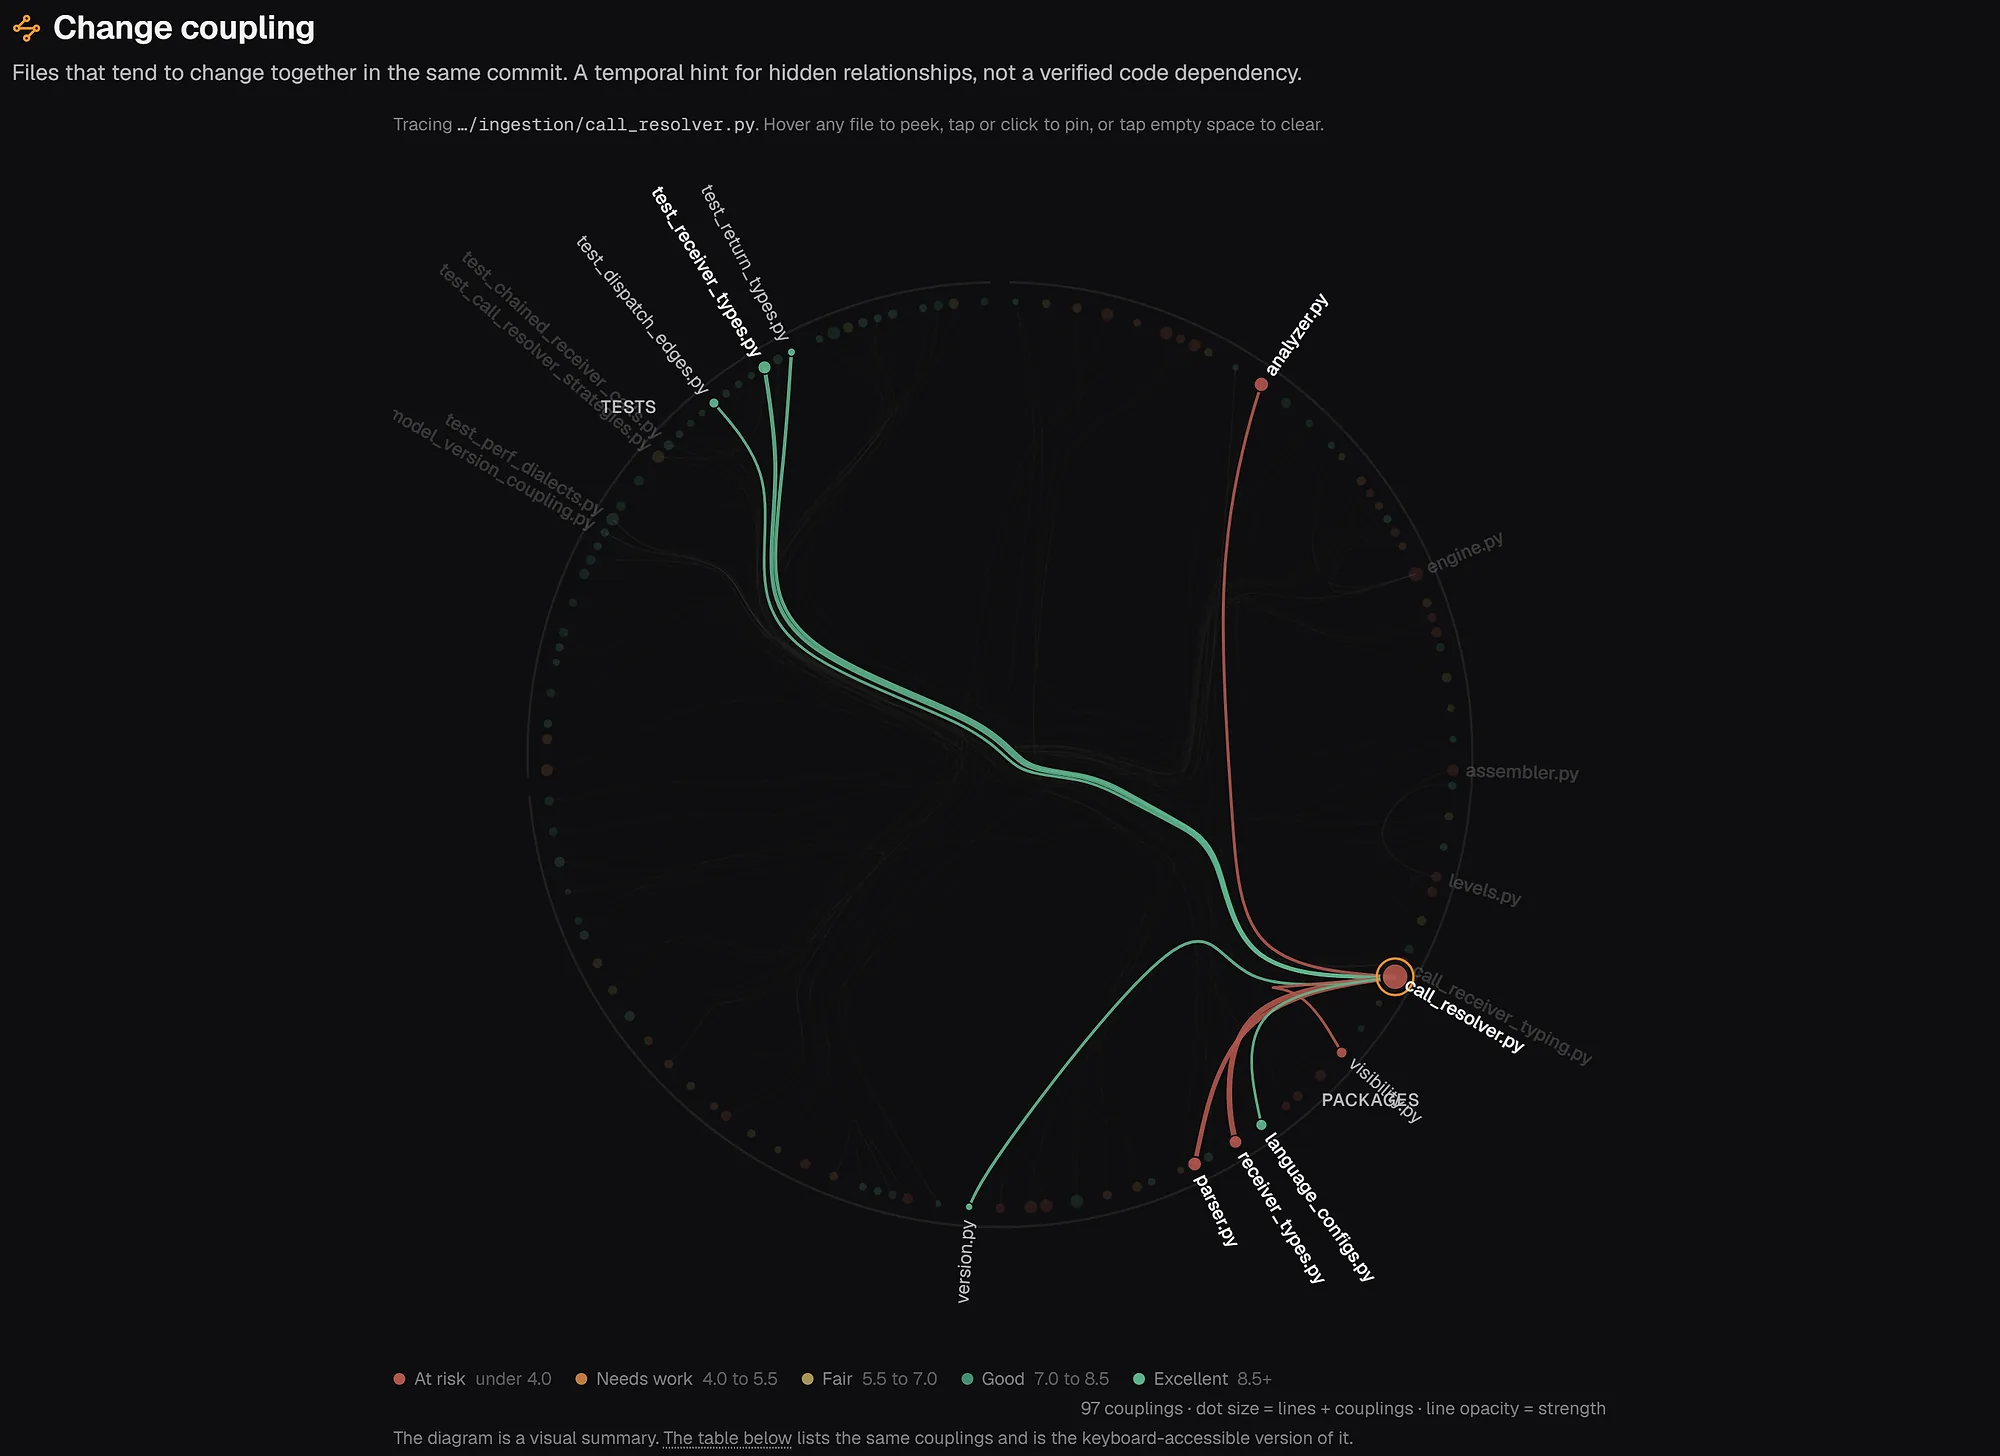
Co-change is the signal worth seeing for yourself. It shows files that change together with no import between them, which is where an agent's "safe" edit usually breaks something.
How to choose
Start with the constraint you cannot move, then pick on what the index must know.
- Code cannot leave your network: hosted engines are out unless you buy a self-hosted tier. Use CodeGraph, Serena, GitNexus (licence permitting) or the open-source repowise engine.
- You need the index in browser chat as well as an IDE: Claude.ai and ChatGPT run on someone else's servers and cannot reach an MCP server on your laptop, so you need a hosted address. Augment, Sourcegraph, Greptile and repowise.dev all provide one.
- Agents keep breaking files they did not touch: you need history in the index. Files that break together are often not linked by imports, so a call graph will not show them. Co-change (repowise) and diff impact (GitNexus) address this.
- Agents burn tokens finding files: any graph tool helps. Measure it yourself first; see below.
- The budget is zero: CodeGraph and Serena are free, the repowise engine is free, and hosted repowise starts free with Pro at $15 a month.
What the published numbers say
There is no neutral, widely accepted benchmark for this category, so read every vendor number, ours included, with its conditions.
On ContextBench (bug reports from real GitHub issues, graded on whether the tool found the files the real fix touched), repowise's get_answer scored 0.876 file coverage on 42 sealed instances against 0.610 for CodeGraph. That measures retrieval only: the right files were found, not that an agent then wrote better code. In a real Codex agent loop on django, output tokens fell 31.6% against a bare agent. The full method, including the first run where we scored last, is in we benchmarked ourselves and came last.
Latest result: agents open up to 99% fewer files with repowise and write up to 51.2% less (Sonnet 4.6), every model tested opened fewer files, and the newest flagship, Opus 5.5, got 48 of 48 answers right (benchmarks).
Single-payload numbers are bigger and answer a different question: loading one commit's context took 35.6x fewer tokens than reading every changed file. The 35x or 16 percent write-up explains why both are true. We have not rerun Augment's, Sourcegraph's or Greptile's published results, and you should treat any of them as a reason to run your own test.
A one-hour test on your own repository
The test that should decide between these tools uses your code and your questions.
- Pick five questions you actually had last month: one "where is X handled", one "what breaks if I change Y", one "why is Z built this way", one cross-module question, and one about a file nobody knows well.
- Run each in your agent with no context tool. Record the answer, the files opened and the tokens used.
- Add one tool and run the same five in fresh sessions. Keep the agent and model identical.
- Have a senior engineer on that code grade each answer: right, partly right, wrong.
- Repeat for the next tool.
Watch whether the agent calls the tool at all, since a connected MCP server is often ignored when its tool descriptions do not match how the agent thinks about the task. Then check freshness by asking about code merged yesterday. To see an index before installing anything, open any public repository on repowise.dev and connect it to your agent with one URL.
For the idea itself, see giving AI coding agents real codebase context, the best MCP servers for coding agents and the AI context feature page.
How we compared
Each row was checked against the tool's own pricing page, documentation or repository on 12 October 2026. "Git history" means the index reads commit history itself, not that the tool can call git. We did not run the one-hour test on all seven tools for this post. Prices and features in this category change monthly.
FAQ
- What is a context layer for AI coding agents?
- It is a service between the agent and your code that answers questions from a prebuilt index: where things are, what depends on what, what changed recently, what is risky. The agent calls it through tools, usually over MCP, instead of reading files until it finds the answer.
- What are the best codebase indexing tools for AI agents in 2026?
- The ones most teams evaluate are Augment Code's Context Engine, Sourcegraph, Greptile, CodeGraph, Serena, GitNexus and repowise. They differ mainly in whether they read git history, whether they add docs and risk signals, whether your code leaves your machine, and price.
- Which indexing tools work with Claude Code and Cursor?
- All seven in this guide can be reached from Claude Code and Cursor through MCP. Sourcegraph's MCP server requires an Enterprise plan, and Augment's requires a paid plan.
- What is the best tool for indexing both code and dev docs?
- If "dev docs" means documentation generated from your code, GitNexus and repowise both produce a wiki from the index. If it means third-party library documentation, that is a different job covered by tools such as Context7, and many teams run one of each.
- Do I need a context tool if my agent has a large context window?
- A large window lets the agent hold more, but it still has to find the right files, and you pay for every token it reads. A context tool cuts the reading and adds what a file read cannot give, such as history and ownership. Test both ways on your own repository.
- Is it safe to send private code to a context engine?
- It depends on the vendor's data handling and your rules. Check where code is processed, what is stored after indexing and which model providers see excerpts. If code cannot leave your network, use a local tool or a self-hosted tier.