On this page
- Why agents need tools beyond file reads
- The ten tools at a glance
- 1. get_overview: orient once
- 2. get_answer: ask in plain language
- 3. search_codebase: find the symbol
- 4. get_context: triage before reading
- 5. get_symbol: the exact bytes
- 6. get_risk: what history says about a file
- 7. get_change_risk: review a diff
- 8. get_why: the intent behind the code
- 9. get_health: what to fix and whether an edit helped
- 10. get_dead_code: a deletion hit list
- A call order that works
- Reading the response envelope
- Set it up
- FAQ
The most useful MCP tools for a coding agent answer a question about the repository in one call, so the agent reads fewer files and edits with more context. repowise serves ten of them over the Model Context Protocol: get_answer, get_overview, get_context, get_symbol, search_codebase, get_risk, get_change_risk, get_why, get_health and get_dead_code. This post covers what each returns, when to call it, and the order that works.
Part of the AI Context & MCP guide.
Why agents need tools beyond file reads
An agent that can only read files rebuilds the same understanding every session. It greps, opens files, guesses which ones matter, and spends its context window on boilerplate. A larger window helps with capacity, not with direction: the agent still does not know which file is the entry point, which one breaks most often, or why a pattern exists.
Three things live outside the current text of a file, and an agent cannot see them by reading it:
- Structure: who calls a function, what imports a module, how the packages relate.
- History: how often a file changes, which fixes landed in it, who owns it, which files change with it.
- Intent: the decision behind a design, recorded in a decision record, a commit or a rationale comment.
repowise indexes all three once and serves them through MCP. The agent asks a question and gets a bounded, sourced answer. For the wider case, see giving AI coding agents real codebase context.
The ten tools at a glance
Each tool maps to one kind of question. The table is the whole default surface in a single-repository server. Full parameters are in the MCP tools reference.
| Tool | Answers | Call it when |
|---|---|---|
get_overview | What is the shape of this repo? | First action in an unfamiliar repo |
get_answer | How does X work? Where is Y? | Any how, where or why question |
search_codebase | Which symbol, file or page matches this? | You need ranked hits or an exact symbol id |
get_context | What is in these files, who calls them, who owns them? | Before reading or editing code |
get_symbol | What is the exact body of this symbol? | After another call named the symbol |
get_risk | Is this file risky to touch? | Before a non-trivial edit |
get_change_risk | What did this diff make worse? | Before committing or merging |
get_why | Why was it built this way? | Before a refactor or a pattern change |
get_health | What should we fix first? Did my edit help? | Planning work and self-checking edits |
get_dead_code | What can we delete? | A cleanup pass |
Scroll the table sideways to see every column.
1. get_overview: orient once
get_overview returns the architecture map of the repository in one call. That is the summary, key modules, entry points, layers, code and git health, and next actions. An agent calls it first in an unfamiliar repo and skips it afterwards, because it does not change within a session.
get_overview()
get_overview(include=["outline", "tour"])
The include list opens larger blocks on request: the wiki page outline, a guided tour with reading order, community clusters, decisions and top owners. Defaults stay small on purpose.
2. get_answer: ask in plain language
get_answer is the first call for any how, where or why question. It runs hybrid retrieval over the wiki and the symbol index and returns a cited answer, with the live bodies of the symbols it names.
get_answer(question="How does the authentication flow work?", scope="src/auth/")
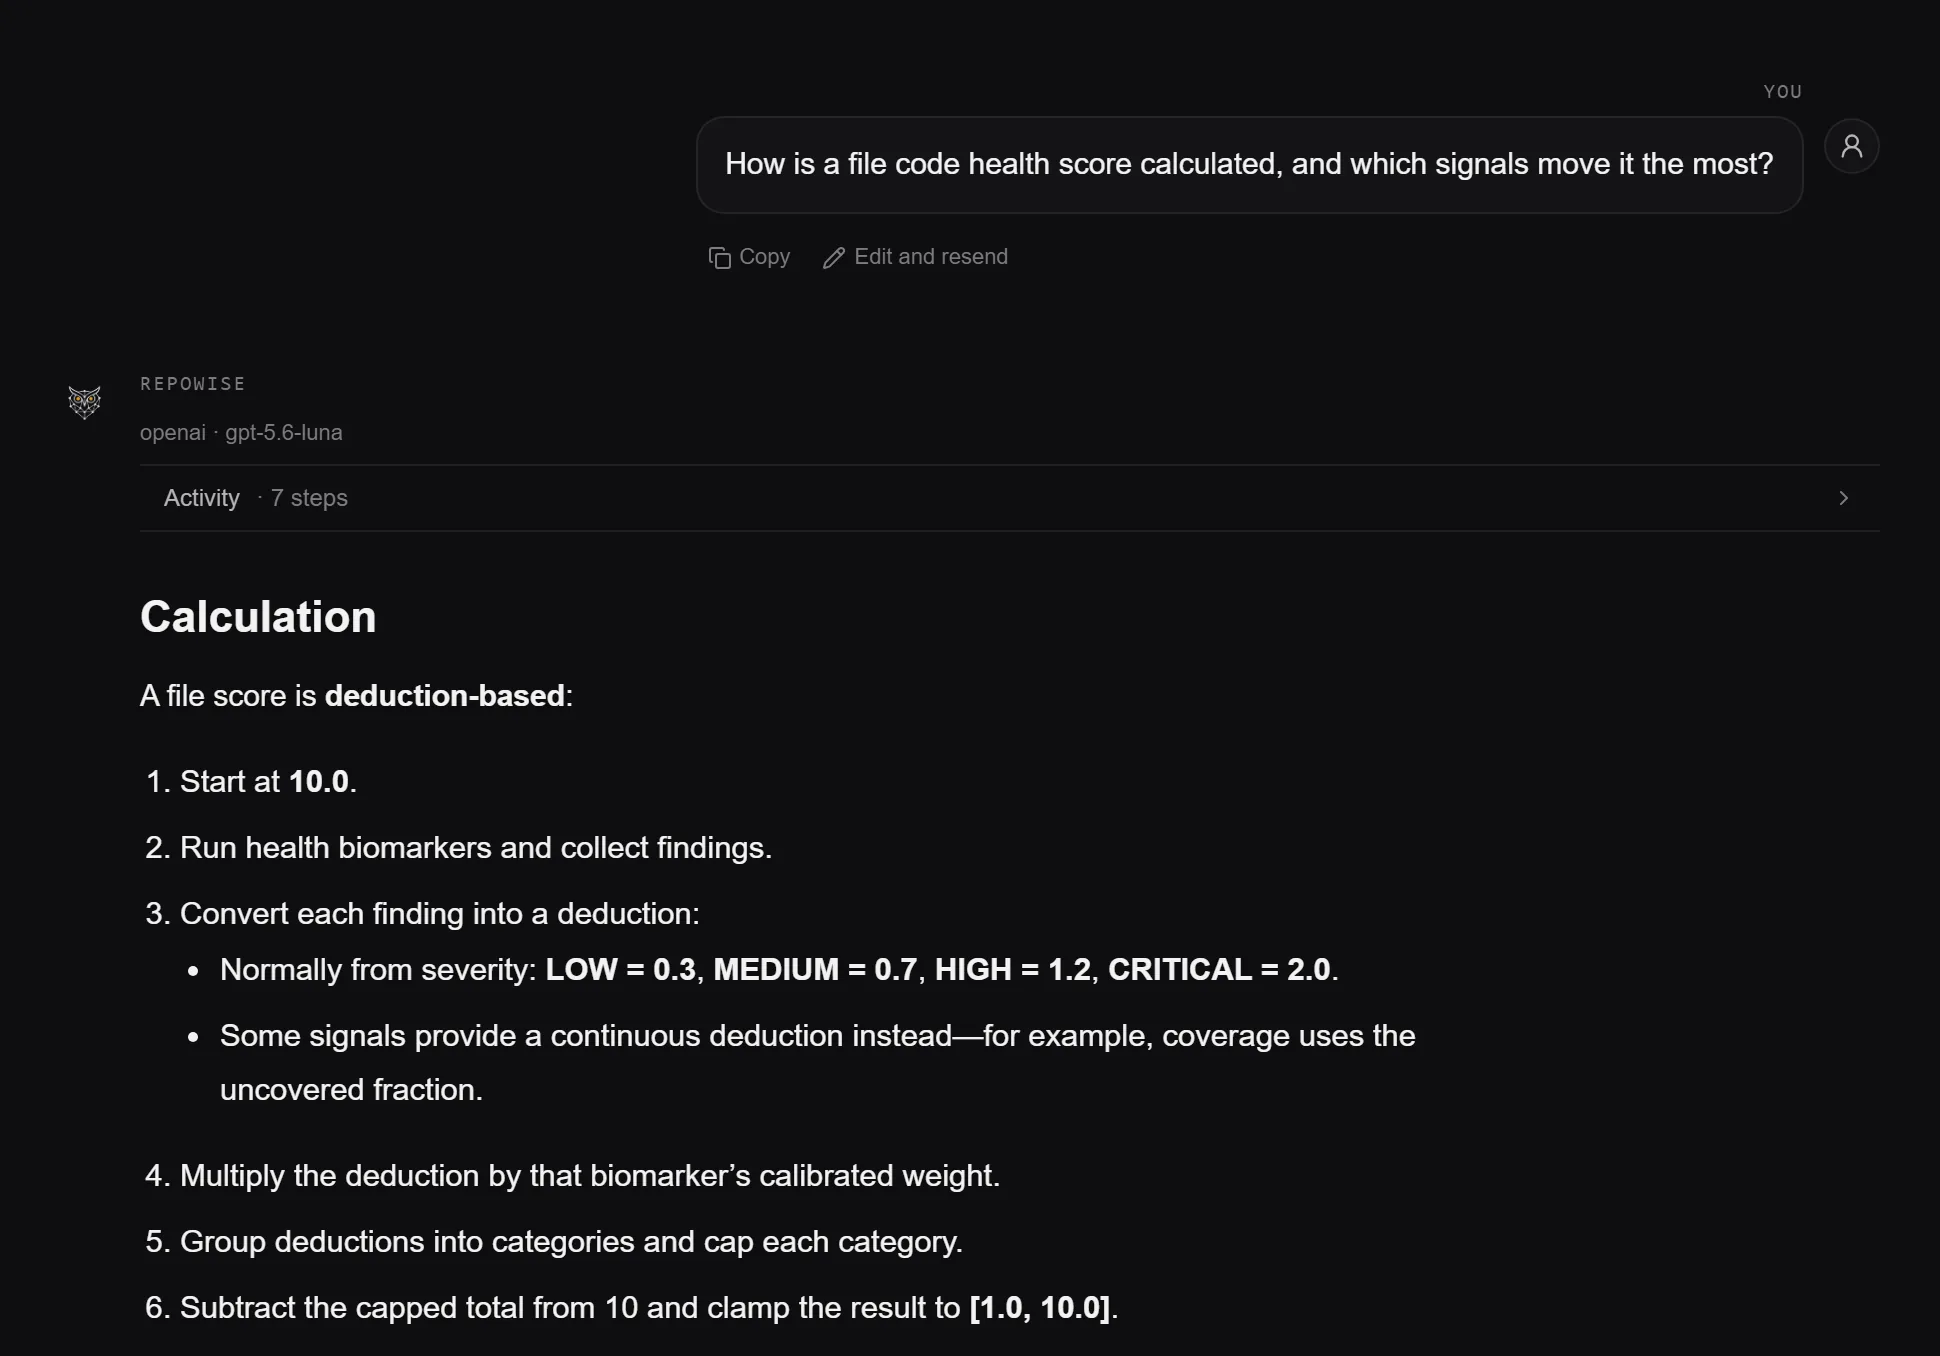
The response carries two ratings: confidence rates the prose and retrieval_quality rates the evidence. A high answer can be cited directly. On low, the reply names candidate_files to read next. Without an LLM provider configured the tool still answers from retrieval and marks the reply degraded.
3. search_codebase: find the symbol
search_codebase routes by the shape of the query. Identifiers search the symbol index, paths resolve files, prose runs semantic search over the wiki, and mixed queries run both.
search_codebase(query="GitIndexer index_repo")
search_codebase(query="login", mode="symbol", symbol_kind="method")
An identifier query also returns lines, every live line naming it, definitions first. When complete is true, that list is every match, which is the edit set for a rename. Use it for ranked hits and symbol ids. For a question, call get_answer, which runs the same retrieval internally.
4. get_context: triage before reading
get_context returns a triage card for several files, modules or symbols in one call. Each card holds a summary, the symbols with signatures and line numbers, hotspot and fix-history cues, owners and decisions. It returns relationships, not source.
get_context(targets=["src/auth/middleware.ts", "src/api/routes.ts"], include=["callers"])
get_context(targets=["src/big_module.py"], include=["skeleton"])
The skeleton view renders a large file with bodies elided: every signature, the imports and the bodies of the most central symbols. For a symbol target, references lists every live line that names it. That replaces a round of grep before a rename.
5. get_symbol: the exact bytes
get_symbol returns verified, line-numbered source for one symbol or one line range. It is a follow-up call for an id another response gave the agent.
get_symbol(symbol_id="src/auth/service.py::login", depth=2)
get_symbol(symbol_id="src/auth/service.py:140-180")
depth=2 also returns the bodies the symbol calls. When a response is marked _meta.complete, the bytes were checked against the live file, so the agent does not need to re-read it.
6. get_risk: what history says about a file
get_risk reports the hotspot score, bug-fix record, owners, co-change partners and dependents of a file. A file that changes often and is complex is where bugs concentrate. Co-change partners are the files that usually change in the same commit, so an edit to one is a prompt to look at the others.
get_risk(targets=["src/auth/middleware.ts"])
get_risk(changed_files=["src/api/routes.ts", "src/middleware/cors.ts"])
Passing changed_files switches on PR mode. The response then leads with a directive: what may break, which co-changing files the change is missing, and which tests to run. Learn more on the change risk feature page.
7. get_change_risk: review a diff
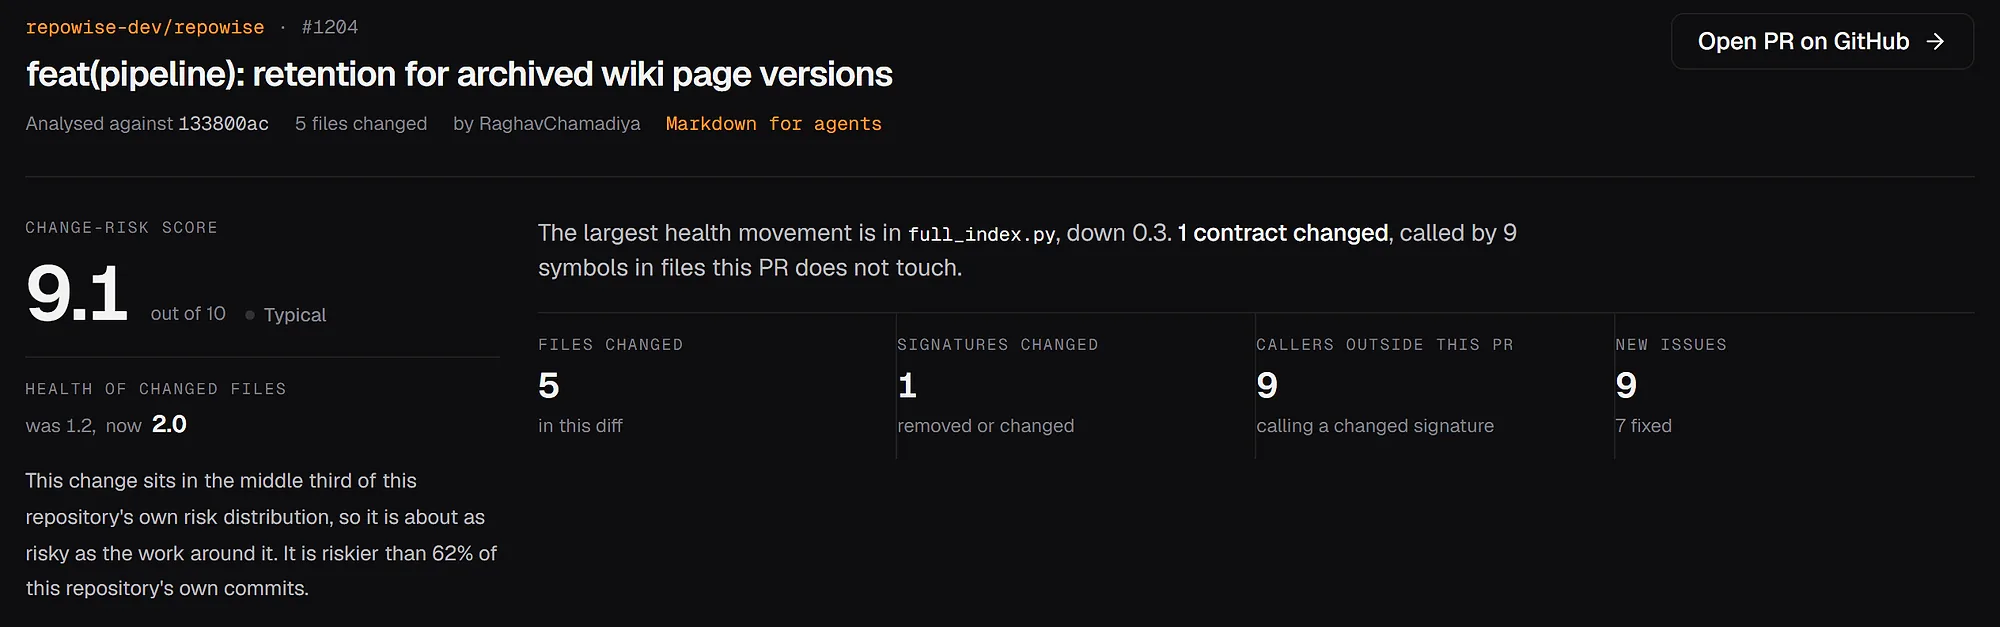
get_change_risk reviews a commit, a base..head range or uncommitted work by comparing the two revisions. It reports what the change made worse across defect risk, maintainability and performance, which tests cover the changed lines, and the bug-fix record of the files touched. It needs no index refresh and no LLM call.
get_change_risk()
get_change_risk(revspec="main..HEAD", exclude_patterns=["tests/"])
directive.status is the verdict: review_required, review_recommended, clear_in_analyzed_scope or unknown. An agent can run it on its own diff before proposing the change, the way a careful engineer re-reads a diff before opening a pull request.
8. get_why: the intent behind the code
get_why answers why code is shaped the way it is, from decision records first. Where no decision governs a path, it falls back to git archaeology and rationale comments mined from the code.
get_why(query="why JWT over sessions?")
get_why(query="src/payments/processor.ts")
get_why()
The response separates decisions (accepted, binding) from candidates (inferred, hints rather than rules). With no arguments it returns the decision health dashboard. See decisions for how records are captured.
9. get_health: what to fix and whether an edit helped
get_health returns code-health scores and findings across defect risk, maintainability and performance. Without targets it returns a dashboard led by fix_first, one ranked queue of what to work on. With targets it scores those files. It reads stored analysis and makes no LLM calls.
get_health(only=["fix_first"], limit=25)
get_health(targets=["src/api/server.py"], include=["signals"])
Agents use the second form as a self-check on files they just changed. Run repowise update, then ask again to see new numbers. More on the code health feature page.
10. get_dead_code: a deletion hit list
get_dead_code lists unreachable files, unused exports and unused packages, tiered by confidence. safe_only leaves out anything with runtime-load risk, such as dynamic imports and framework-registered functions.
get_dead_code(tier="high", safe_only=true)
get_dead_code(kind="unused_export", group_by="owner")
Use it for a cleanup pass, not a targeted fix. For the method behind it, see how to find dead code in your repository.
A call order that works
Orient, find, assess, read, edit, check. This is the sequence we see agents settle into on a real task, such as changing a webhook handler:
get_overviewonce, to learn the layout.get_answer("how are stripe webhooks handled?"), orsearch_codebasefor the exact symbol.get_contexton the files named, withinclude=["callers"].get_riskon the file about to change.get_symbolfor the body that must change.- Edit.
get_health(targets=[...])on the edited files, thenget_change_riskon the diff.
Steps 1 to 5 replace most of the file opening an agent would do blind. Steps 6 and 7 move review from the pull request to the moment of the edit. Benchmark results for this approach are on the benchmarks page.
Reading the response envelope
Every tool returns a _meta envelope that tells the agent how far to trust the result. Three fields matter most:
stale_warning: present when the index is behind in a way that changed the files served. Runrepowise updatebefore trusting file-level detail.complete: the symbol bodies or files served were verified against the live file. Do not re-read them.omitted: refs to content cut for size, restorable withrepowise expand <ref>orget_symbol("repowise#<ref>").
An empty callers list comes with a *_basis field that says how much of that language's calls the graph resolved, so an agent does not read a zero as proof.
Set it up
repowise init indexes the repository and registers the MCP server with Claude Code. It needs no API key for the structural index.
pip install repowise
cd your-repo
repowise init
repowise mcp   # stdio server for Claude Code, Codex, Cursor
The parser covers 27 languages with a full AST. Setup steps for Claude Code, Cursor and Cline are in the MCP setup guide.
FAQ
- Which AI agents can use these MCP tools?
- Any client that supports the Model Context Protocol, including Claude Code, Codex, Cursor, Cline and Windsurf. The server runs over stdio by default and over streamable HTTP with
repowise mcp --transport streamable-http. - How many MCP tools does repowise expose?
- Ten by default, in a single-repository server. Workspace mode adds
list_reposfor discovering repositories. A few specialist tools, such asget_execution_flows, are opt-in through.repowise/config.yaml. - Do the tools edit my code?
- No. They read from the index and answer questions. The agent makes every edit. Two opt-in tools go further: one records a triage verdict in the index, and one drafts a diff with your configured LLM.
- Do I need an LLM key to use them?
- The structural index and most tools work without one.
get_answerstill answers from retrieval without a provider and marks the replydegraded. A provider adds synthesized, cited answers. - Is my code sent anywhere?
- repowise is open source under AGPL-3.0 and runs on your machine. The index lives in your repository's
.repowisedirectory. Only an LLM provider you configure for synthesis receives text. - Which tool should an agent call first?
get_overviewin an unfamiliar repository, thenget_answerfor the actual question. In a repository the agent already knows, start atget_answerorget_context.