On this page
To onboard engineers faster, shrink the distance between cloning the repo and changing the right file for the right reason. That takes four pieces of context in a fixed order: the shape of the system, where the first ticket lands, why the code is built that way, and who and what a change affects. repowise generates all four from the code and git history, so a new hire reads a current map instead of a README from 2021, and the senior who would have given the tour keeps working.
What does codebase onboarding involve?
Codebase onboarding is getting an engineer from zero context to safe, independent contribution in a repository they did not write. It covers four jobs: orienting on structure and entry points, finding where a change belongs, recovering the reasoning behind existing design, and knowing the blast radius and owners before a pull request.
Most teams treat this as a documentation problem and write more docs. A doc is a snapshot of a moving system, and it starts drifting the day it is merged. Treat it as a context problem instead: the new hire needs an accurate answer to a specific question, at the moment they ask it, grounded in the code as it is today.
Day 1 to 3: orient on the whole system first
The first hours go to a map, not to opening random files. You want the product boundary, where control enters the system, the main modules and layers, and which areas are risky.
repowise init indexes the repository and builds a wiki from the code itself: an overview page, a page per module, and an architecture graph. It parses 28 languages to a full AST, so a polyglot monorepo gets one map instead of a patchwork. The same map is available to an agent through get_overview, which returns the summary, key modules, entry points and layers, and, with include=["tour"], a guided reading order.
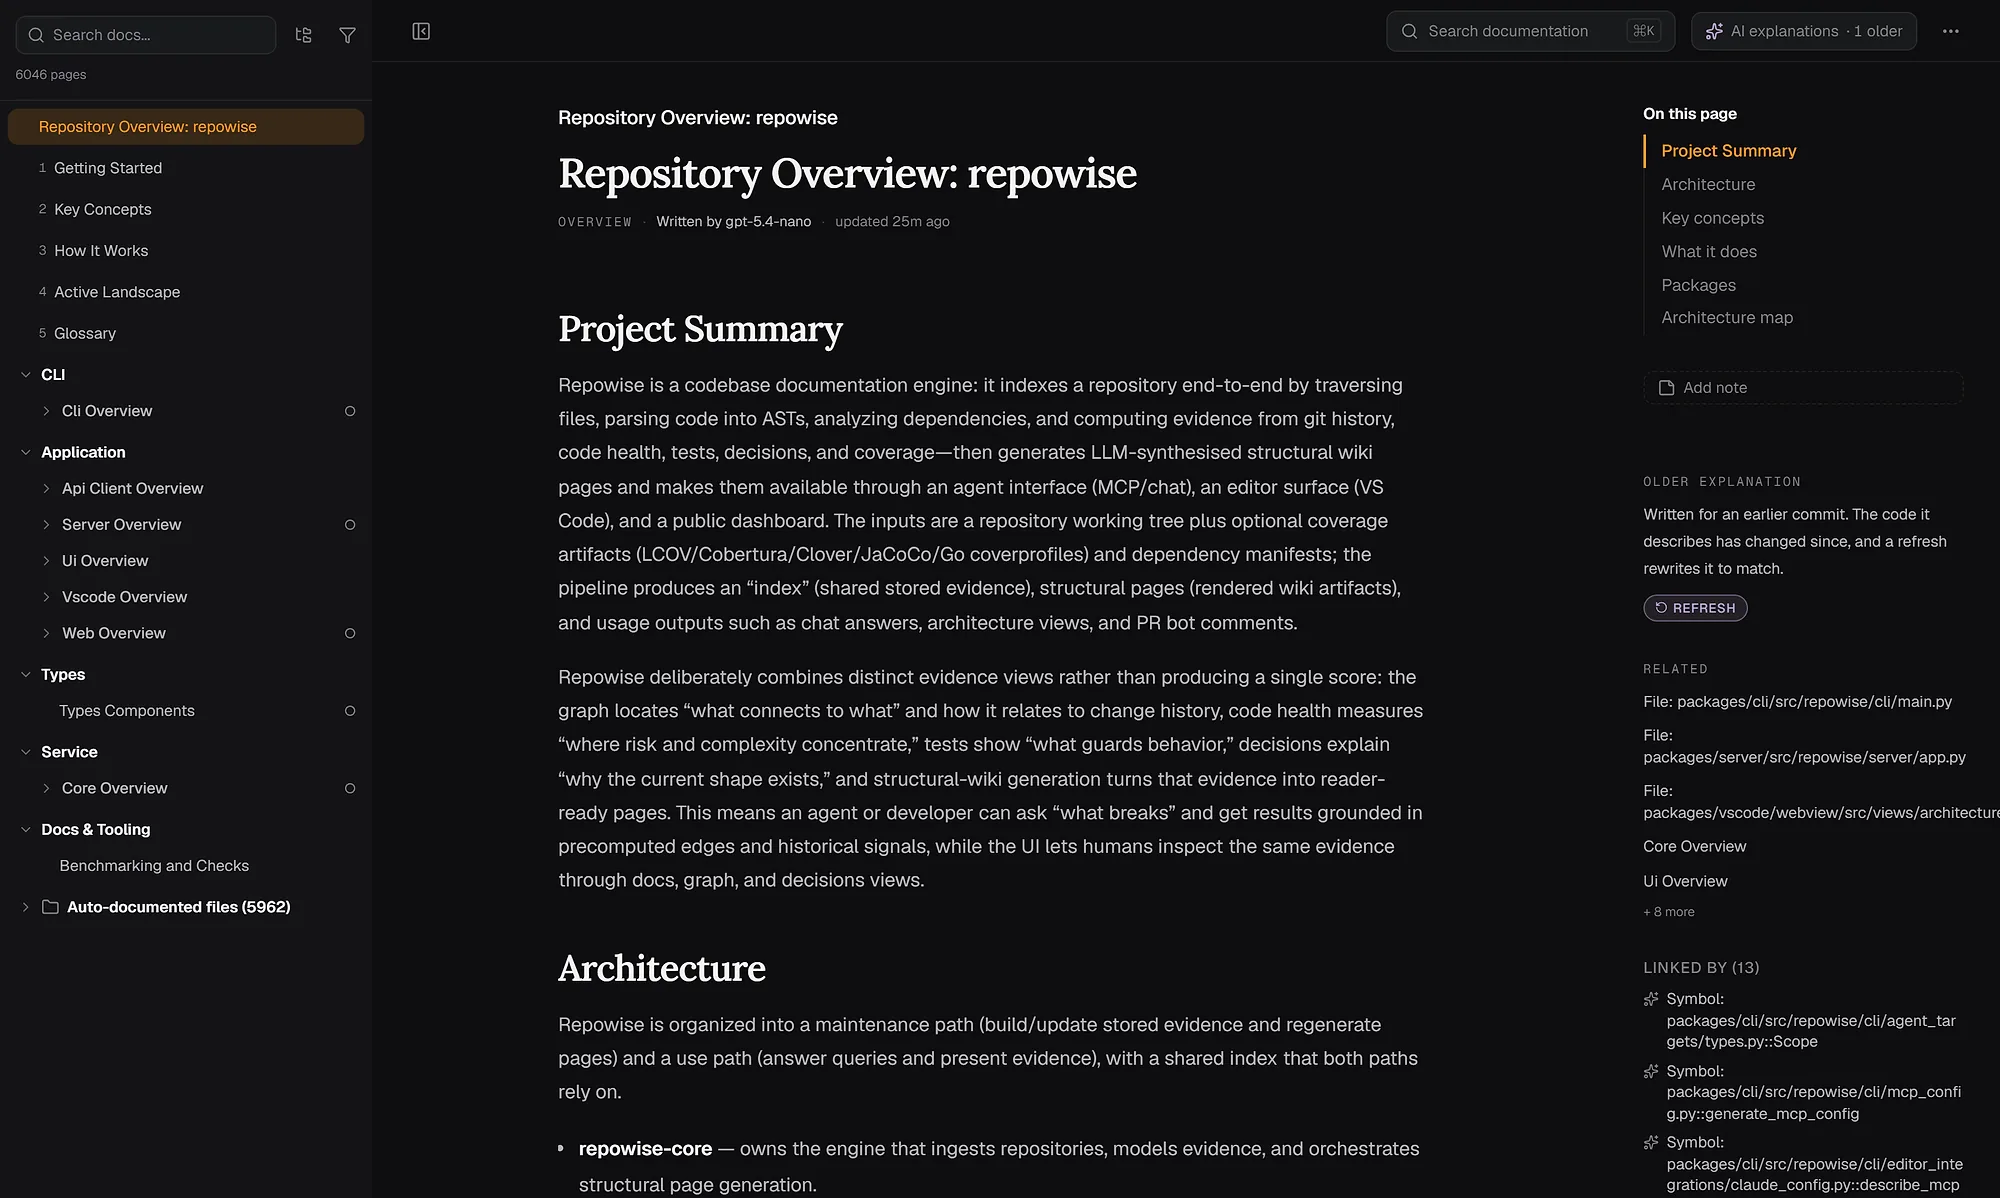
The practical payoff is the questions that stop reaching Slack. "Which service owns checkout?" and "where do requests come in?" become a lookup. Reading the overview and the tour in order takes an afternoon, and it is the same material a senior would have walked through on a call.
Day 4 to 10: find where the ticket lands
Search by concept, then read the file card before the file. Engineers rarely know the right symbol name on day four, so search_codebase takes a description ("where do we retry failed webhooks") and ranks files, symbols and wiki pages, while an exact identifier returns every live match.
For each candidate, get_context gives a triage card without the source: what the file does, its signatures, who calls it, its owner and its fix history. get_context(include=["skeleton"]) shows a large file's structure without reading all of it. For a "how does this flow work" question, get_answer returns one cited answer from the index, and its symbol_bodies carry live code.
search_codebase(query="retry failed webhooks")
get_context(targets=["src/billing/webhooks.py"], include=["skeleton"])
get_answer(question="how does a failed webhook get retried?")
Day 11 to 20: recover the why behind legacy code
The hardest part of a legacy repo is not what the code does but why. The engineer who chose that retry strategy or that odd data shape left two years ago, and the reasoning left with them. A new hire who cannot see the reason either asks around or "cleans it up" and reintroduces the original bug in week one.
get_why answers this in layers, strongest first. Accepted decision records are binding rulings. Inferred candidates are hints that nobody has accepted yet. When neither exists for a path, it falls back to git archaeology and rationale mined from comments, so a repo that never wrote an ADR still produces a reasoned account.
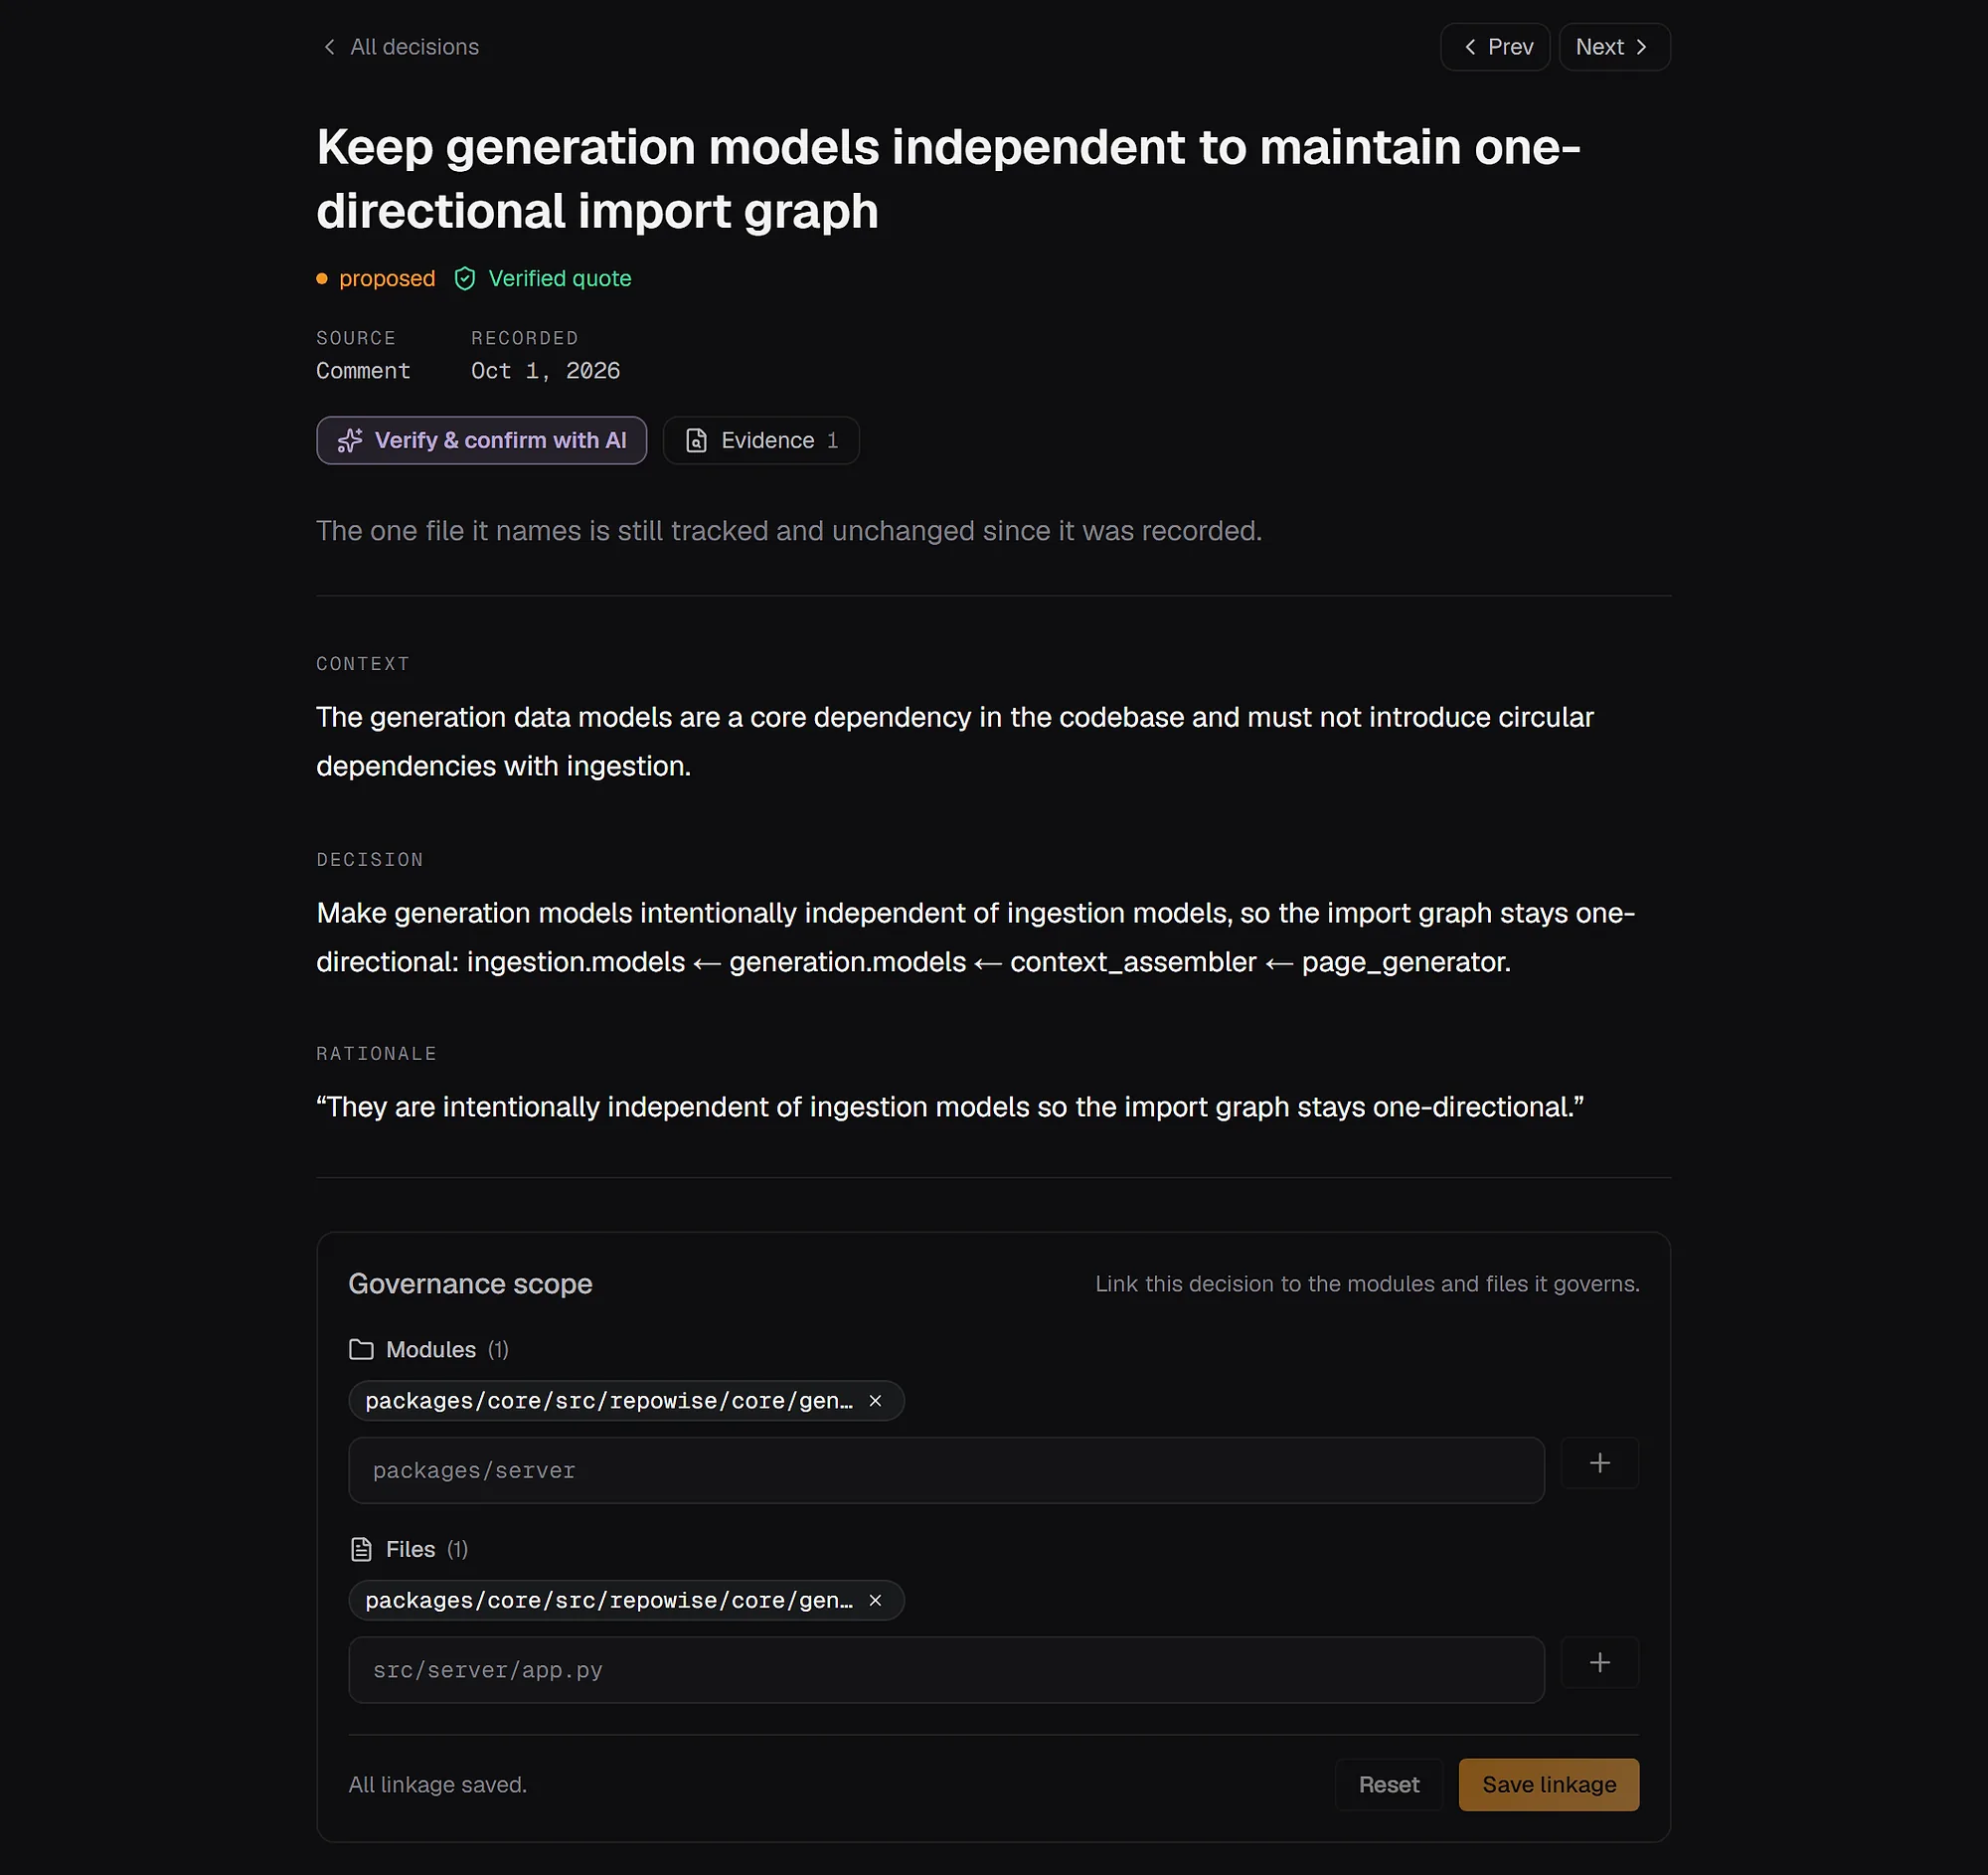
get_why(query="why do we retry webhooks in a queue?")
get_why(query="src/billing/webhooks.py")
A decision record names the files it governs, so the new hire sees the constraint on the page they are about to edit. That turns a fast first commit into a safe one. See decision records in repowise for how they are captured and confirmed.
Day 21 to 30: change safely, with owners and blast radius
Before the first pull request, check what the change touches and who knows the area. get_risk on a file returns its churn, owners, bus factor and bug-fix history. With changed_files=[...] it returns what the set could break and which tests to run. get_health scores the files you touched, and get_change_risk scores a commit or diff range once the change exists.
Ownership comes from git history: who wrote the most, who touched it recently, and where knowledge is thin. A new hire learns whom to ask for review before they open the PR, and the answer comes from the repository rather than from a guess.
| Window | Goal | What the engineer does | Tool |
|---|---|---|---|
| Days 1 to 3 | Orient | Read the architecture map and the guided tour | get_overview |
| Days 4 to 10 | Locate | Find the modules and symbols the first tickets touch | search_codebase, get_context, get_answer |
| Days 11 to 20 | Understand intent | Recover the reasoning behind code they must change | get_why |
| Days 21 to 30 | Change safely | Check blast radius, owners and health before a PR | get_risk, get_health, get_change_risk |
Scroll the table sideways to see every column.
The calendar is a guide. The sequence is the point: an engineer who checks owners and blast radius first ships a smaller first change and earns trust faster than one who guesses.
One map for the engineer and their coding agent
repowise indexes once and serves the result two ways: as a wiki a person reads, and as ten MCP tools an agent calls. A new hire working with Claude Code, Codex or Cursor gets the same grounded context inside the editor, so the agent does not guess at structure from file names.
That context is also cheap to deliver. Loading one commit's context through repowise uses 35.6x fewer tokens than a naive full-file dump (a single-payload measurement), and in a real agent loop against a bare-agent control it holds up as a measured 31.6% fewer output tokens on Codex. The method is on the benchmarks page.
Latest result: agents open up to 99% fewer files with repowise and write up to 51.2% less (Sonnet 4.6), every model tested opened fewer files, and the newest flagship, Opus 5.5, got 48 of 48 answers right (benchmarks).
The wiki and index are rebuilt on repowise update, so they follow the code. And because repowise is open source under AGPL-3.0, a team that cannot send code to a third party can run the whole pipeline in-house and still hand every hire a current map. The repowise for developers page covers the day-to-day workflow.
Keep reading
- Developer onboarding with codebase intelligence: why traditional onboarding fails and what replaces it.
- Best tools for onboarding engineers: the 2026 comparison.
- Best tools to understand a legacy codebase: the day-one sequence for an inherited system.
- How to read a codebase you did not write: a repeatable audit workflow.
FAQ
- How do you onboard an engineer to a new codebase quickly?
- Give them context in a fixed order: an architecture map first, then the files their first tickets touch, then the reasoning behind the code they must change, then owners and blast radius before the pull request. repowise generates each of these from the repository, so none of it depends on a senior engineer's time.
- How do you onboard onto a codebase with no documentation?
- Do not wait for documentation to exist.
repowise initbuilds an overview, module pages and an architecture graph from the source, so a repo with no README still gets a current map. For the reasoning behind code,get_whyfalls back to git archaeology and rationale comments when no decision records exist. - What is the fastest way to understand legacy code?
- Orient before you edit. Read the structure and entry points, then recover the intent behind the specific code you will change, then check its owners and fix history. The legacy codebase guide walks through that sequence.
- Does repowise work on a polyglot monorepo?
- Yes. repowise parses 28 languages to a full AST and builds one dependency graph and one wiki across them, with 15 languages at the Full tier for the deepest analysis. A new hire sees one map of the system rather than one per language.
- Can we self-host repowise for onboarding if our code cannot leave the company?
- Yes. repowise is open source under AGPL-3.0, and indexing, the wiki and the MCP server run locally. Git-derived signals such as ownership and risk need no LLM key.