On this page
- How does repowise run on its own codebase?
- Why can agent-written code be gated deterministically?
- What changes day to day
- What the public benchmarks measured
- Loading one commit's context
- Agent sessions on a real repository
- Distilling command output
- The health score that gates our pull requests
- Reproduce it on your repo
- FAQ
We build repowise with repowise: the repo is indexed by its own product, agent sessions query that index through MCP, and every pull request is scored by the same deterministic risk and health checks that ship to users. This case study covers the setup, what each piece does day to day, and the public benchmark numbers behind the workflow.
One rule shapes how we write about it: efficiency numbers come from public repositories, never from our own. We know our codebase too well and tune our index too closely, so any figure measured there would be a best case. The workflow is described here; the measurements come from corpora you can rerun.
How does repowise run on its own codebase?
Four pieces sit on top of the index in every working session. The repowise monorepo is a Python core with a TypeScript UI, spread across the architectural layers.
- A generated CLAUDE.md.
repowise initwrites the orientation block loaded at session start: architecture summary, key modules, entry points, files that need care with their bug-fix history, and current health scores. When the index updates, the block updates. It is the file the CLAUDE.md generator produces for any repo. - MCP tools over the index. The agent queries instead of walking the tree:
get_answerfor how, where and why questions,get_contextfor a triage card on a file it is about to edit,get_symbolfor one verified source range,search_codebasefor hybrid search,get_riskbefore touching a hotspot, andget_whybefore diverging from an established pattern. The full set is ten tools, listed in the MCP tools reference. - Output distillation. Tests, builds and
git logrun throughrepowise distill, which keeps every error line, puts errors first, and stores the raw output sorepowise expandrestores anything omitted. - The PR bot and health gate. Every pull request gets a risk and health report before review, and each push gets a repowise review check. Signals mode is deterministic; AI review adds a model read on top of the same signals.
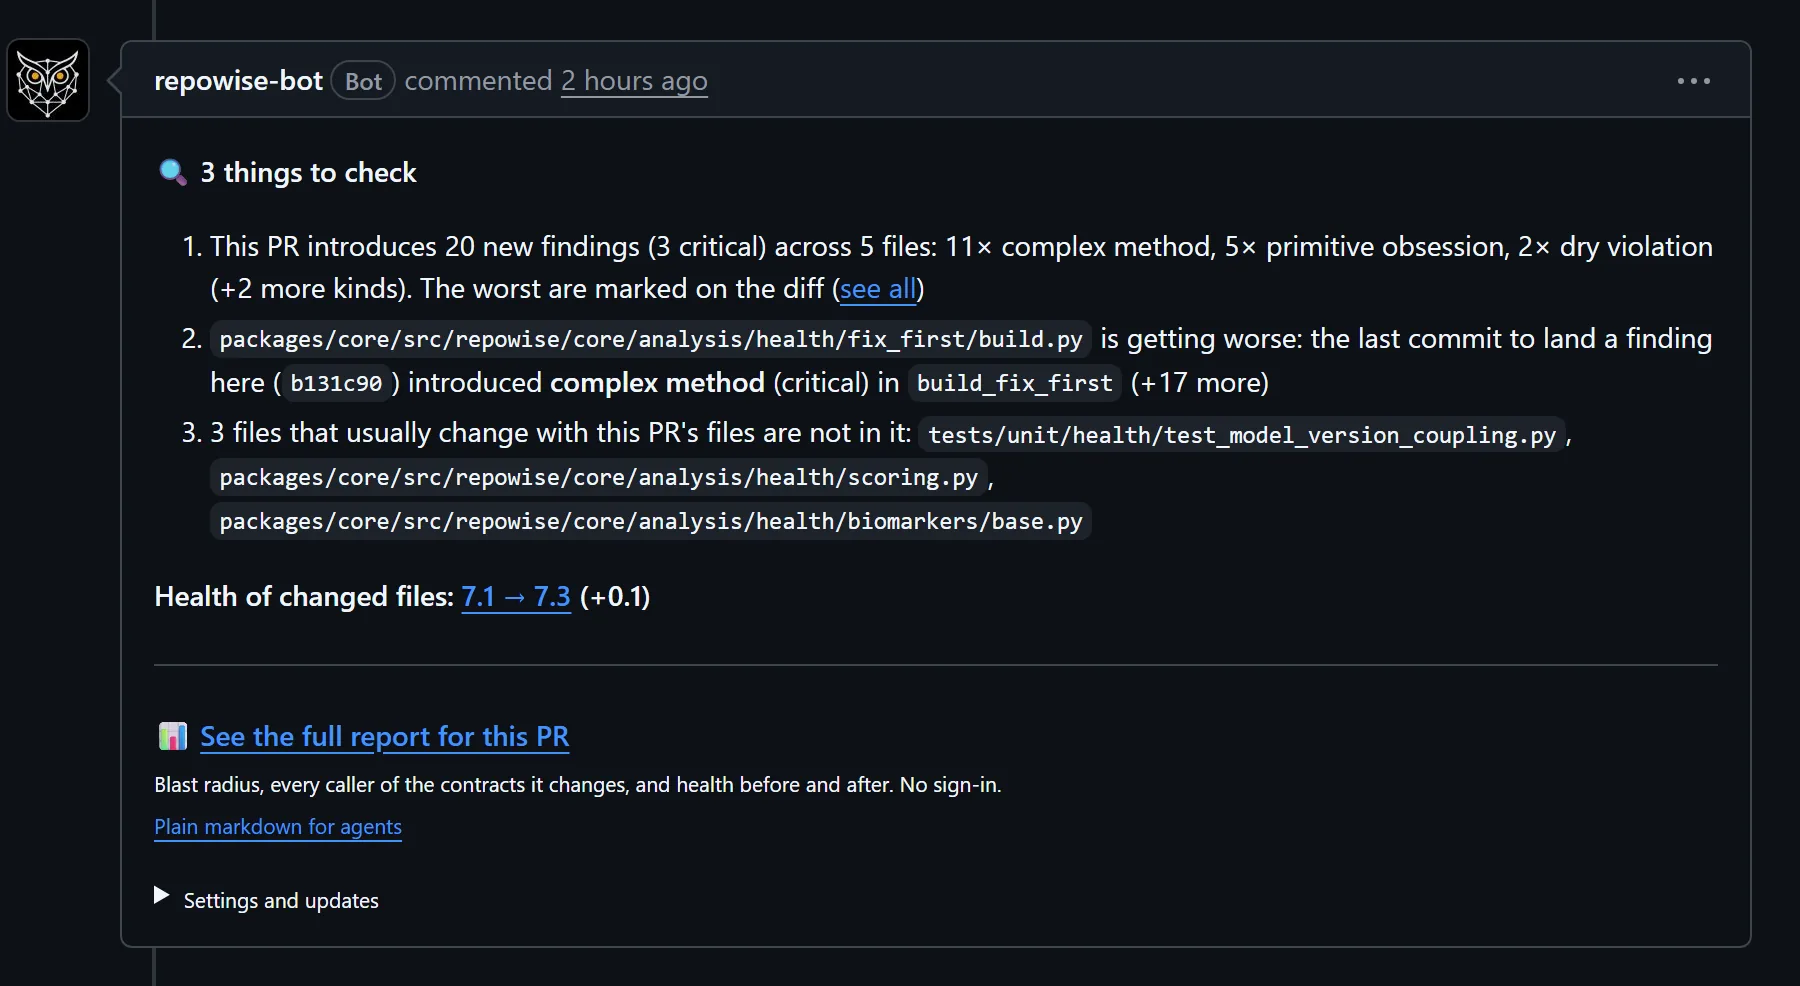
A repowise-bot comment on a pull request to the repowise repository: new findings grouped by kind, co-change partners the diff left out, and the health of the changed files before and after.
Why can agent-written code be gated deterministically?
The checks that gate a pull request involve no model, so the same input always produces the same score. A large share of this repo is written in agent sessions. That is defensible only when the controls around it are at least as strong as for hand-written code, and the ones that matter here cannot be talked around.
- Risk and health checks are deterministic. No LLM scores them. The gate cannot be flattered or prompted into agreement.
- Tests, types and lint gate merges the ordinary way. The agent workflow replaced none of them.
- The benchmark harness is public. Anyone can run it and check the claims on this page.
A change written by an agent and a change written by a person pass or fail the gate on identical terms.
What changes day to day
Orientation, risk and cleanup all move earlier in the loop. The benchmarks below measure single tasks. On our own repo the compounding effects are the point.
- Orientation is free. A session starts already knowing which files in the analysis package carry the most churn and bug-fix history. Nobody re-derives the architecture each morning.
- Risk arrives before the edit. Change risk flags hotspot files and likely co-changes when a change is proposed, while acting on it is cheap.
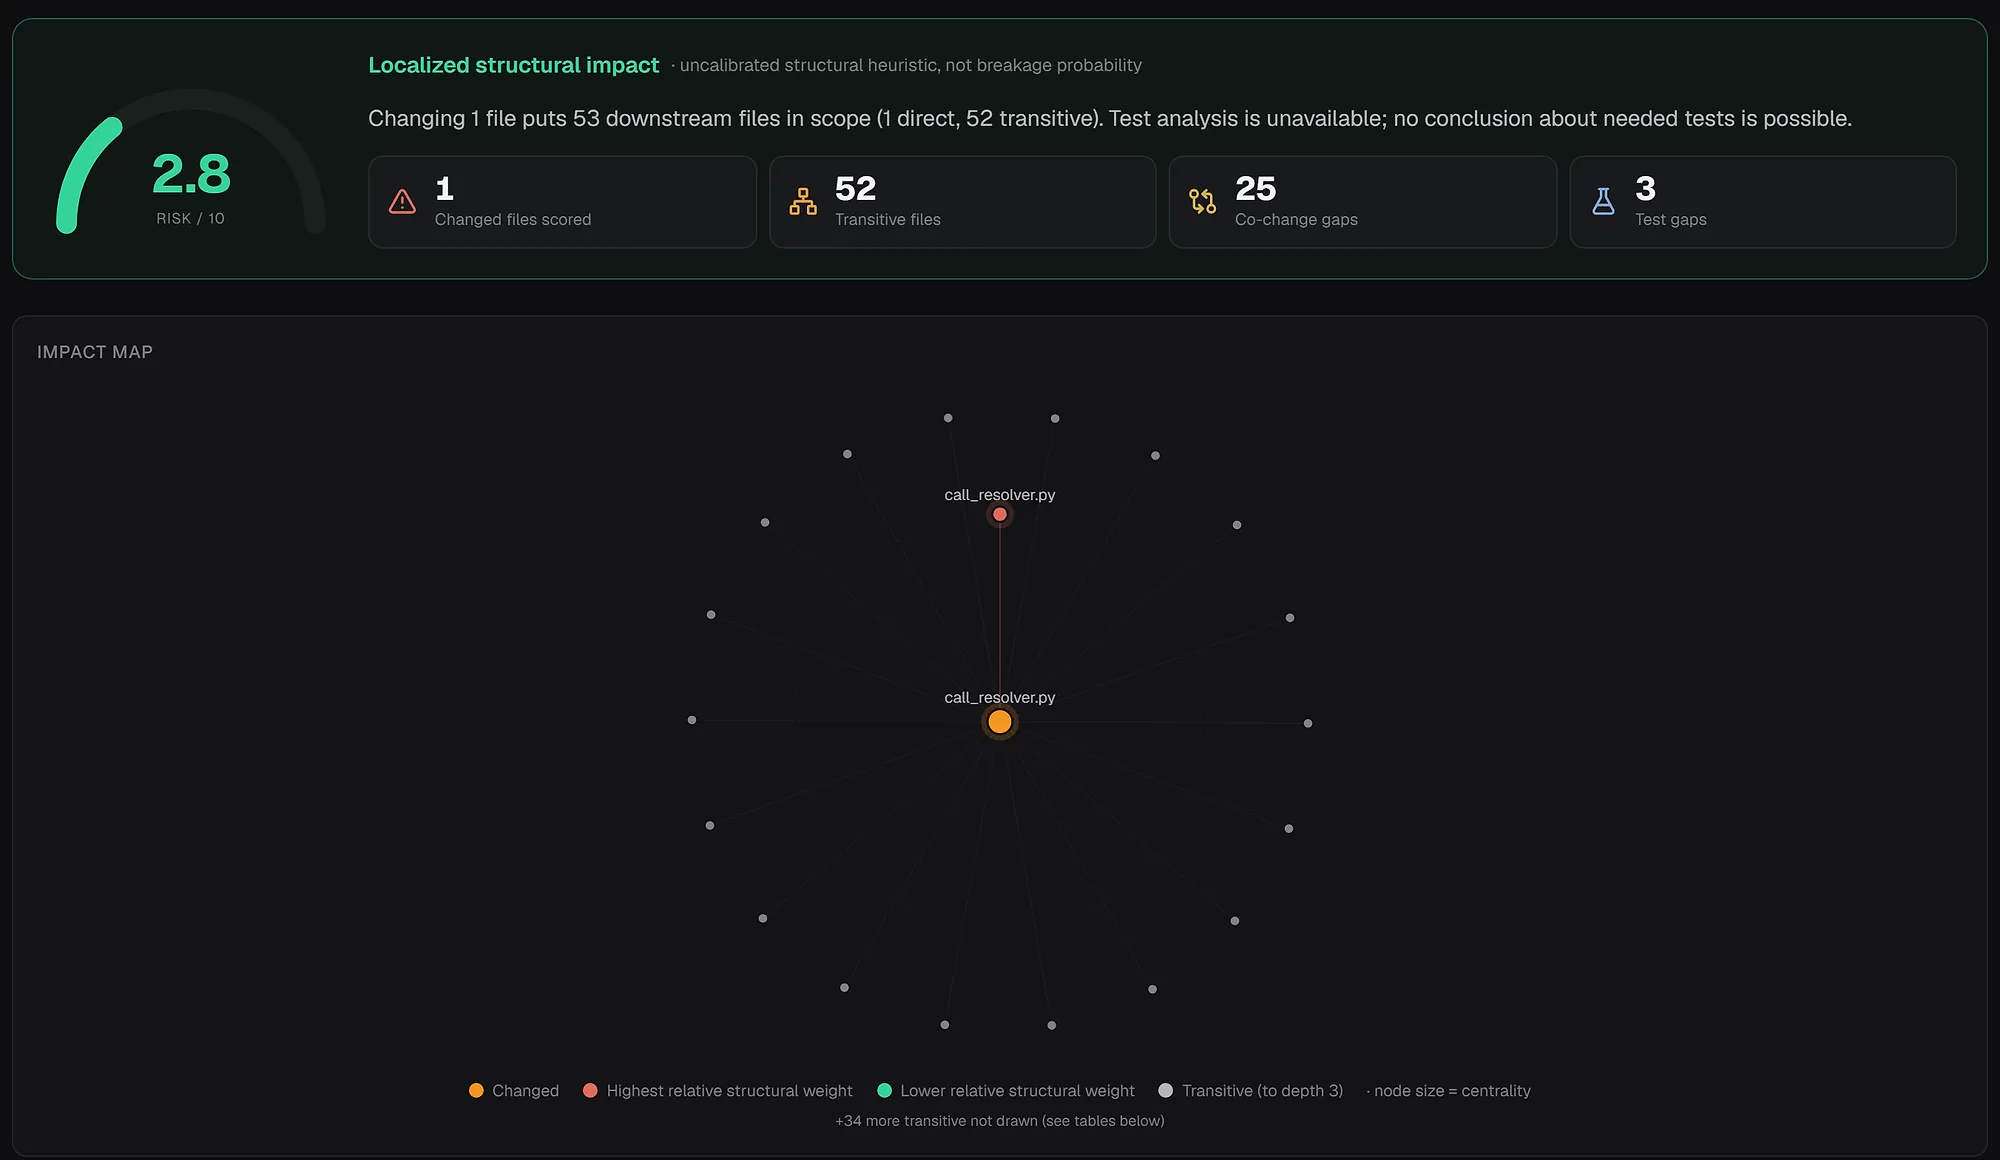
The blast radius view for a change to call_resolver.py in the repowise repository: direct and transitive dependents, co-change gaps, and the impact map.
- We meet our own findings first. The health gate runs on our PRs before it runs on yours, on a repo we know well enough to tell a sharp finding from a noisy one. That feedback loop is why detectors get tuned against real code.
What the public benchmarks measured
Measured on public repositories, repowise cuts the tokens an agent spends reaching an answer. Every figure below comes from the benchmark page, which links the harness, configs and raw results. Two identical agents get identical tasks; the only variable is whether the repowise MCP tools are available.
Loading one commit's context
On the 30 most recent non-merge commits of pallets/flask, get_context needed 393 tokens per commit, 35.6x fewer than reading every changed file and 3.6x fewer than git diff alone, pooled.
The measurement almost every tool in this category publishes, labelled as such. Counted with deterministic tiktoken over the 30 most recent non-merge commits of pallets/flask.
| Strategy | Tokens per commit |
|---|---|
| naive, full contents of every changed file | 13,984 |
| git diff only | 1,408 |
| get_context | 393 |
Scroll the table sideways to see every column.
35.6x fewer than naive pooled, 29.3x as a mean of per-commit ratios, and 3.6x pooled against git diff. This is one payload, not a session. It says our representation of a commit is smaller than the commit; it does not say an agent finishes faster.
Agent sessions on a real repository
On Codex, over 37 of 44 questions on Django, the agent with repowise used 31.6% fewer output tokens than the bare agent and made 3.8 tool calls to reach an answer. The result held on a second harness: Claude Code used 15.9% fewer, and a local model with local-only tools used 47.9% fewer.
Every question in django's question set, six arms, byte-identical prompts, each tool's full advertised surface, and a freshly built index on the same pinned commit. Every tool was called on every question, so this is like for like.
| Tool | Agent used it | Output tokens | vs bare agent | Tool calls | Leaner on | p |
|---|---|---|---|---|---|---|
| repowise | 44 / 44 | 1,250 | -31.6% | 3.8 | 37 of 44 | <0.0001 |
| CodeGraph | 44 / 44 | 1,383 | -24.4% | 4.0 | 37 of 44 | <0.0001 |
| Serena | 43 / 43 | 1,550 | -14.8% | 10.1 | 35 of 43 | <0.0001 |
| Graphify | 43 / 43 | 1,658 | -8.9% | 7.4 | 31 of 43 | 0.003 |
| code-review-graph | 43 / 43 | 1,710 | -6.0% | 7.2 | 26 of 43 | 0.046 |
| bare agent (control) | 0 / 44 | 1,828 | baseline | 7.2 | n/a | n/a |
Scroll the table sideways to see every column.
Codex (gpt-5.6-sol) on django/django at one pinned commit. Correcting for testing five tools at once, three reductions are solid and two are marginal. 5 of the 48 questions are missing from every arm equally because the run hit an API usage cap, so the figures are over the 43 questions all six arms completed; because all arms lost the same 5, the paired comparisons are unaffected.
The saving is larger on harder questions: 34.3% on the harder half of the question set. Conditions for the headline figure: n = 43 · p = <0.0001 · Codex (gpt-5.6-sol) · django/django at a single pinned commit · 2026-08
Distilling command output
On long investigation tasks the win comes from output distillation. On single commands, repowise distill saved 61% of tokens on a pytest run with 11 failures and 89% on git log -50, with every error line preserved.
The health score that gates our pull requests
The repo carries a live health badge, served from the same index this page describes. It reads the current average code health, and it is the number to trust over any figure typed into prose.
 Code health badge for repowise-dev/repowise
The score is validated against defects. Across 21 open-source repositories, 9 languages and 2,826 labeled files, it ranks files that go on to receive bug fixes with a ROC AUC of 0.74, 95% confidence interval 0.68 to 0.79, ranging from 0.55 to 0.86 across individual repos. In plain terms, it ranks a file that later needed a bug fix above a clean one about three times in four. Read the full method on the benchmarks page.
Reproduce it on your repo
The fastest check is your own repository. Index it with repowise init, which needs no API key for the first index, then ask it a question your team keeps answering by hand.
pip install repowise
cd your-repo
repowise init
repowise distill pytest -x
repowise saved
repowise saved reports the tokens and dollars distillation has saved so far. To see the output on a codebase you already know first, browse the pre-indexed open-source repos. Everything measured above lives in the public benchmark repository, and the token-efficiency script takes any git repo as input.
FAQ
- Are the benchmark numbers measured on the repowise codebase?
- No. The token-efficiency and agent-loop benchmarks run on public repositories (Flask and Django) so anyone can reproduce them. The repowise codebase is where we use the tool daily; the public corpora are where we measure it.
- If agents write the code, why trust the checks?
- The checks are deterministic and involve no model. Risk and health scores are computed from the same input every time, and the health score is validated against a public defect corpus. An agent's change and a person's change pass or fail the gate on identical terms.
- Why a live badge instead of a quoted score?
- A score typed into a page is correct on the day it is written and stale after. The badge reads the live index, so it moves when the codebase moves. The score itself is defect-validated with a published confidence interval.
- Can I run the benchmark on my own repository?
- Yes. The harness, configurations and analysis scripts are in the public benchmark repository, and the token-efficiency script accepts any git repo.
- Does this require Claude Code?
- No. The index is exposed over the Model Context Protocol, so it works with Claude Code, Cursor, Cline, Codex and any other MCP client. One index serves every agent.